<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://gwenneg.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://gwenneg.github.io/" rel="alternate" type="text/html" /><updated>2026-09-06T12:36:11+02:00</updated><id>https://gwenneg.github.io/feed.xml</id><title type="html">Gwenneg’s blog</title><subtitle>Gwenneg&apos;s blog</subtitle><author><name>Gwenneg Lepage</name></author><entry><title type="html">Take soundings before you ship</title><link href="https://gwenneg.github.io/2026/09/03/take-soundings-before-you-ship.html" rel="alternate" type="text/html" title="Take soundings before you ship" /><published>2026-09-03T00:00:00+02:00</published><updated>2026-09-03T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/09/03/take-soundings-before-you-ship</id><content type="html" xml:base="https://gwenneg.github.io/2026/09/03/take-soundings-before-you-ship.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/take-soundings-before-you-ship/header.png" alt="Take soundings before you ship" width="800px"></span></p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>I lead a Red Hat engineering team responsible for shipping multiple cloud services to production.
Every week we make a call: is this deployment safe to ship?
When it isn&#8217;t, our job is to catch the risks and mitigate them before they reach production.
The end goal never changes: keep production stable and reliable, with zero customer disruption.</p>
</div>
<div class="paragraph">
<p>What has changed is the volume.
AI now generates and touches code at a rate no human review process was built for.
Diffs grow, release cadence accelerates, but reviewing everything carefully doesn&#8217;t scale.
The only review that scales with AI is AI: a reviewer that reads everything, with judgment, before anything ships.</p>
</div>
<div class="paragraph">
<p>That reviewer is <a href="https://github.com/gwenneg/soundings" target="_blank" rel="noopener">Soundings</a>, a Claude Code plugin I built.
The name comes from an <a href="https://en.wikipedia.org/wiki/Depth_sounding" target="_blank" rel="noopener">old sailors' practice</a>: measuring the water&#8217;s depth ahead before committing a ship to a course, "taking soundings".
This post explains what the plugin does, why I think you should try it on your next release, and why it is safe to run on your laptop even though its job is to read text it has no reason to trust.</p>
</div>
<div class="admonitionblock important">
<table>
<tr>
<td class="icon">
<i class="fa icon-important" title="Important"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Red Hat associates: this post is about the general-purpose Soundings plugin.
To analyze the deployment MRs you ship through app-interface, pair it with the <a href="https://github.com/gwenneg/soundings-app-interface" target="_blank" rel="noopener">soundings-app-interface</a> adapter.
I&#8217;ll publish a dedicated post about that adapter soon.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-soundings-does">What Soundings does</h2>
<div class="sectionbody">
<div class="paragraph">
<p>In your Claude Code session, point Soundings at one or more GitHub or GitLab compare URLs:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/soundings:analyze https://github.com/org/repo/compare/v1.0...v1.1</code></pre>
</div>
</div>
<div class="paragraph">
<p>It reads the diffs, the commit messages, the PR and MR comments, and the repository documentation.
Then it hands back one clear verdict (release, manual review, or no-go) and a report specific enough to act on: named files, named functions, concrete failure modes, and action items sorted by urgency.
Before it starts, it asks where to save the report, unless you already said so:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/soundings:analyze https://github.com/org/repo/compare/v1.0...v1.1 save the report to ./reviews/v1.1.md</code></pre>
</div>
</div>
<div class="paragraph">
<p>A few minutes after you hit enter, the verdict shows up right in your session: the summary, the recommendation, and what drove it.
The full report is the markdown file, written by the helper, ready to archive or to post where the ship decision happens.</p>
</div>
<div class="paragraph">
<p>The verdict follows a fixed policy: by default, any critical concern blocks the release and any high concern requires manual review.
Every concern is a concrete claim you can go verify, so if the verdict feels wrong, you can check which concern caused it and whether that concern is true.
You can also tighten the policy and block on high or even medium concerns for your most critical services.</p>
</div>
<div class="paragraph">
<p>There is nothing to deploy and no LLM API key to create: the analysis runs in the Claude Code session you already have.
A small open-source Go helper does the deterministic work, borrowing the Git credentials you already use: a <code>gh</code> or <code>glab</code> login, or a platform token.</p>
</div>
<div class="paragraph">
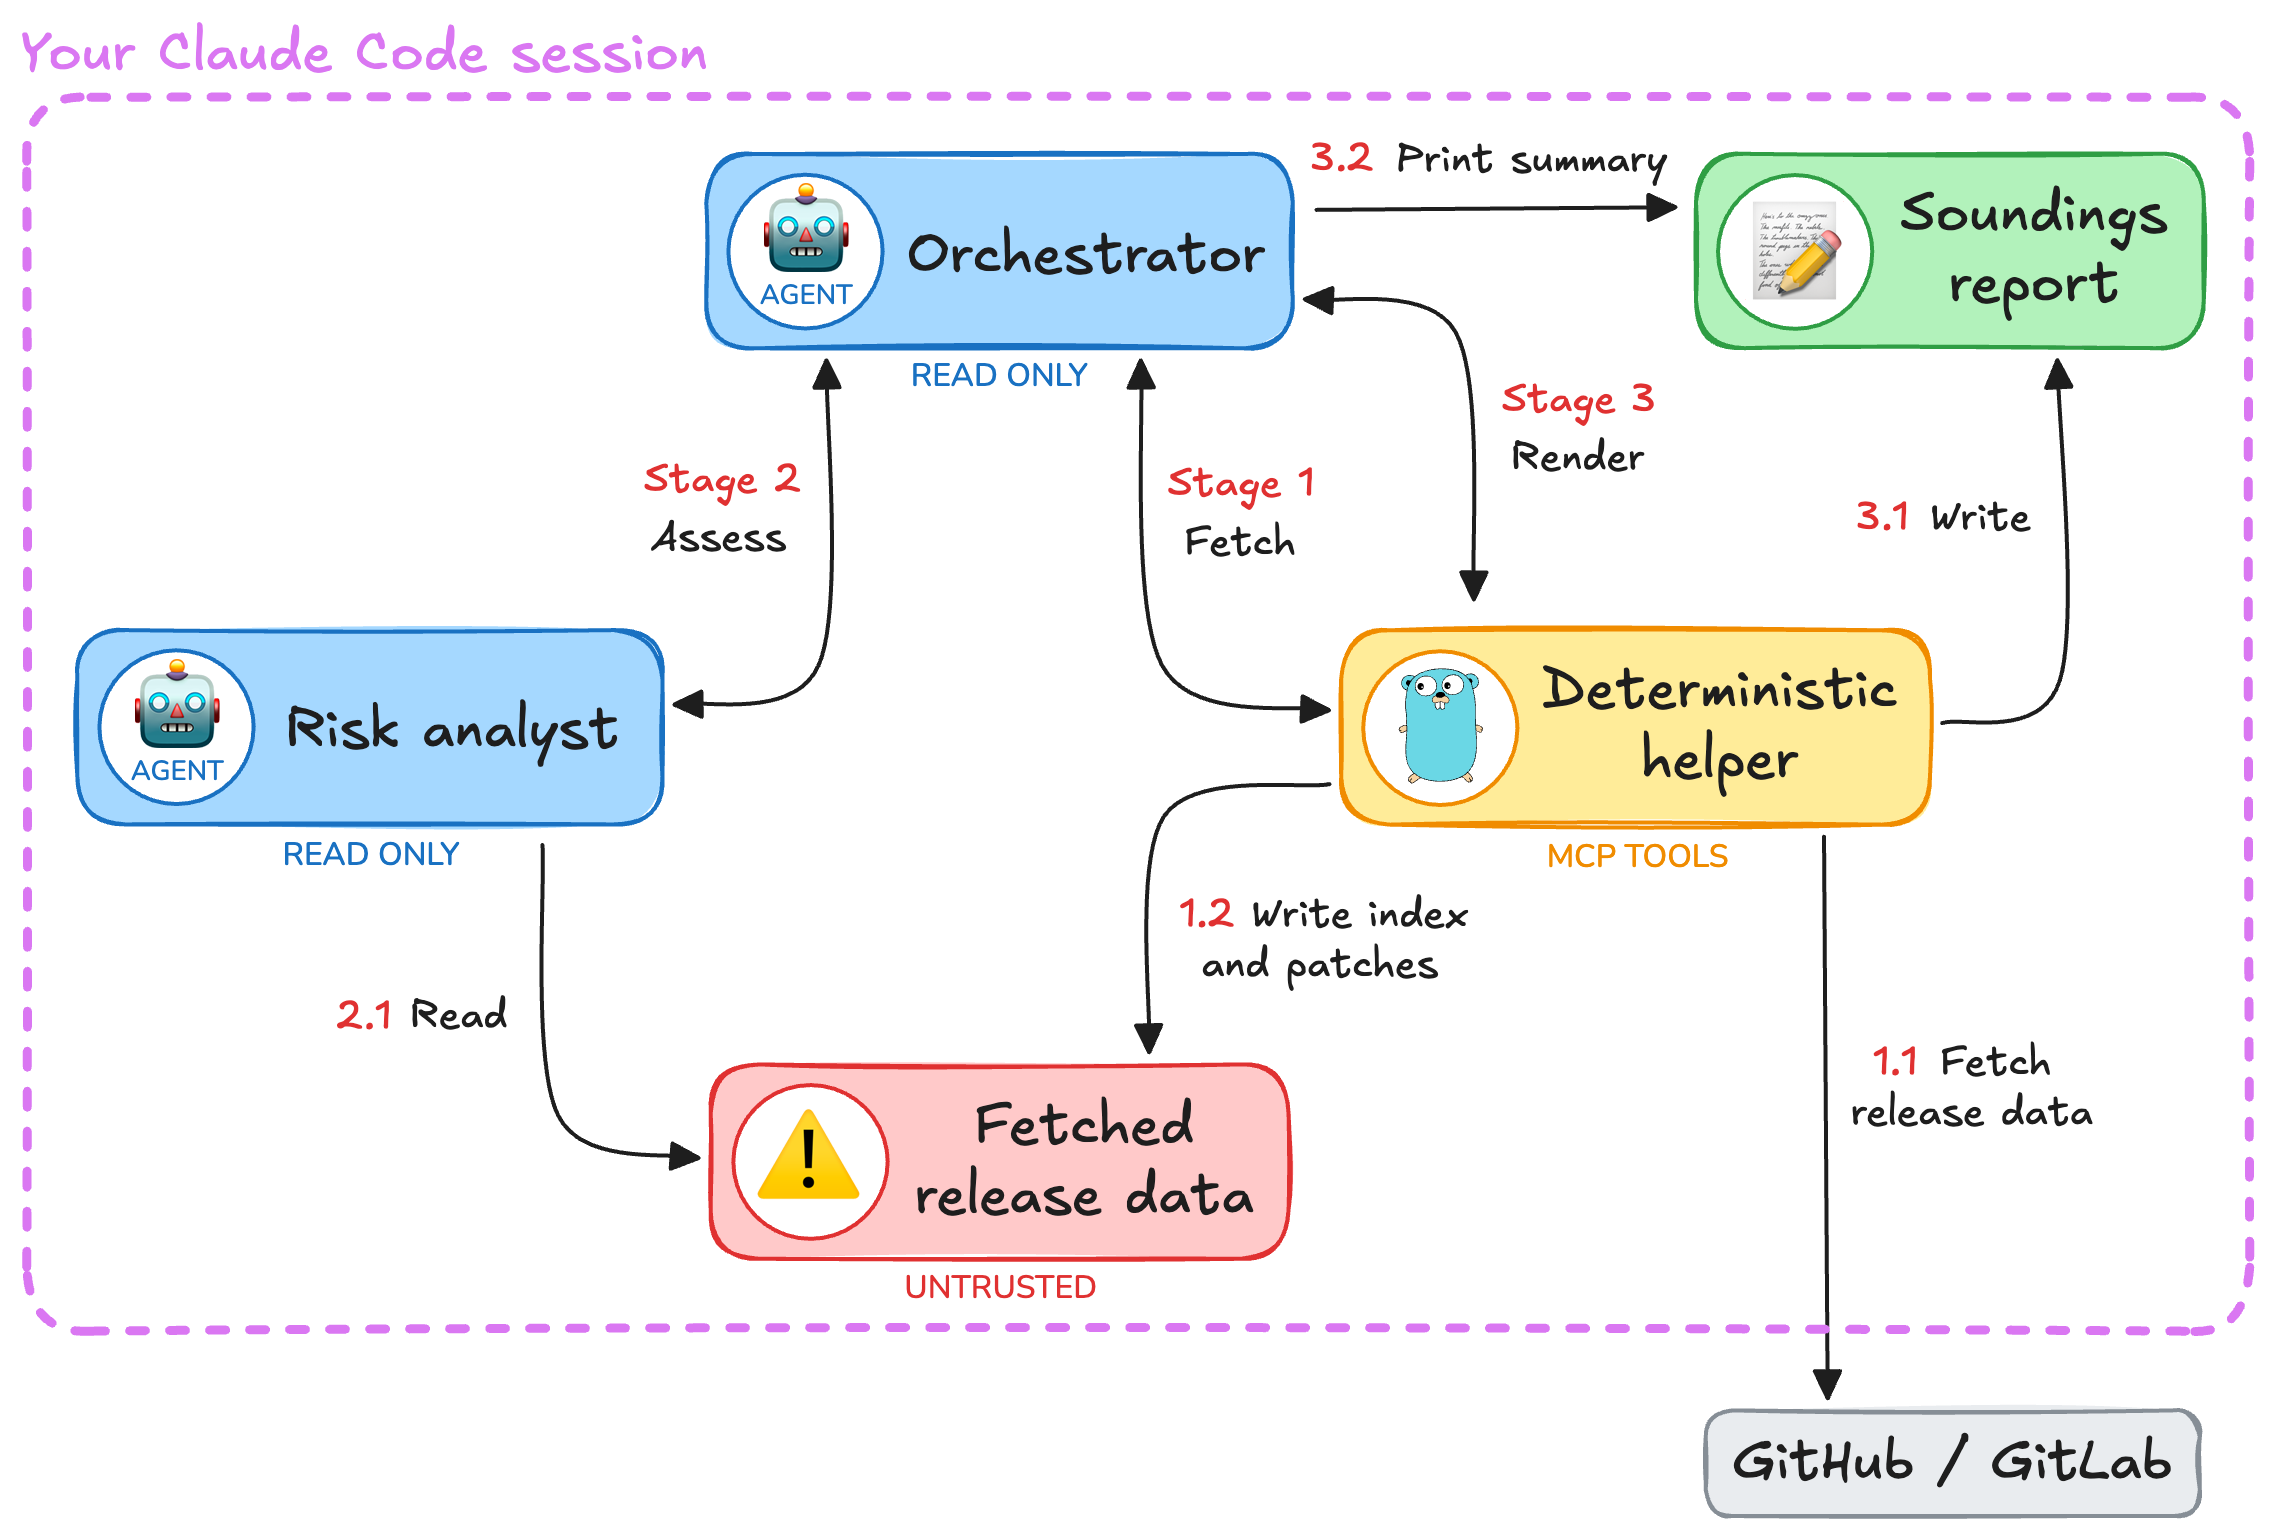
<p>A run has three stages:</p>
</div>
<div class="olist arabic">
<ol class="arabic">
<li>
<p><strong>Fetch.</strong>
The Go helper clones the repositories, computes the diffs locally, and writes per-file patches into a temporary directory it owns, with an index describing how much each file changed and its risk tier.
It returns only counts and paths, never content.</p>
</li>
<li>
<p><strong>Assess.</strong>
An isolated subagent called <code>risk-analyst</code> decides how deeply to read each file instead of cutting every diff to a fixed size: database, auth, and API contract changes are always read in full, tests only when they back up a claim about coverage.
It assigns each concern an evidence-based severity, the higher one when evidence is incomplete, and returns one structured JSON analysis.</p>
</li>
<li>
<p><strong>Render.</strong>
The helper validates that JSON against a schema, computes the verdict from the severities and the blocking policy, renders the report, and writes it to the file you chose.
When it succeeds, the fetched data is deleted.</p>
</li>
</ol>
</div>
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/take-soundings-before-you-ship/what-soundings-does.png" alt="What Soundings does" width="85%"></span></p>
</div>
<div class="paragraph">
<p>You can pass several compare URLs in one invocation, and they are analyzed together.
A coordinated deployment usually spans repositories.
The schema migration lives in one service, the code that depends on it in another.
Per-repo CI can never see that interaction.
A single analysis across all the repos of a deployment can, and compound risks are what Soundings hunts for.
For a team shipping coordinated deployments every week, this is the feature that matters.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-a-report-looks-like">What a report looks like</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Soundings looks for the risk families you would brief a new release manager on:</p>
</div>
<div class="ulist">
<ul>
<li>
<p><strong>Database changes</strong>: migration ordering, rollback traps, locks taken under load</p>
</li>
<li>
<p><strong>Security</strong>: secrets in diffs, auth changes, new logging on sensitive paths, risky dependency updates</p>
</li>
<li>
<p><strong>API contracts</strong>: breaking changes, services no longer agreeing on request and response shapes</p>
</li>
<li>
<p><strong>Infrastructure and configuration</strong>: deployment and CI changes, resource limits, config changes paired with the code that reads them</p>
</li>
<li>
<p><strong>Resilience</strong>: retry, timeout, rate limit, circuit breaker, and connection pool changes, which all shift capacity and failure modes</p>
</li>
<li>
<p><strong>Compound risks</strong>: changes that are each fine alone but dangerous together, including across repositories</p>
</li>
</ul>
</div>
<div class="paragraph">
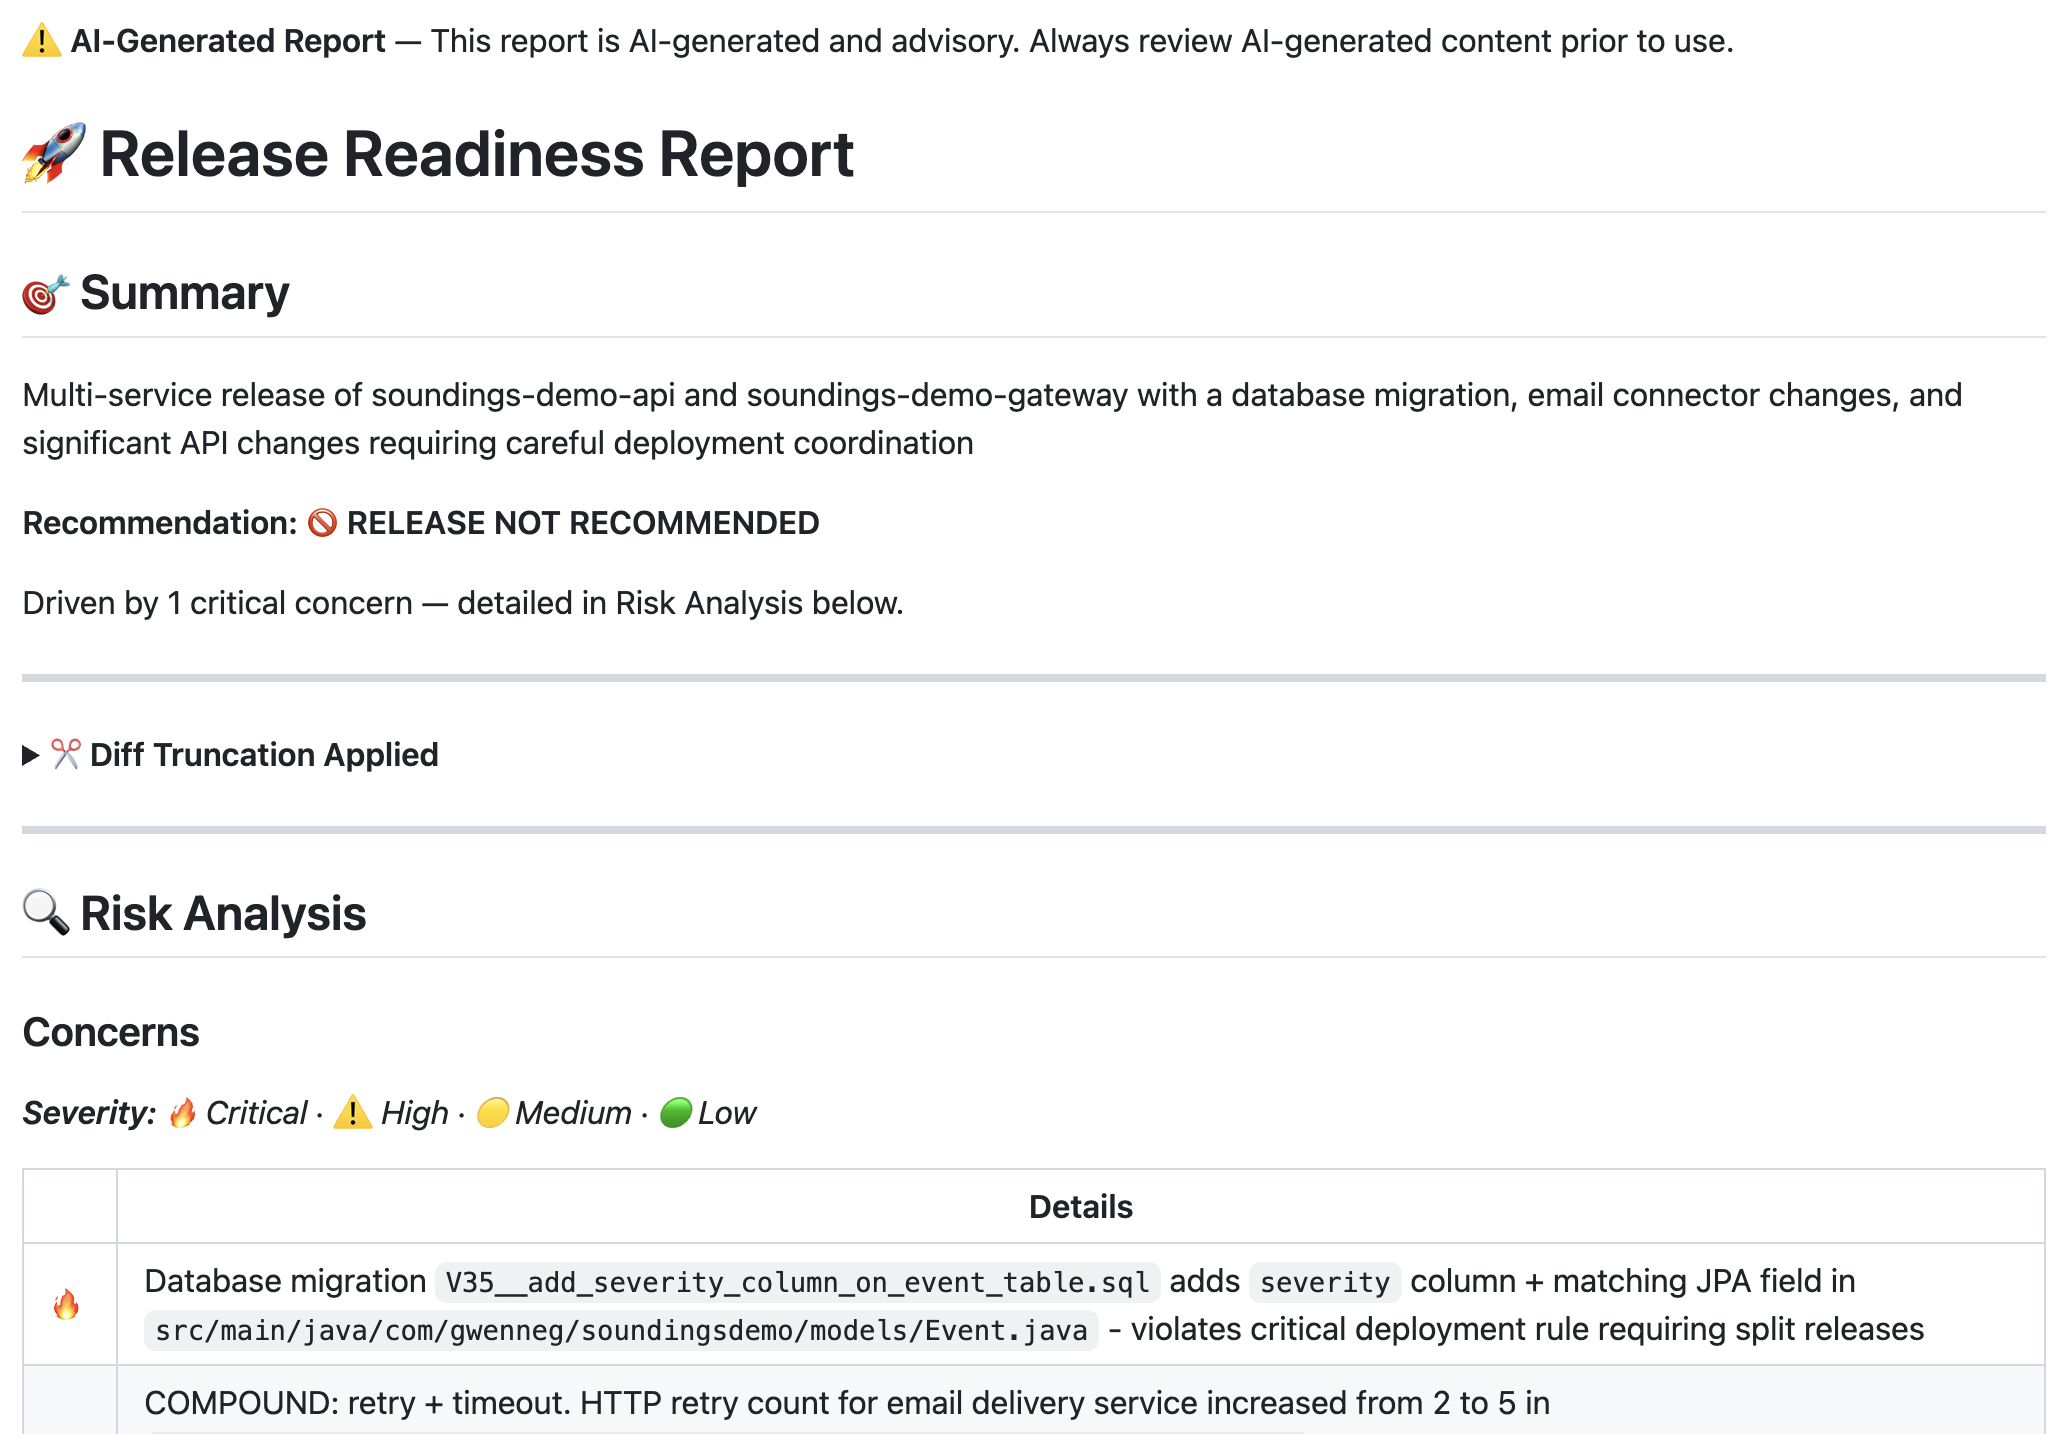
<p>Your session shows only the Summary section.
The full report is in the markdown file.
Here&#8217;s the top of one, from a demo analysis of a two-service release:</p>
</div>
<div class="paragraph">
<p><span class="image bordered"><img src="/assets/images/posts/take-soundings-before-you-ship/soundings-demo-report.png" alt="Soundings demo report" width="85%"></span></p>
</div>
<div class="paragraph">
<p>You can read the <a href="https://github.com/gwenneg/soundings/blob/main/docs/DEMO_REPORT.md" target="_blank" rel="noopener">full demo report</a> to see everything it contains.</p>
</div>
<div class="paragraph">
<p>Two findings from that report stand out.
The critical one caught a database migration and the code using its new column shipping in the same release, a sequence the service&#8217;s own deployment rules forbid.
Its action item: block the deployment and split the release, migration first, code second.
The compound one caught a retry count raised from 2 to 5 in one file and a timeout raised from 200ms to 1s in another.
Each change is fine alone.
Combined, the worst case blows past the service&#8217;s 2 second SLO when the email service degrades.
No single-file review connects those two lines.</p>
</div>
<div class="paragraph">
<p>The positives are evidence-based too, and just as specific.
The same report credits the release for a feature flag guarding the new endpoint, an <code>IF NOT EXISTS</code> guard on the migration, a documented rollback path, and a gateway change verified compatible with both the old and new versions of the API behind it.
That last one is only visible because the two repositories were analyzed together.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="try-it-on-your-next-release">Try it on your next release</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Here&#8217;s the complete setup on a machine that already runs Claude Code:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace add gwenneg/claude-ichiba <i class="conum" data-value="1"></i><b>(1)</b>
/plugin install soundings@claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Full disclosure: <a href="https://github.com/gwenneg/claude-ichiba" target="_blank" rel="noopener">claude-ichiba</a> is my own plugin marketplace.
It also hosts <a href="https://github.com/gwenneg/ai-mentor" target="_blank" rel="noopener">AI Mentor</a>, the plugin from <a href="/2026/07/13/which-80-percent-of-claude-code-are-you-missing.html" target="_blank" rel="noopener">an earlier post</a> that teaches you the Claude Code capabilities you&#8217;re missing.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>You need two things besides Claude Code: a Go toolchain, and a credential for each platform you analyze, either a <code>gh</code> or <code>glab</code> login or a <code>GITHUB_TOKEN</code>/<code>GITLAB_TOKEN</code> env var.
That&#8217;s it.
No LLM API key, no service account, no Docker image, no config file.
At run time, Soundings picks the right credential for each platform and each GitLab host, so one invocation can mix github.com and any number of GitLab instances, and a token for one host is never sent to another.</p>
</div>
<div class="paragraph">
<p>Claude Code only updates plugins from its official marketplace automatically.
Enable auto-update for claude-ichiba in the <code>/plugin</code> panel, or refresh it yourself from time to time:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace update claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="why-its-safe-to-run-on-your-laptop">Why it&#8217;s safe to run on your laptop</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Everything Soundings analyzes (diffs, commit messages, PR comments, repository docs) could have been written by anyone.
Even your own release carries text you didn&#8217;t write: other people&#8217;s code, bot commits, comments from anyone with an account.
So the design assumes every byte it fetches is hostile, and the protections are limits the AI cannot cross, not instructions it is asked to follow.</p>
</div>
<div class="sect2">
<h3 id="what-a-run-talks-to">What a run talks to</h3>
<div class="paragraph">
<p>Those limits start at the network.
A run adds no channel of its own: no extra LLM API, no telemetry, no server collecting anything.
It only reaches the platforms that host your code, and the analysis stays in your existing Claude Code session, like the rest of your work.</p>
</div>
<div class="paragraph">
<p>Even that traffic never comes from the AI: the fetching is done by a Go helper with an SSRF-hardened HTTP client.
The client blocks connections to private and internal addresses at dial time, covering redirects and DNS rebinding rather than just the initial URL.
A document link planted in a repo cannot make your laptop probe your internal network or a cloud metadata endpoint.
It guards your credentials the same way: a GitLab token is only ever sent to its own host, and gets stripped from any redirect that leaves it.</p>
</div>
</div>
<div class="sect2">
<h3 id="who-gets-to-read-the-data">Who gets to read the data</h3>
<div class="paragraph">
<p>Once the data is fetched, the reading happens in a dedicated subagent called <code>risk-analyst</code>, and each agent in a run gets only the permissions its job needs:</p>
</div>
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 33.3333%;">
<col style="width: 33.3334%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">What</th>
<th class="tableblock halign-left valign-top">Main agent (your session)</th>
<th class="tableblock halign-left valign-top"><code>risk-analyst</code> subagent</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Shell, file edits, network</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Switched off during the run</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Never had them</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Your project files</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Can read them</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Cannot read them*</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">The fetched release data</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Cannot read it*</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">The only thing it can read*</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">The helper&#8217;s <code>fetch</code> and <code>render</code> tools</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Can call them</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Cannot call them</p></td>
</tr>
</tbody>
</table>
<div class="paragraph">
<p>The starred cells all describe the same mechanism: a fence around the fetched data, enforced by a hook the plugin ships.
It exists because read-only is not enough on its own: an injected instruction could still make the AI read <code>~/.ssh</code> or a <code>.env</code> file and leak what it finds into the report.
The hook is backed by a registry of the exact directories the fetch step created, and the two agents sit on opposite sides of the fence: the <code>risk-analyst</code> may read only in there, every other agent may read anywhere but there.
If anything goes wrong with the registry, the hook denies rather than allows.
And the plugin cannot override your own Claude Code settings: anything you&#8217;ve denied there stays denied.</p>
</div>
<div class="paragraph">
<p>The result: a prompt injection buried in a diff reaches only <code>risk-analyst</code>, and can, at worst, change what the analysis says.
It cannot run commands in your session, and the hostile text cannot be pulled into any other agent&#8217;s context.</p>
</div>
</div>
<div class="sect2">
<h3 id="what-comes-out-and-what-remains">What comes out, and what remains</h3>
<div class="paragraph">
<p>What comes out of a run is as controlled as what goes in.
Every file is written by the helper, and it refuses to overwrite anything that is not a previously generated Soundings report.
Recognizable credentials (platform tokens, cloud keys, PEM blocks) are redacted before the analysis is even validated, so a secret that slips into the assessment never reaches the report.
Externally-authored text is escaped in the report, so a crafted comment cannot forge its structure.
And the verdict is computed from the concern severities: flipping it would require fabricating or suppressing a whole concern, in plain sight, in a report a human will read.</p>
</div>
<div class="paragraph">
<p>Nothing stays behind after a run.
The helper owns the fetched data from creation to deletion: a successful render deletes it, a failed fetch cleans up behind itself, and an abandoned run&#8217;s leftovers are deleted the next time the helper starts.
Only the report survives.</p>
</div>
</div>
<div class="sect2">
<h3 id="the-residual-risk">The residual risk</h3>
<div class="paragraph">
<p>One risk remains: a prompt injection can still bias the analysis wording or a concern&#8217;s severity.
That risk is inherent to any LLM-based review, which is why every report opens with an advisory banner and why the footer names the exact model that performed the analysis.
The severity-driven verdict at least forces that bias into the most auditable place there is: a named concern, in a report, right where you will read it.</p>
</div>
<div class="paragraph">
<p>And if you&#8217;d rather verify all of this than trust me: the helper is a small, tested, open-source Go program you can read in an afternoon, and it never runs arbitrary commands.
It runs as an MCP server that does nothing until a tool is called: no credentials read, no network touched.
You can also toggle it off entirely in the <code>/mcp</code> panel.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="getting-better-results">Getting better results</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Two inputs make the analysis noticeably sharper.</p>
</div>
<div class="paragraph">
<p>A <code>.soundings.md</code> file in your repository root tells the analyst what the service is, how critical it is, and where the known risky areas are.
Good candidates: the SLO your callers expect, deployment rules such as "migrations ship in their own release", rollback procedures, and links to your runbooks.
That&#8217;s where the demo&#8217;s blocking concern came from: the analyst read the split-release rule in the repository&#8217;s own documentation and enforced it.
Documentation linked from it is fetched too, SSRF-hardened and size-capped like every other fetch.</p>
</div>
<div class="paragraph">
<p>A <code>/soundings note</code> comment on a PR or MR hands the analysis context a diff cannot show:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/soundings note The new index was tested on a staging copy with production data volume. Creation took 47 seconds, with no lock contention.</code></pre>
</div>
</div>
<div class="paragraph">
<p>Notes only influence the analysis when their author is the PR/MR author or an authorized approver, and that authorization is computed from the platform API, never guessed.
Unauthorized notes are disclosed in the report but excluded from the analysis, so a random commenter cannot change the verdict.
The demo report has an example: a commenter insists the release should ship regardless of the verdict, and the guidance table lists that note as ignored.</p>
</div>
<div class="paragraph">
<p>The full guide lives in the repo: <a href="https://github.com/gwenneg/soundings/blob/main/docs/IMPROVING_ANALYSIS.md" target="_blank" rel="noopener">Improving your release readiness analysis</a>.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="where-soundings-comes-from">Where Soundings comes from</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Soundings is the successor to <a href="https://github.com/RedHatInsights/release-confidence-score" target="_blank" rel="noopener">Release Confidence Score</a>, a tool I originally built at Red Hat, licensed under Apache-2.0.
I extracted its core with the full git history preserved: the original commits, including the security hardening, are visible in the Soundings log.
It is Apache-2.0 too, and the whole pipeline is open to inspection.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-next">What&#8217;s next</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Everything in this post runs interactively, on a laptop, with a human reading the report.
The next step is to remove the laptop.
The entire pipeline (the skill, the isolated analyst, the helper) is designed to also run headless: a containerized Claude Code session analyzing a release unattended, as a step of the release process itself, delivering its report where the ship decision is made.
And because the verdict is computed rather than written, it can serve as a gate in a continuous delivery pipeline: a clean verdict promotes, anything else stops the line and hands the decision back to a human, with the report already explaining why.
That&#8217;s why a normal run already needs no permission prompt, and why the injection containment doesn&#8217;t rely on a human watching: the guarantees that make Soundings safe on your laptop are exactly the ones an unattended run needs.
The only thing a headless run has to provide is where to write the report, since nobody is there to answer the question.</p>
</div>
<div class="paragraph">
<p>I&#8217;m also exploring how to port Soundings to <a href="https://openai.com/codex/" target="_blank" rel="noopener">Codex</a>.
The split at the heart of the design, code for the deterministic work and an isolated agent for the reading, is not specific to Claude Code.
Stay tuned.</p>
</div>
<div class="paragraph">
<p>Soundings is under active development, and feedback directly shapes what changes next: <a href="https://github.com/gwenneg/soundings/issues" target="_blank" rel="noopener">issues and ideas</a> are welcome on the repository.</p>
</div>
<div class="paragraph">
<p>Take soundings before you ship!</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="agents" /><category term="ai" /><category term="claude code" /><category term="plugins" /><category term="release management" /><category term="security" /><summary type="html"><![CDATA[We decide every week whether a release is safe to ship. Soundings is the Claude Code plugin I built to answer that: release, manual review, or no-go.]]></summary></entry><entry><title type="html">Turn an AI you can’t trust into one you can</title><link href="https://gwenneg.github.io/2026/08/01/turn-an-ai-you-cant-trust-into-one-you-can.html" rel="alternate" type="text/html" title="Turn an AI you can’t trust into one you can" /><published>2026-08-01T00:00:00+02:00</published><updated>2026-08-01T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/08/01/turn-an-ai-you-cant-trust-into-one-you-can</id><content type="html" xml:base="https://gwenneg.github.io/2026/08/01/turn-an-ai-you-cant-trust-into-one-you-can.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>I maintain <a href="https://gwenneg.com/2026/07/13/which-80-percent-of-claude-code-are-you-missing.html" target="_blank" rel="noopener">AI Mentor</a>, a Claude Code plugin that teaches developers the AI capabilities they don&#8217;t know exist.
For that to work, every recommendation has to be trustworthy: verified against a curated catalog, never invented.
That claim needed proof, so I built evals: automated tests that run the plugin like a real user would and check its answers for recommendations it shouldn&#8217;t be making.
It took me a month to make them trustworthy, because the evals turned out to give wrong verdicts too.</p>
</div>
<div class="paragraph">
<p>After three weeks, most of what I had built needed rebuilding around something I hadn&#8217;t seen coming.
If you&#8217;re building evals for an AI-powered product, or still deciding whether to, these are the traps I fell into.</p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>No prior evals knowledge is needed to understand this post.
If you&#8217;ve ever written a unit test, most of this will feel familiar.
The parts that won&#8217;t are the lessons.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>In a hurry? Jump to the <a href="#starting-from-scratch">If you are starting from scratch</a> section for a TL;DR of this post.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-is-an-eval-and-why-bother">What is an eval, and why bother?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>A unit test can assert an exact outcome because the code under test is deterministic: the same input produces the same behavior.
An LLM is not deterministic.
Run it twice on the same input and you may get different words, sometimes different decisions.
You can&#8217;t assert equality on that, so an eval asks questions about the AI&#8217;s answer instead: "Is this claim accurate?", "Did it violate a stated rule?".</p>
</div>
<div class="paragraph">
<p>Evals started in research labs, as benchmarks for comparing models (Stanford&#8217;s <a href="https://crfm.stanford.edu/helm/" target="_blank" rel="noopener">HELM</a> is a good example).
The name caught on in 2023, when OpenAI open-sourced its <a href="https://github.com/openai/evals" target="_blank" rel="noopener">Evals framework</a>.
This post follows that framework&#8217;s core idea: write your own evals for your own use case.</p>
</div>
<div class="paragraph">
<p>Any eval suite needs cases and a grader, and, if your product carries state, an environment to run them in.
Mine started simple:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Around 40 test cases, each one about a realistic user request like <code>my long session keeps getting dumber</code></p>
</li>
<li>
<p>A small fixture project to run them in: a sample repo standing in for a real one</p>
</li>
<li>
<p>A second AI, the judge, that reads each answer and decides pass or fail against written expectations</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>The cases come from your product&#8217;s promises: write one for each rule it must follow and each kind of request it must handle.</p>
</div>
<div class="paragraph">
<p>My plan was just as simple: write the cases, let the judge grade the answers, fix the plugin until everything went green, then make that green a gate no release could skip.
This plan looked solid until the judge started grading.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-1-the-hard-part-of-your-evals-is-yours-to-write">Lesson 1: the hard part of your evals is yours to write</h2>
<div class="sectionbody">
<div class="paragraph">
<p>I wrote the first version of the suite in Go, like every other tool in the repo.
It worked, but I didn&#8217;t like owning an eval harness, the code that runs the suite, when so many already exist.
So I gave <a href="https://www.promptfoo.dev/" target="_blank" rel="noopener">Promptfoo</a>, one of the most popular eval frameworks, a real chance and ported the suite to it a few different ways.
All of them worked, but none beat the plain Go runner they were meant to replace.</p>
</div>
<div class="paragraph">
<p>Frameworks offer real machinery: assertions, built-in AI graders, and test matrices.
But the hard part of my suite, about 450 lines, was <em>state</em>: seeding a user profile on disk before each case (the plugin keeps one to remember what each developer already knows), isolating each run in its own throwaway home directory so runs can&#8217;t see each other&#8217;s files, handing the judge the exact catalog files to check answers against.
Every port kept all of that code and simply moved it into the framework&#8217;s hooks.
All Promptfoo could take off my hands was the loop that runs each case and collects results, a few dozen lines of Go, at the price of a second toolchain and a config layer.</p>
</div>
<div class="paragraph">
<p><strong>Before adopting an eval framework, count the lines it would actually save you.</strong>
If your product is stateless, prompt in and text out, a framework will save you real time.
Agent-focused harnesses like the UK AI Security Institute&#8217;s <a href="https://inspect.aisi.org.uk/" target="_blank" rel="noopener">Inspect</a> even host the isolated test environments for you.
But no framework knows your product&#8217;s rules, so the fixtures, the facts the judge grades against, and the checks are still yours to write.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-2-dont-let-the-judge-grade-from-memory">Lesson 2: don&#8217;t let the judge grade from memory</h2>
<div class="sectionbody">
<div class="paragraph">
<p>One of the first bugs my evals caught was in the judge, not the plugin.</p>
</div>
<div class="paragraph">
<p>The plugin taught a real, documented Claude Code feature that shipped recently.
The judge flagged it as fabricated.
The judge&#8217;s training data was older than the feature, so it was grading 2026 answers with frozen knowledge, confidently calling the truth an invention.</p>
</div>
<div class="paragraph">
<p>That turned into a rule the suite still enforces: <strong>the judge only fails an answer based on facts it was handed, never on facts it remembers.</strong>
Handed means literally pasted into the judge&#8217;s prompt: the list of plugins that exist, the documentation behind each capability, and the files in the fixture project.
An instruction like "you know what Claude Code supports" is a mistake, because the judge&#8217;s knowledge is frozen at training time.
Same goes for any fact your judge couldn&#8217;t have learned in training: your internal rules, your data, whatever shipped last month.</p>
</div>
<div class="paragraph">
<p>Stale knowledge doesn&#8217;t only hide in the judge&#8217;s training.
One of my tests described, in prose, what one of the plugin&#8217;s data files should contain.
That file changes weekly by design, and the test failed three correct plugin answers in a row.
Prose descriptions go stale the moment the file changes, so now the judge gets the file itself instead of my description of it.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-3-measure-your-judge-before-trusting-it">Lesson 3: measure your judge before trusting it</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Handing the judge files fixed what it knew.
It did nothing for how it reasoned.</p>
</div>
<div class="paragraph">
<p>It took me weeks to check the judge itself, because <strong>a broken judge doesn&#8217;t look broken.</strong>
Its wrong verdicts look like product failures, so every red result sent me to fix the plugin instead of questioning the grader.
Eventually I blind-labeled a sample of the judge&#8217;s verdicts: reviewer agents read each answer and formed their own verdict before seeing the judge&#8217;s, and I settled the disagreements myself.
I used AI to audit the AI.
The <a href="https://arxiv.org/pdf/2306.05685" target="_blank" rel="noopener">textbook version</a> has a human label everything.
Letting AI reviewers do the first pass is what made it a couple hours of my time instead of a day.
Measuring and correcting a judge this way is called calibrating it.</p>
</div>
<div class="paragraph">
<p>The judge turned out to be right 75 percent of the time, meaning one verdict in four was wrong.</p>
</div>
<div class="paragraph">
<p>My own spec, the written rules for how the plugin must answer, required every recommendation to carry a "do it now" offer, and the judge failed answers for containing exactly that offer.
It passed an answer that skipped a required warning label, because a similar-looking phrase nearby fooled it.
And it excused some failures by citing exceptions that nobody had written anywhere.
Every error came from one sentence in the judge&#8217;s instructions or one ambiguous sentence in my spec, and every fix was one sentence long.</p>
</div>
<div class="paragraph">
<p>False greens, answers that broke the rules but passed anyway, were the expensive kind.
A wrong failure gets investigated.
A false green stays quiet: nobody checks a passing test, so the bug survives.
The couple hours I spent calibrating earned more trust in the suite than anything else in the project, and I did it two weeks late.
Two days after the one-sentence fixes, the same blind check hit 100 percent on a fresh sample of 24 verdicts.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-4-your-test-environment-misleads-you-too">Lesson 4: your test environment misleads you too</h2>
<div class="sectionbody">
<div class="paragraph">
<p>The judge had misled me more than once by then, so I got suspicious of the one component I had never questioned: the fixture project, the sample codebase Claude had generated at the start.
That suspicion was justified.</p>
</div>
<div class="paragraph">
<p>The fixture&#8217;s own docs claimed it was a web service built with <a href="https://expressjs.com/" target="_blank" rel="noopener">Express</a>, a popular Node.js framework.
It had no routes and no server, and the Express dependency sat unused.
One test asked the plugin to document "our orders endpoints", endpoints that didn&#8217;t exist.
One earlier failure I&#8217;d blamed on the plugin was actually the plugin correctly catching the fixture&#8217;s false claim, and getting punished for it.
Better yet, Claude had left a comment in the fixture&#8217;s source code: "eval cases need real paths to ground against".
In plain words: a note that this codebase exists to be tested.
Every test run, the plugin under test could read that it was inside a test.
That matters more than it sounds: <a href="https://arxiv.org/pdf/2505.23836" target="_blank" rel="noopener">models often detect when they are being evaluated</a>, and may behave differently when they do.
The fix is two cheap checks.
<strong>Verify every claim the fixture makes about itself against its own files, and search it for anything that admits it&#8217;s a test.</strong></p>
</div>
<div class="paragraph">
<p>By that point the judge had invented exceptions, my spec had proven ambiguous, and the fixture had lied about what it was.
All three failures shared the same shape: something that sounded right until it was checked.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="the-discovery-that-changed-my-strategy">The discovery that changed my strategy</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Around week four I got tired of iterating: twenty-ish pull requests, each fixing one eval failure, and some introducing regressions.
I told Claude there has to be a better approach.</p>
</div>
<div class="paragraph">
<p>The audit that followed found what I should have seen earlier.
Most failures lived in one layer: the judge interpreting prose.
A few checks skipped the judge entirely, plain code like greps and file comparisons, and they&#8217;d never produced a wrong verdict.</p>
</div>
<div class="paragraph">
<p>That&#8217;s when I realized <strong>I didn&#8217;t need to make the judge better, I needed to rely on it less.</strong></p>
</div>
<div class="paragraph">
<p>So I gave the plugin a receipt to append to its answers: one HTML comment, a machine-readable summary of what it just did.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>&lt;!-- mentor mode=problem goal=debugging move=autonomous-loops surprise=hooks-as-workflow --&gt;</code></pre>
</div>
</div>
<div class="paragraph">
<p>Users never see it: the plugin only emits the receipt when an environment variable enables it, and only the eval runner sets that variable.
The fields are the plugin&#8217;s own vocabulary: the mode it ran in, the goal it classified, the move it recommended, and the surprise, a bonus capability it taught along the way.
The eval runner reads it, and suddenly the hard questions become string comparisons.
Did it classify correctly?
Just check if the goal equals "debugging".
Did it re-offer the capability the user declined?
Just grep for it.
Same verdict every time.</p>
</div>
<div class="admonitionblock important">
<table>
<tr>
<td class="icon">
<i class="fa icon-important" title="Important"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This works because the plugin&#8217;s decisions come from a fixed menu of goals and moves.
The receipt only works if your product&#8217;s answers fit a short vocabulary.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The judge didn&#8217;t disappear.
A few cases genuinely need judgment, like the fabrication trap: ask for a feature that doesn&#8217;t exist and check that the plugin says so instead of playing along.
Everywhere else, the judge now answers exactly one question: does the answer match its receipt?
That one still needs a judge, because a model could write a receipt claiming one thing while the answer does another, and only a reader can catch the mismatch.
But one question is a far easier job than before, when my written expectations asked the judge to verify over a dozen separate things per answer.
A calibrated judge scores well, but only for a moment.
New cases can reintroduce the old biases, and I would have to keep re-checking it forever.
A string comparison never needs calibrating.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Adding the receipt changes the model you&#8217;re measuring.
This is a documented pattern: <a href="https://arxiv.org/pdf/2408.02442" target="_blank" rel="noopener">format requirements measurably degrade model output</a>.
I A/B tested the same cases with and without the receipt, and saw no effect at first.
Then my busiest test case, the one whose answers already carried the most work, started failing more often: producing the receipt cost the model effort exactly where it had none to spare.
Shrinking the receipt from five fields to the four you saw above recovered most of the loss.
So run this comparison on your most loaded case, not an easy one.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-5-your-rules-can-fight-each-other">Lesson 5: your rules can fight each other</h2>
<div class="sectionbody">
<div class="paragraph">
<p>One rule in my plugin says: never mention a capability the user has declined.
One test checks it.
The gate runs every case three times per release, because a single run can pass by luck, and this test kept failing for two weeks, at first roughly one run in three.</p>
</div>
<div class="paragraph">
<p>Six fixes lowered the failure rate, but none reached zero.
The model kept finding new sentences for the same leak, and at one point the investigation revealed why: another of my own rules was demanding the model justify its choice, and the only honest justification named the declined capability.</p>
</div>
<div class="paragraph">
<p><strong>When a model keeps violating an instruction in creative new ways, look for the second instruction rewarding it.</strong></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="lesson-6-not-every-failure-can-reach-zero">Lesson 6: not every failure can reach zero</h2>
<div class="sectionbody">
<div class="paragraph">
<p>The last lesson is the one I resisted longest.</p>
</div>
<div class="paragraph">
<p>Even after resolving the rules conflict, a residual failure rate remained: about 15 to 20 percent, stable, measured across dozens of individual runs.
What should a release gate do with a test like that, when no prompt engineering can remove the failures?</p>
</div>
<div class="paragraph">
<p>Failing every release would be honest but useless.
It would block a third or more of releases without surfacing anything new.
Retrying until green would be worse than no test at all, because a green earned by retries just means I got lucky.
So I split tests into two kinds:</p>
</div>
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 20%;">
<col style="width: 40%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">Kind</th>
<th class="tableblock halign-left valign-top">Example</th>
<th class="tableblock halign-left valign-top">Gate policy</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Promises</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">never invent a feature, never corrupt the user&#8217;s data</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Must pass every single run. One failure blocks the release.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Rates</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">wording rules, like never naming a capability the user declined</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Compared with the same test&#8217;s own recent failure rate. The gate goes red only when the rate <em>worsens</em>.</p></td>
</tr>
</tbody>
</table>
<div class="paragraph">
<p>I made the suite compute each flaky check&#8217;s baseline from the last five runs and ask a boring statistical question: is today&#8217;s failure count surprising, given the known rate?
The idea is anything but new: Google was already <a href="https://testing.googleblog.com/2016/05/flaky-tests-at-google-and-how-we.html" target="_blank" rel="noopener">treating its known-flaky tests this way</a> back in 2016.
Bad luck within the rate still passes, with a printed warning saying so.
A genuine regression stays red.
The test that blocked two releases became a monitored number that has not caused a crisis since.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="starting-from-scratch">If you are starting from scratch</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Eight things I&#8217;d tell myself a month ago:</p>
</div>
<div class="olist arabic">
<ol class="arabic">
<li>
<p>Before adopting an eval framework, count the lines it would actually save you. State is the hard part, and fixtures and rules are yours to write either way.</p>
</li>
<li>
<p>Hand the judge files, never facts from memory. The judge&#8217;s memory is frozen at training time, and yours goes stale the moment the thing you described changes, like a prose description of a file that changes weekly.</p>
</li>
<li>
<p>Start with 10 cases and a judge, but calibrate the judge in week one. Blind-label a sample of verdicts. The result will surprise you, and every disagreement is a one-sentence fix.</p>
</li>
<li>
<p>Move every check you can into plain code. Counting, greps, file diffs. If your product&#8217;s answers fit a short vocabulary, ask the model to emit a structured receipt instead, enabled by an environment variable only your eval runner sets. Reserve the judge for questions that need judgment.</p>
</li>
<li>
<p>When a model repeatedly breaks a rule, audit your other rules first. The contradiction may be yours.</p>
</li>
<li>
<p>Log every run to a file you keep. Per-case history is how you tell a flaky test from a stable 15 percent failure rate wearing a flaky costume. Without it, you can&#8217;t tell the difference.</p>
</li>
<li>
<p>Decide which tests are promises and which are rates, and give them different gates. One policy for both will either block good releases or let real failures slip through.</p>
</li>
<li>
<p>Make every eval-fix PR prove its fix in the PR. Run the target case several times before merging. Without that, "the diff looks right" quietly becomes "fixed".</p>
</li>
</ol>
</div>
</div>
</div>
<div class="sect1">
<h2 id="dig-deeper">Dig deeper</h2>
<div class="sectionbody">
<div class="ulist">
<ul>
<li>
<p><a href="https://platform.claude.com/docs/en/test-and-evaluate/develop-tests" target="_blank" rel="noopener">Anthropic&#8217;s guide to building evals</a> covers eval design and grading options, including code-based and model-based grading.</p>
</li>
<li>
<p>Hamel Husain&#8217;s <a href="https://hamel.dev/blog/posts/evals/" target="_blank" rel="noopener">Your AI Product Needs Evals</a> is the best practitioner introduction I know, and his follow-up on <a href="https://hamel.dev/blog/posts/llm-judge/" target="_blank" rel="noopener">LLM-as-judge</a> walks through judge calibration with a domain expert, the technique that caught my broken judge.</p>
</li>
<li>
<p>The evals section of Eugene Yan&#8217;s <a href="https://eugeneyan.com/writing/llm-patterns/#evals-to-measure-performance" target="_blank" rel="noopener">Patterns for Building LLM-based Systems &amp; Products</a> surveys eval patterns and their tradeoffs.</p>
</li>
<li>
<p>The <a href="https://arxiv.org/pdf/2005.04118" target="_blank" rel="noopener">CheckList paper</a> (Ribeiro et al.) inspired how I picked cases: cover each capability and each rule systematically instead of adding cases as they occur to you.</p>
</li>
<li>
<p><a href="https://arxiv.org/pdf/2406.12045" target="_blank" rel="noopener">τ-bench</a> introduced <code>pass^k</code>, the "must pass every run" metric this post calls promises, and shows how badly single-run pass rates overstate agent reliability.</p>
</li>
<li>
<p><a href="https://arxiv.org/pdf/2411.00640" target="_blank" rel="noopener">Adding Error Bars to Evals</a> argues that eval numbers should come with uncertainty estimates, the statistics behind treating failures as rates.</p>
</li>
<li>
<p><a href="https://inspect.aisi.org.uk/" target="_blank" rel="noopener">Inspect</a> natively supports repeated runs per case and rules for combining their verdicts, if you want rates without building them yourself.</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>I&#8217;m one month into evals, and still learning.
It took me most of that month to stop fixing failures that don&#8217;t matter.
I worked through all of it with Claude Fable 5, and we checked every claim in this post against the suite&#8217;s code and run logs.
The whole suite is <a href="https://github.com/gwenneg/ai-mentor" target="_blank" rel="noopener">open source</a> if you want to see any of it for real.</p>
</div>
<div class="paragraph">
<p>If you&#8217;ve built evals for your own product, or you&#8217;re about to, I&#8217;m curious how it compares: share your experience, tips, or corrections in the comments.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="ai" /><category term="claude code" /><category term="evals" /><category term="llm" /><category term="testing" /><summary type="html"><![CDATA[You can&#8217;t unit-test an AI. Notes from a month of building evals instead.]]></summary></entry><entry><title type="html">Which 80% of Claude Code are you missing?</title><link href="https://gwenneg.github.io/2026/07/13/which-80-percent-of-claude-code-are-you-missing.html" rel="alternate" type="text/html" title="Which 80% of Claude Code are you missing?" /><published>2026-07-13T00:00:00+02:00</published><updated>2026-07-13T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/07/13/which-80-percent-of-claude-code-are-you-missing</id><content type="html" xml:base="https://gwenneg.github.io/2026/07/13/which-80-percent-of-claude-code-are-you-missing.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>You&#8217;re probably using 20% of Claude Code, and you have no way of knowing which 80% you&#8217;re missing.</p>
</div>
<div class="paragraph">
<p>Did you know the <code>/rewind</code> menu can bring back the conversation you just wiped with <code>/clear</code>?
That <code>/usage</code> can tell you which plugin or MCP server is eating your rate limit?
That <code>/goal</code> keeps Claude working unattended, across as many turns as it takes, until a condition you stated holds?
If any of those are news to you, that&#8217;s your 80%.
And none of it is hidden: everything is in Claude Code&#8217;s docs, and something new lands nearly every week.
The problem is that you cannot search for a capability you don&#8217;t know exists.</p>
</div>
<div class="paragraph">
<p>Even if you know a Claude Code feature exists, nothing reminds you of it when a problem shows up.
A developer whose test fails one time in five doesn&#8217;t wonder whether an autonomous loop with a machine-checkable finish line would help.
They wonder how to fix the flaky test, and they retry the pipeline for another week.</p>
</div>
<div class="paragraph">
<p>I built <a href="https://github.com/gwenneg/ai-mentor" target="_blank" rel="noopener">AI Mentor</a> to close that gap.
It&#8217;s a Claude Code plugin that reads your setup, your session and your repo, computes the difference between what Claude Code offers and what you actually use, and teaches you the most valuable thing you&#8217;re missing.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-a-session-with-ai-mentor-looks-like">What a session with AI Mentor looks like</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Say a CVE just dropped against a library you depend on:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/ai-mentor:mentor Our scanner flagged jackson-databind for CVE-2022-42003. Do we need the upgrade and what breaks if we bump it?</code></pre>
</div>
</div>
<div class="sect2">
<h3 id="grounded-in-your-repo">Grounded in your repo</h3>
<div class="paragraph">
<p>Before recommending anything, the mentor reads your dependency file and finds the exact version you&#8217;re pinned to.
The answer names that version, not a generic "check whether you are affected".</p>
</div>
</div>
<div class="sect2">
<h3 id="one-move-with-the-why">One move, with the why</h3>
<div class="paragraph">
<p>The mentor recommends a single approach, with the reasoning behind it, instead of a list of options to compare.
Here the move is deep research, with a research question the mentor drafts from the repo: affected version ranges, what an attacker actually needs, and the breaking-change history between your exact pin and the fixed release.</p>
</div>
<div class="paragraph">
<p>A routine CVE doesn&#8217;t need this: when the advisory is unambiguous and the fix is a patch bump, you read it and bump.
The move exists for the other kind, where the severity is disputed, the vulnerable code path may not apply to your usage at all, and the real answer is scattered across changelogs, migration guides and issue threads.
That&#8217;s the part of CVE triage that actually takes the time, and it&#8217;s multi-source, contested-information work: the deep research harness runs parallel searches and adversarially cross-checks claims against each other before citing them.
Most engineers don&#8217;t know this harness exists and assume AI research means a single web search.</p>
</div>
</div>
<div class="sect2">
<h3 id="one-surprise">One surprise</h3>
<div class="paragraph">
<p>Every answer also carries one capability you probably didn&#8217;t know about, picked for you based on what the mentor knows you haven&#8217;t seen yet.
Here it might be worktree isolation: try the upgrade in a disposable copy of your repo and get a real damage report, instead of guessing the impact from the changelog.</p>
</div>
</div>
<div class="sect2">
<h3 id="the-rest-behind-more">The rest behind "more"</h3>
<div class="paragraph">
<p>Say "more" and the full ranked list appears, and for this problem it covers the rest of the CVE&#8217;s lifecycle rather than five variations of one idea: plan mode to map which of your modules actually depend on the vulnerable package before you commit to anything, MCP context to wire your scanner&#8217;s findings straight into the conversation.
That wiring is more available than most people realize: GitHub&#8217;s official MCP server exposes your Dependabot alerts, the open-source scanners Trivy and OSV-Scanner ship MCP servers of their own, and every commercial scanner I checked publishes one too.</p>
</div>
<div class="paragraph">
<p>The mentor also saves you a wrong turn: ask it how to detect CVEs in your dependencies and it won&#8217;t point you at <code>/security-review</code>, whose analysis deliberately excludes exactly those findings.
No built-in Claude Code feature scans dependencies against an advisory database, and the mentor tells you so instead of improvising.
Detection stays with your scanner, and the MCP wiring above is exactly how its findings reach Claude for the assessment and the fix.</p>
</div>
</div>
<div class="sect2">
<h3 id="nothing-is-homework">Nothing is homework</h3>
<div class="paragraph">
<p>The response ends with the exact <code>/deep-research</code> line to paste, question already drafted from your repo, and the worktree command if you want the damage report first.
And when the move is something Claude can set up itself (a hook, a custom agent, a CI workflow), the mentor offers to write it in the same session.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="it-never-repeats-itself">It never repeats itself</h2>
<div class="sectionbody">
<div class="paragraph">
<p>The mentor keeps a small markdown file at <code>~/.ai-mentor/profile.md</code>, one line per capability, marked <code>shown</code>, <code>adopted</code> or <code>declined</code>:</p>
</div>
<div class="listingblock">
<div class="title">~/.ai-mentor/profile.md</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown"><span class="gh"># Mentor Profile</span>
<span class="ge">*Updated: 2026-07-13*</span>

Level: comfortable (daily Claude Code use, no automation yet)
Last new-capability check: 2026-w28

| Capability | Status | Date | Note |
|------------|--------|------|------|
| plan-mode | adopted | 2026-06-19 | Uses Shift+Tab habitually |
| hooks-as-workflow | adopted | 2026-06-26 | PostToolUse test hook in settings |
| deep-research | shown | 2026-07-08 | Demoed on the jackson-databind CVE triage |
| worktree-isolation | shown | 2026-07-08 | Upgrade damage report in a worktree |
| fan-out-workflows | declined | 2026-06-26 | "Too token-heavy for us" |</code></pre>
</div>
</div>
<div class="paragraph">
<p>This one tells the mentor: never explain plan mode or hooks to this engineer, open the next session by asking whether the deep research demo stuck, and never bring up fan-out again.
It does not re-teach what it showed you last week, it skips what you already use, and it drops anything you declined.</p>
</div>
<div class="paragraph">
<p>The profile is machine-local and never committed, and it never leaves your machine except as context inside your own Claude sessions.
You can edit or delete it whenever you want.
A hand edit always wins over anything the mentor inferred.
There is no account and no setup.</p>
</div>
<div class="paragraph">
<p>This is also why the mentor becomes more useful over time: every session starts from what you already know and reaches for the next thing you don&#8217;t.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="growth-mode">Growth mode: teach me something</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Everything so far started from a problem you brought, which the plugin calls problem mode.
Growth mode works in the other direction: invoke the mentor bare, and it finds something worth teaching on its own.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/ai-mentor:mentor</code></pre>
</div>
</div>
<div class="paragraph">
<p>Depending on what it finds in your setup and your profile, it teaches the most valuable capability you&#8217;re not using yet, follows up on the last thing it showed you, or opens with what shipped since you last checked.</p>
</div>
<div class="paragraph">
<p>This also changes how you stay up to date.
Following Claude Code means tracking changelogs, release notes, videos, tutorials and blog posts, and nobody sustains that alongside a day job.
The mentor collapses all of it into a single interaction, and it only ever shows you the part that matters to you.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-in-the-catalog">What&#8217;s in the catalog</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Under the hood, a playbook for each of 24 engineering goals (debugging, code review, refactoring, migration, incident response, performance, security, and so on) ranks 46 approaches.
Most of them are technique deep-dives, and the rest are verified records of external tools such as the Claude Code GitHub Action and hands-on-validated plugins from Anthropic&#8217;s official marketplace.</p>
</div>
<div class="paragraph">
<p>Two parts of the catalog are worth mentioning separately.</p>
</div>
<div class="paragraph">
<p>First, it also serves people building AI, not just people using it.
Four goal categories cover building AI agents, MCP integrations, skills and plugins, and LLM-powered product features, backed by dedicated catalog entries for the Agent SDK, MCP development tooling and LLM eval methodology.
If your team is shipping an AI feature, "what&#8217;s the right approach here?" is a mentor question too.</p>
</div>
<div class="paragraph">
<p>Second, beyond the promoted set, the full <a href="https://github.com/anthropics/claude-plugins-official" target="_blank" rel="noopener">official plugin marketplace</a> (around 250 plugins) is available as a lookup directory.
Name a technology in your problem, Quarkus or Terraform or Grafana, and the mentor greps the directory and surfaces the purpose-built plugin along with its install command.
Every entry is labeled with how far it was verified: hands-on (installed and exercised), desk-checked (reviewed but not exercised), or caution (a built-in does it better, or there is a sharp edge to know about).</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="why-not-just-ask-claude">Why not just ask Claude?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Claude already knows a lot about Claude Code, so why install a plugin instead of asking "what&#8217;s the best AI approach for debugging this?"</p>
</div>
<div class="paragraph">
<p>Because a model answering from memory is fine on average and unreliable in the details.
Claude Code changes every week, so any model&#8217;s memory of it has gaps, and a model asked about a gap doesn&#8217;t say "I don&#8217;t know".
It fills the gap with a plausible guess.</p>
</div>
<div class="sect2">
<h3 id="a-command-that-does-not-exist">A command that does not exist</h3>
<div class="paragraph">
<p>While writing this post, I asked Claude Fable 5, in a session without the plugin, which command searches the plugin marketplace.
The answer, from memory: <code>claude plugin search &lt;query&gt;</code>, described with full confidence down to the argument syntax.
That command does not exist.
Even the strongest Claude available today fails this way when its memory has a gap.
The same answer correctly named <code>claude plugin install</code>, and that is what makes the invented half so hard to spot: the correct and the fabricated command sit side by side, delivered with the same confidence.</p>
</div>
</div>
<div class="sect2">
<h3 id="same-failure-other-shapes">Same failure, other shapes</h3>
<div class="paragraph">
<p>Each guess below follows the same pattern, and each correction was checked against the current official docs:</p>
</div>
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 50%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">The plausible guess</th>
<th class="tableblock halign-left valign-top">The reality</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">An environment variable that feels like it should exist: <code>$CLAUDE_FILE_PATH</code> in a hook</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">No such variable exists: hooks receive their input as JSON on stdin</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">A config format guessed from convention: custom agent <code>tools</code> as a YAML list</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">The <code>tools</code> field is a comma-separated string</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">A path that mirrors a real one: MCP config in <code>~/.claude/mcp.json</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">User-scoped MCP servers live in <code>~/.claude.json</code></p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">A behavior assumed from similar features: "checkpoints don&#8217;t survive a restart"</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Checkpoints persist across sessions and are cleaned up after 30 days</p></td>
</tr>
</tbody>
</table>
</div>
<div class="sect2">
<h3 id="a-moving-target">A moving target</h3>
<div class="paragraph">
<p>Claude Code moves faster than any model&#8217;s memory of it.
A guess that is wrong today can quietly become right after a release, and a correct answer can go stale the same way.
Whatever the model tells you, you never know which side of that line it is on.
A catalog that is verified against the docs, and re-verified as they change, takes memory out of the loop.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="keeping-the-catalog-accurate">Keeping the catalog accurate</h2>
<div class="sectionbody">
<div class="paragraph">
<p>A catalog loses its value the moment its content stops matching reality, so most of the engineering in this project went into the pipeline that keeps it accurate:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>A linter runs in CI and verifies the catalog&#8217;s structural invariants on every PR: every playbook ranking points at a real approach file, every tool record is structurally complete, and the compiled capability index stays in sync with its sources.</p>
</li>
<li>
<p>A drift checker compares the catalog against the live official marketplace manifest, so plugins added or removed upstream are flagged instead of the directory silently going stale.</p>
</li>
<li>
<p>A <a href="https://github.com/gwenneg/ai-mentor/blob/main/.claude/skills/ai-mentor-update/SKILL.md" target="_blank" rel="noopener">maintenance skill</a> keeps the content current: every Monday, a headless Claude session runs it in CI, processes the week&#8217;s Claude Code changelog, syncs the catalog, and opens a pull request for human review. Weeks with nothing to do are detected deterministically and skipped, so quiet weeks cost nothing.</p>
</li>
<li>
<p>The same skill has a deeper mode that re-verifies the claims in each file against current official docs, oldest-verified first. Every file carries its last-verified date, and the full catalog was last re-verified against Claude Code v2.1.206.</p>
</li>
<li>
<p>An automated benchmark suite is wired into CI for every release. It checks classification, grounding, output shape, the never-repeat guarantee, and that recommendations contain zero fabricated commands.</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>The pipeline also runs on the same capabilities the catalog teaches: the maintenance passes are headless Claude sessions on a weekly schedule, so the plugin that recommends AI workflows is itself maintained by one.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="find-your-80">Find your 80%</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Installation is three lines in Claude Code, no cloning and no file editing.
The first line adds my plugin marketplace, claude-ichiba, and the next two install the plugin from it:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace add gwenneg/claude-ichiba
/plugin install ai-mentor@claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Installing a plugin usually means letting its author run code on your machine.
AI Mentor ships no hooks, no MCP servers and no binaries: everything it does goes through Claude&#8217;s normal permission prompts, and you can audit every file before installing, since it&#8217;s all markdown.
And every release is pinned to an immutable commit SHA: what you install is what you keep running, and work in progress on <code>main</code> never reaches you.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Then bring it a real problem, or bring nothing and let <a href="#growth-mode">growth mode</a> pick the lesson:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/ai-mentor:mentor [your problem, or leave empty to learn something you don't know]</code></pre>
</div>
</div>
<div class="paragraph">
<p>You don&#8217;t have to remember to call it either.
If you ask something mentor-shaped in a normal session, like "what&#8217;s the best way to use AI for this?", Claude invokes it on its own.</p>
</div>
<div class="paragraph">
<p>Claude Code disables auto-update for third-party marketplaces by default, but this plugin ships updates regularly, because the catalog tracks a tool that changes weekly.
Either enable auto-update once (<code>/plugin</code> &#8594; Marketplaces &#8594; claude-ichiba), or refresh manually whenever you want the latest catalog:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace update claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Not sure when to update? <a href="https://github.com/gwenneg/ai-mentor/subscription" target="_blank" rel="noopener">Subscribe to releases</a> and GitHub will tell you the moment a new version ships, so you know exactly when to run the update above.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>If you try it, start with the problem you are actually dealing with today.
The plugin did its job when the answer contains something you didn&#8217;t know existed.
And when it doesn&#8217;t, tell the mentor: it records what you already know and does better next time.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-next">What&#8217;s next?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>AI Mentor is deliberately Claude Code-first, so every recommendation can be verified against one tool&#8217;s current reality instead of being vaguely right about five tools.
Support for other Agent Skills-compatible tools may come later.</p>
</div>
<div class="paragraph">
<p>I&#8217;m also considering the community plugin marketplace, which holds more than two thousand plugins of very uneven quality.
If it joins the catalog, it will be through a strict selection: a small set of proven, actively maintained plugins, carrying the same trust tiers as everything else.</p>
</div>
<div class="paragraph">
<p>Everything is open source under Apache-2.0: the catalog, the playbooks, the verification tooling and the eval suite all live at <a href="https://github.com/gwenneg/ai-mentor" target="_blank" rel="noopener">github.com/gwenneg/ai-mentor</a>.
Issues and pull requests are welcome, especially reports of anything the mentor got wrong.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="ai" /><category term="claude code" /><category term="developer experience" /><category term="plugins" /><summary type="html"><![CDATA[AI Mentor is a Claude Code plugin that finds the capabilities you don&#8217;t know exist and teaches them one at a time, grounded in your real repo.]]></summary></entry><entry><title type="html">Claude Code plugins and the trust nobody talks about</title><link href="https://gwenneg.github.io/2026/06/26/claude-code-plugins-and-the-trust-nobody-talks-about.html" rel="alternate" type="text/html" title="Claude Code plugins and the trust nobody talks about" /><published>2026-06-26T00:00:00+02:00</published><updated>2026-06-26T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/06/26/claude-code-plugins-and-the-trust-nobody-talks-about</id><content type="html" xml:base="https://gwenneg.github.io/2026/06/26/claude-code-plugins-and-the-trust-nobody-talks-about.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>I&#8217;ve been spending a lot of time with Claude Code skills, hooks and plugins lately.
When I started building <a href="https://github.com/gwenneg/togi" target="_blank" rel="noopener">togi</a> (a friction-capture plugin), I quickly realized the way plugins are published comes with real supply-chain risks.
I wanted to understand them fully and mitigate them as much as possible before shipping anything.
Then a second plugin idea came up, and I needed a way to publish both from a single <a href="https://github.com/gwenneg/claude-ichiba" target="_blank" rel="noopener">marketplace</a> while keeping each plugin in its own repo.
The multi-repo layout and the GitHub Actions plumbing for that are easy to find, but what I couldn&#8217;t find anywhere was the supply-chain security reasoning behind the design, and a working pipeline built around it.
The <a href="https://code.claude.com/docs/en/plugin-marketplaces" target="_blank" rel="noopener">official docs</a> describe SHA pinning as a feature but never explain <em>why</em> you should use it or what happens if you don&#8217;t.</p>
</div>
<div class="paragraph">
<p>This post is what I learned: the risks, the mitigations, and the pipeline that ties it all together.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="a-plugin-is-not-a-library">A plugin is not a library</h2>
<div class="sectionbody">
<div class="paragraph">
<p>A Claude Code plugin is not a passive dependency you import.
Installing one lets the author run code on your machine, at every session start and end, with no per-update review.
Hooks can run shell scripts, but they can also execute pre-compiled binaries shipped in the plugin repo.
Git preserves the executable bit, so a binary committed with <code>chmod +x</code> is ready to run the moment Claude Code fetches the plugin.
No additional permission step on the user&#8217;s machine.
As of this writing, Claude Code shows no diff when plugin hooks change and asks for no re-approval.
There is no plugin signing, no checksum verification, no integrity check in the install path.
That is a lot of trust to hand someone.</p>
</div>
<div class="paragraph">
<p>So the security bar for publishing a plugin is closer to running a software-update service than shipping a package.
Every design choice in this post follows from that.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-can-go-wrong">What can go wrong</h2>
<div class="sectionbody">
<div class="paragraph">
<p>A plugin&#8217;s <code>source</code> field in <code>marketplace.json</code> tells Claude Code where to fetch the code.
The three options (branch, tag and SHA) carry very different risks.</p>
</div>
<div class="sect2">
<h3 id="branch">Branch</h3>
<div class="paragraph">
<p>A branch (e.g. <code>main</code>, or a relative <code>"./."</code> source) tracks the latest commit silently.
Every push is an implicit release.
One bad commit, whether from a compromised account, a force push, or a merged malicious PR, reaches every user on their next marketplace refresh.
No gate, no review, no rollback signal.</p>
</div>
</div>
<div class="sect2">
<h3 id="tag">Tag</h3>
<div class="paragraph">
<p>Most people assume a tag (<code>v0.3.0</code>) is immutable.
It&#8217;s not: <code>git tag -f v0.3.0 &lt;new-sha&gt;</code> silently rewrites what the tag points to.
GitHub repository rulesets can block force-moves and tag deletion, but that protection is a repo-owner setting, not a platform guarantee.
A compromised account can disable the ruleset, re-point a tag to a different commit, and users fetching the tag get different code with no way to tell.</p>
</div>
</div>
<div class="sect2">
<h3 id="sha">SHA</h3>
<div class="paragraph">
<p>A SHA is content-addressed and immutable.
It cannot be re-pointed, force-moved, or overwritten.
Anyone can verify what they run by comparing the pinned SHA against the repository history and inspecting the tree at that commit.
Not exactly convenient, but in a system with no signing, this is the best you can get.</p>
</div>
<div class="paragraph">
<p>The <a href="https://code.claude.com/docs/en/plugin-marketplaces" target="_blank" rel="noopener">official docs</a> mention the <code>sha</code> field as "Optional. Full 40-character git commit SHA to pin to an exact version."
That undersells it.
SHA pinning is not a version-management convenience.
It is the only thing standing between your machine and silent code substitution in a system with no signing.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="a-marketplace-plugin-entry">A marketplace plugin entry</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Three fields in each marketplace plugin entry control version detection, code pinning, and release traceability:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"$schema"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://json.schemastore.org/claude-code-marketplace.json"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"claude-ichiba"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"plugins"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
    </span><span class="p">{</span><span class="w">
      </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"togi"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"description"</span><span class="p">:</span><span class="w"> </span><span class="s2">"Captures AI coding friction..."</span><span class="p">,</span><span class="w">
      </span><span class="nl">"version"</span><span class="p">:</span><span class="w"> </span><span class="s2">"0.3.0"</span><span class="p">,</span><span class="w"> <i class="conum" data-value="1"></i><b>(1)</b>
      </span><span class="nl">"source"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
        </span><span class="nl">"source"</span><span class="p">:</span><span class="w"> </span><span class="s2">"github"</span><span class="p">,</span><span class="w">
        </span><span class="nl">"repo"</span><span class="p">:</span><span class="w"> </span><span class="s2">"gwenneg/togi"</span><span class="p">,</span><span class="w">
        </span><span class="nl">"ref"</span><span class="p">:</span><span class="w"> </span><span class="s2">"v0.3.0"</span><span class="p">,</span><span class="w"> <i class="conum" data-value="2"></i><b>(2)</b>
        </span><span class="nl">"sha"</span><span class="p">:</span><span class="w"> </span><span class="s2">"744400ba1d80c69fb9fa078862974e94fc353753"</span><span class="w"> <i class="conum" data-value="3"></i><b>(3)</b>
      </span><span class="p">}</span><span class="w">
    </span><span class="p">}</span><span class="w">
  </span><span class="p">]</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Claude Code&#8217;s update cache key. This is how it decides whether a newer version is available.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>The branch or tag Claude Code fetches the plugin from. When <code>sha</code> is also set, Claude Code pins to the SHA directly. <code>ref</code> stays in the entry as a human-readable label: which tag this SHA came from.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>The immutable security anchor. A SHA cannot be re-pointed, force-moved, or overwritten.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Both <code>version</code> and <code>sha</code> must change together on every release: a version bump without a SHA bump ships the same code, and a SHA bump without a version bump is invisible to Claude Code&#8217;s update mechanism.</p>
</div>
<div class="sect2">
<h3 id="why-version-stays-out-of-plugin-json">Why version stays out of plugin.json</h3>
<div class="paragraph">
<p>Claude Code <a href="https://code.claude.com/docs/en/plugin-marketplaces#version-resolution-and-release-channels" target="_blank" rel="noopener">resolves a plugin&#8217;s version</a> in this order: <code>plugin.json</code> first, then the marketplace entry, then the source SHA.</p>
</div>
<div class="paragraph">
<p>If <code>plugin.json</code> sets a version, it silently wins over the marketplace entry.
A version bump in the marketplace alone changes nothing: Claude Code still sees the old version from <code>plugin.json</code> and skips the update.</p>
</div>
<div class="paragraph">
<p>Keeping <code>version</code> only in the marketplace entry means the catalog is the single authority on what gets released.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="why-split-the-marketplace-from-the-plugin">Why split the marketplace from the plugin?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>A Claude Code <a href="https://code.claude.com/docs/en/plugin-marketplaces" target="_blank" rel="noopener">marketplace</a> is a JSON catalog that lists plugins and tells Claude Code where to fetch them.
When the marketplace and the plugin share a repo, <code>source</code> is typically a relative path or a self-reference.
That ties the plugin&#8217;s development to the marketplace&#8217;s.
Every plugin commit is a marketplace commit.
Every collaborator who can touch a plugin can also touch the catalog.</p>
</div>
<div class="paragraph">
<p>Splitting gives you:</p>
</div>
<table class="tableblock frame-all grid-all fit-content stretch">
<colgroup>
<col>
<col>
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">Benefit</th>
<th class="tableblock halign-left valign-top">What it means</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Independent lifecycles</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">A plugin repo has its own issues, PRs, and releases. The marketplace repo is a thin catalog that changes only when a plugin releases.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Multiple plugins, one catalog</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Adding a second plugin means adding an entry to <code>marketplace.json</code>, not restructuring the repo.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">Separate access control</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Contributors to a plugin do not need write access to the catalog.</p></td>
</tr>
</tbody>
</table>
</div>
</div>
<div class="sect1">
<h2 id="pipeline-layout">Pipeline layout</h2>
<div class="sectionbody">
<div class="paragraph">
<p>I built a release pipeline for Claude Code plugins around two repos, both open source: <a href="https://github.com/gwenneg/claude-ichiba" target="_blank" rel="noopener">claude-ichiba</a> (Japanese for marketplace) is the catalog, and <a href="https://github.com/gwenneg/togi" target="_blank" rel="noopener">togi</a> is the friction-capture plugin.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>claude-ichiba/                     # marketplace catalog
├── .claude-plugin/
│   └── marketplace.json           # references plugins in other repos
└── .github/
    └── workflows/
        └── update-marketplace.yml # receives release dispatches

togi/                              # plugin repo
├── .claude-plugin/
│   └── plugin.json                # plugin manifest (no version field)
├── skills/
├── hooks/
└── .github/
    └── workflows/
        └── release.yml            # tags → release → dispatch</code></pre>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="from-tag-to-release">From tag to release</h2>
<div class="sectionbody">
<div class="sect2">
<h3 id="step-1-tag-and-release-plugin-repo">Step 1: tag and release (plugin repo)</h3>
<div class="paragraph">
<p>The release flow starts with a signed annotated tag push:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">git tag <span class="nt">-s</span> v0.3.0 <span class="nt">-m</span> <span class="s2">"v0.3.0"</span>
git push origin v0.3.0</code></pre>
</div>
</div>
<div class="paragraph">
<p>The tag triggers a release workflow, which dispatches to the marketplace repo:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="na">name</span><span class="pi">:</span> <span class="s">Release</span>

<span class="na">on</span><span class="pi">:</span>
  <span class="na">push</span><span class="pi">:</span>
    <span class="na">tags</span><span class="pi">:</span> <span class="pi">[</span><span class="s1">'</span><span class="s">v*'</span><span class="pi">]</span>

<span class="na">jobs</span><span class="pi">:</span>
  <span class="na">release</span><span class="pi">:</span>
    <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
    <span class="na">permissions</span><span class="pi">:</span>
      <span class="na">contents</span><span class="pi">:</span> <span class="s">write</span> <i class="conum" data-value="1"></i><b>(1)</b>
    <span class="na">steps</span><span class="pi">:</span>

      <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="s">tag</span>
        <span class="na">name</span><span class="pi">:</span> <span class="s">Validate and extract tag</span>
        <span class="na">env</span><span class="pi">:</span>
          <span class="na">GH_TOKEN</span><span class="pi">:</span> <span class="s">${{ secrets.GITHUB_TOKEN }}</span>
        <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
          <span class="s">TAG="${GITHUB_REF#refs/tags/}"</span>
          <span class="s"># Only annotated tags are supported — lightweight tags provide no signing guarantee.</span>
          <span class="s">TYPE=$(gh api "repos/$GITHUB_REPOSITORY/git/ref/tags/$TAG" --jq '.object.type')</span>
          <span class="s">if [ "$TYPE" != "tag" ]; then</span>
            <span class="s">echo "Error: $TAG is not an annotated tag (type='$TYPE')"</span>
            <span class="s">exit 1</span>
          <span class="s">fi</span>
          <span class="s">echo "value=$TAG" &gt;&gt; "$GITHUB_OUTPUT"</span>

      <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="s">create-release</span>
        <span class="na">name</span><span class="pi">:</span> <span class="s">Create release</span>
        <span class="na">env</span><span class="pi">:</span>
          <span class="na">GH_TOKEN</span><span class="pi">:</span> <span class="s">${{ secrets.GITHUB_TOKEN }}</span>
          <span class="na">TAG</span><span class="pi">:</span> <span class="s">${{ steps.tag.outputs.value }}</span>
        <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
          <span class="s">URL=$(gh release create "$TAG" --repo "$GITHUB_REPOSITORY" --title "$TAG" --generate-notes)</span>
          <span class="s">echo "url=$URL" &gt;&gt; "$GITHUB_OUTPUT"</span>

      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Dispatch to marketplace</span>
        <span class="na">env</span><span class="pi">:</span>
          <span class="na">ICHIBA_PAT</span><span class="pi">:</span> <span class="s">${{ secrets.ICHIBA_PAT }}</span> <i class="conum" data-value="2"></i><b>(2)</b>
          <span class="na">RELEASE</span><span class="pi">:</span> <span class="s">${{ steps.create-release.outputs.url }}</span>
        <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
          <span class="s"># Sends a `repository_dispatch` event to the marketplace repo with the release URL as the only payload.</span>
          <span class="s">curl -fsSL -X POST \</span>
            <span class="s">-H "Authorization: token $ICHIBA_PAT" \</span>
            <span class="s">-H "Accept: application/vnd.github+json" \</span>
            <span class="s">"https://api.github.com/repos/gwenneg/claude-ichiba/dispatches" \</span>
            <span class="s">-d "$(jq -n --arg release "$RELEASE" '{event_type: "plugin-release", client_payload: {release: $release}}')"</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Required by <code>gh release create</code>.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>See <a href="#the-bridge-a-fine-grained-pat">The bridge: a fine-grained PAT</a>.</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="step-2-update-the-catalog-marketplace-repo">Step 2: update the catalog (marketplace repo)</h3>
<div class="paragraph">
<p>The marketplace repo receives the dispatch and resolves the plugin, tag, and commit SHA from the release URL.
It then opens a pull request so every catalog update can be reviewed before it reaches <code>main</code>.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="na">name</span><span class="pi">:</span> <span class="s">Update Marketplace</span>

<span class="na">on</span><span class="pi">:</span>
  <span class="na">repository_dispatch</span><span class="pi">:</span>
    <span class="na">types</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">plugin-release</span><span class="pi">]</span>

<span class="na">jobs</span><span class="pi">:</span>
  <span class="na">update-marketplace</span><span class="pi">:</span>
    <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
    <span class="na">permissions</span><span class="pi">:</span>
      <span class="na">contents</span><span class="pi">:</span> <span class="s">write</span> <i class="conum" data-value="1"></i><b>(1)</b>
      <span class="na">pull-requests</span><span class="pi">:</span> <span class="s">write</span> <i class="conum" data-value="2"></i><b>(2)</b>
    <span class="na">steps</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">uses</span><span class="pi">:</span> <span class="s">actions/checkout@9c091bb21b7c1c1d1991bb908d89e4e9dddfe3e0</span> <span class="c1"># v7.0.0 </span><i class="conum" data-value="3"></i><b>(3)</b>

      <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="s">update-marketplace</span>
        <span class="na">name</span><span class="pi">:</span> <span class="s">Update marketplace.json</span>
        <span class="na">env</span><span class="pi">:</span>
          <span class="na">GH_TOKEN</span><span class="pi">:</span> <span class="s">${{ secrets.GITHUB_TOKEN }}</span>
          <span class="na">RELEASE</span><span class="pi">:</span> <span class="s">${{ github.event.client_payload.release }}</span>
        <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>

          <span class="s"># Resolve the plugin name by matching the release URL against `source.repo` in marketplace.json.</span>
          <span class="s">PLUGIN=$(jq -r --arg u "$RELEASE" \</span>
            <span class="s">'.plugins[] | select(("https://github.com/" + .source.repo + "/") as $prefix | $u | startswith($prefix)) | .name' \</span>
            <span class="s">.claude-plugin/marketplace.json)</span>
          <span class="s">if [ -z "$PLUGIN" ]; then</span>
            <span class="s">echo "Error: no plugin matched $RELEASE"</span>
            <span class="s">exit 1</span>
          <span class="s">fi</span>

          <span class="s"># Extract tag and repo from the release URL (https://github.com/owner/repo/releases/tag/vX.Y.Z).</span>
          <span class="s">TAG=$(basename "$RELEASE")</span>
          <span class="s">REPO=$(echo "$RELEASE" | cut -d'/' -f4-5)</span>

          <span class="s"># Resolve the commit SHA from the annotated tag — two calls needed to dereference the tag object.</span>
          <span class="s">REF=$(gh api "repos/$REPO/git/ref/tags/$TAG")</span>
          <span class="s">if [ "$(echo "$REF" | jq -r '.object.type')" != "tag" ]; then</span>
            <span class="s">echo "Error: $TAG is not an annotated tag"</span>
            <span class="s">exit 1</span>
          <span class="s">fi</span>
          <span class="s">SHA=$(gh api "repos/$REPO/git/tags/$(echo "$REF" | jq -r '.object.sha')" --jq '.object.sha')</span>

          <span class="s"># Update version, ref, and sha for the matched plugin. Uses a temp file because jq cannot read and write the same file.</span>
          <span class="s">jq --arg p "$PLUGIN" --arg v "${TAG#v}" --arg r "$TAG" --arg s "$SHA" \</span>
            <span class="s">'(.plugins[] | select(.name == $p)) |= (.version = $v | .source.ref = $r | .source.sha = $s)' \</span>
            <span class="s">.claude-plugin/marketplace.json &gt; /tmp/marketplace.json</span>
          <span class="s">mv /tmp/marketplace.json .claude-plugin/marketplace.json</span>

          <span class="s">echo "plugin=$PLUGIN" &gt;&gt; "$GITHUB_OUTPUT"</span>
          <span class="s">echo "tag=$TAG" &gt;&gt; "$GITHUB_OUTPUT"</span>

      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Create branch and PR</span>
        <span class="na">env</span><span class="pi">:</span>
          <span class="na">GH_TOKEN</span><span class="pi">:</span> <span class="s">${{ secrets.GITHUB_TOKEN }}</span>
          <span class="na">PLUGIN</span><span class="pi">:</span> <span class="s">${{ steps.update-marketplace.outputs.plugin }}</span>
          <span class="na">RELEASE</span><span class="pi">:</span> <span class="s">${{ github.event.client_payload.release }}</span>
          <span class="na">TAG</span><span class="pi">:</span> <span class="s">${{ steps.update-marketplace.outputs.tag }}</span>
        <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
          <span class="s">BRANCH="release/$PLUGIN-$TAG"</span>

          <span class="s"># Create the release branch from the current HEAD of main.</span>
          <span class="s">gh api "repos/$GITHUB_REPOSITORY/git/refs" \</span>
            <span class="s">--method POST \</span>
            <span class="s">-f "ref=refs/heads/$BRANCH" \</span>
            <span class="s">-f "sha=$(git rev-parse HEAD)"</span>

          <span class="s"># Commit the updated marketplace.json via the Contents API, which produces a signed commit.</span>
          <span class="s">gh api "repos/$GITHUB_REPOSITORY/contents/.claude-plugin/marketplace.json" \</span>
            <span class="s">--method PUT \</span>
            <span class="s">-f "message=release: $PLUGIN $TAG" \</span>
            <span class="s">-f "content=$(base64 -w 0 &lt; .claude-plugin/marketplace.json)" \</span>
            <span class="s">-f "sha=$(git rev-parse HEAD:.claude-plugin/marketplace.json)" \</span>
            <span class="s">-f "branch=$BRANCH"</span>

          <span class="s">gh pr create \</span>
            <span class="s">--title "release: $PLUGIN $TAG" \</span>
            <span class="s">--body "[$TAG]($RELEASE)" \</span>
            <span class="s">--base main \</span>
            <span class="s">--head "$BRANCH"</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Required to create the release branch and commit <code>marketplace.json</code>.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Required to create the pull request.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>Security tip: always pin GitHub Actions to a commit SHA, not a tag. The same tag-rewriting risk described earlier applies to actions too.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The triple update (<code>version</code>, <code>source.ref</code>, <code>source.sha</code>) happens in one <code>jq</code> call and lands in one commit, so the catalog is never in a half-updated state.</p>
</div>
</div>
<div class="sect2">
<h3 id="the-bridge-a-fine-grained-pat">The bridge: a fine-grained PAT</h3>
<div class="paragraph">
<p>Step 1 dispatches from the plugin repo to the marketplace repo.
The default <code>GITHUB_TOKEN</code> in a GitHub Actions workflow is scoped to its own repo, so it cannot reach another repository.
To make the cross-repo dispatch work, you need a token with write access to the target.</p>
</div>
<div class="paragraph">
<p>Create a <a href="https://github.com/settings/personal-access-tokens/new" target="_blank" rel="noopener">fine-grained Personal Access Token</a>:</p>
</div>
<div class="ulist">
<ul>
<li>
<p><strong>Repository access:</strong> only the marketplace repo</p>
</li>
<li>
<p><strong>Permissions:</strong> Contents → Read and write</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>Store it as a repository secret (e.g. <code>ICHIBA_PAT</code>) in the plugin repo.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This PAT is the most sensitive piece in the pipeline.
Anyone who obtains it can trigger a dispatch with an arbitrary release URL, opening a rogue pull request against the marketplace repo.
They cannot inject an arbitrary SHA: the marketplace workflow resolves the commit SHA directly from the GitHub API.
And they cannot write to <code>main</code> directly: the dispatch only opens a PR, which still requires review and approval.
The risk is noise and distraction, not silent code substitution.
That said: set an expiration, rotate it regularly, monitor the audit log for unexpected dispatch events, and revoke immediately if the plugin repo&#8217;s secrets are compromised.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-users-see">What users see</h2>
<div class="sectionbody">
<div class="paragraph">
<p>None of the pipeline complexity surfaces to users.
Their side stays simple.
Install with:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace add gwenneg/claude-ichiba
/plugin install togi@claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
<div class="paragraph">
<p>And update with:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>/plugin marketplace update claude-ichiba
/reload-plugins</code></pre>
</div>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p><a href="https://code.claude.com/docs/en/discover-plugins#configure-auto-updates" target="_blank" rel="noopener">Auto-update is off by default</a> for third-party marketplaces.
Users pull updates only when they choose to.
If a user or org admin enables auto-update, a compromised marketplace entry propagates without any user action at all.
The threat model changes significantly: the refresh becomes silent, not deliberate.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="adding-a-second-plugin">Adding a second plugin</h2>
<div class="sectionbody">
<div class="olist arabic">
<ol class="arabic">
<li>
<p>Create the plugin repo with its own <code>.claude-plugin/plugin.json</code>, skills, hooks, etc.</p>
</li>
<li>
<p>Copy <code>release.yml</code> verbatim: the marketplace resolves the plugin name from the release URL, so nothing is hardcoded per plugin.</p>
</li>
<li>
<p>Add an entry to <code>marketplace.json</code> in the marketplace repo.</p>
</li>
</ol>
</div>
</div>
</div>
<div class="sect1">
<h2 id="known-gaps">Known gaps</h2>
<div class="sectionbody">
<div class="paragraph">
<p>This setup is the best I could do with what Claude Code and GitHub offer today. It&#8217;s not airtight.</p>
</div>
<div class="ulist">
<ul>
<li>
<p><strong>The catalog lives on <code>main</code>.</strong> Every release goes through a pull request before landing. But the branch is the final source of truth: a bad commit that reaches it ships a rewritten SHA on the next refresh. Branch protection, required reviews, and required signed commits reduce this exposure but do not eliminate it.</p>
</li>
<li>
<p><strong>No update notification.</strong> Claude Code does not tell users when a new version exists. They have to watch the plugin repo for releases and refresh manually.</p>
</li>
<li>
<p><strong>No platform-level signing.</strong> Claude Code has no plugin signature verification. SHA pinning gives tamper-evidence (you can verify what you run), but not tamper-prevention (nothing stops a bad SHA from being written to the catalog if <code>main</code> is compromised). That gap closes only when Claude Code adds signing.</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>This pipeline won&#8217;t solve what Claude Code hasn&#8217;t built yet.
But it closes every gap I could find, and it&#8217;s yours to fork.</p>
</div>
<div class="paragraph">
<p>Plugin consumers: verify what you run.
Authors: make that easy.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="claude code" /><category term="plugins" /><category term="supply chain" /><category term="security" /><summary type="html"><![CDATA[The official Claude Code docs describe SHA pinning as a feature but never explain why it matters. This post does, and walks through a release pipeline built to publish Claude Code plugins safely.]]></summary></entry><entry><title type="html">Your Claude bill called. It wants to talk.</title><link href="https://gwenneg.github.io/2026/06/18/your-claude-bill-called.html" rel="alternate" type="text/html" title="Your Claude bill called. It wants to talk." /><published>2026-06-18T00:00:00+02:00</published><updated>2026-06-18T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/06/18/your-claude-bill-called</id><content type="html" xml:base="https://gwenneg.github.io/2026/06/18/your-claude-bill-called.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>AI-assisted coding is great. Until you check the bill.</p>
</div>
<div class="paragraph">
<p>The <a href="https://code.claude.com/docs/en/costs" target="_blank" rel="noopener">Claude Code docs</a> cover how to reduce costs.
This post ranks cost reduction practices by impact and tells you which ones to do first.
Most developers know a few.
Fewer apply them consistently.
The ranking weighs three things: how much a practice saves per session, how universally it applies, and how easy it is to start.
The first seven work for everyone.
The last three depend on your setup.</p>
</div>
<div class="paragraph">
<p>Each of the 10 practices below is worth 2 points: 1 for knowing it, 1 for applying it.
Keep score as you read.</p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post is focused on Claude.
Some of it may apply to other leading AI models.
Local models can also be a valid option to lower costs, but out of scope here.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-the-single-biggest-lever-to-reduce-costs">1. What&#8217;s the single biggest lever to reduce costs?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>Model selection.</strong> First point: free. Second point: when did you last reach for Haiku?</p>
</div>
<div class="paragraph">
<p>Pick the right model for your task:</p>
</div>
<div class="ulist">
<ul>
<li>
<p><strong>Haiku</strong>: simple and fast operations. Formatting, summarization, quick lookups. No heavy reasoning needed.</p>
</li>
<li>
<p><strong>Sonnet</strong>: most coding tasks. The sweet spot between capability and cost.</p>
</li>
<li>
<p><strong>Opus</strong>: complex reasoning, architectural decisions, tricky bugs.
Reach for it when the task genuinely needs it.</p>
</li>
<li>
<p><strong>Fable</strong>: top of the range, currently unavailable.
Most capable, most expensive. Use it when nothing else will do, or when it&#8217;s not your money.</p>
</li>
</ul>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>These suggestions are general guidance. There are many exceptions, and the landscape shifts quickly with every new model release. What matters most is the habit: always weigh capability against cost for the task at hand. That calculation also depends on whether you pay per token through the API or work within a subscription quota.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>In interactive sessions, use <code>/model</code> to switch. In skills and agents, set it in frontmatter.</p>
</div>
<div class="listingblock">
<div class="title">Skill or agent frontmatter</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="nn">---</span>
<span class="na">model</span><span class="pi">:</span> <span class="s">sonnet</span>
<span class="nn">---</span></code></pre>
</div>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://platform.claude.com/docs/en/about-claude/pricing" target="_blank" rel="noopener">Models pricing</a>, <a href="https://code.claude.com/docs/en/model-config" target="_blank" rel="noopener">Model configuration</a>, <a href="https://code.claude.com/docs/en/skills#frontmatter-reference" target="_blank" rel="noopener">Skill frontmatter</a>, <a href="https://code.claude.com/docs/en/sub-agents#supported-frontmatter-fields" target="_blank" rel="noopener">Sub-agent frontmatter</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="your-agent-is-thinking-hard-on-every-task-is-that-a-problem">2. Your agent is thinking hard on every task. Is that a problem?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>Yes. Claude is writing a dissertation about your variable renaming.</strong></p>
</div>
<div class="paragraph">
<p>Thinking tokens count as output tokens.
The priciest kind.
A single request can burn tens of thousands of them.
For a complex architectural decision, worth every token.
For "add a missing semicolon," not so much.</p>
</div>
<div class="paragraph">
<p>In interactive sessions, use <code>/effort low</code> or <code>/effort medium</code> for straightforward tasks, and <code>/effort high</code> when it actually matters. In skills and agents, set it in frontmatter so nobody has to remember.</p>
</div>
<div class="listingblock">
<div class="title">Skill or agent frontmatter</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="nn">---</span>
<span class="na">effort</span><span class="pi">:</span> <span class="s">low</span>
<span class="nn">---</span></code></pre>
</div>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://platform.claude.com/docs/en/about-claude/pricing" target="_blank" rel="noopener">Models pricing</a>, <a href="https://code.claude.com/docs/en/model-config#adjust-effort-level" target="_blank" rel="noopener">Effort configuration</a>, <a href="https://code.claude.com/docs/en/skills#frontmatter-reference" target="_blank" rel="noopener">Skill frontmatter</a>, <a href="https://code.claude.com/docs/en/sub-agents#supported-frontmatter-fields" target="_blank" rel="noopener">Sub-agent frontmatter</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="what-does-improve-the-codebase-actually-cost">3. What does 'improve the codebase' actually cost?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>A lot. The fix is simpler than you think: be specific.</strong></p>
</div>
<div class="paragraph">
<p>Claude starts by figuring out what your codebase even is.
That means reading files until it has enough context to act.
And every file it reads stays in context, getting re-sent with every follow-up message.
You&#8217;re paying for that exploration whether you asked for it or not.</p>
</div>
<div class="paragraph">
<p>Specificity isn&#8217;t just for interactive sessions.
In skills and agents, every word in the spawn prompt loads on top of everything the agent auto-loads, from turn one.
Vague instructions are just as expensive there.</p>
</div>
<div class="paragraph">
<p>Free points. You&#8217;re welcome.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="your-claude-md-documents-your-entire-architecture-smart-or-not">4. Your CLAUDE.md documents your entire architecture. Smart or not?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>Impressive documentation. Expensive documentation.</strong></p>
</div>
<div class="paragraph">
<p>Everything in CLAUDE.md loads at session start and gets re-sent on every single request, whether it&#8217;s relevant or not.
That beautifully written section explaining the history of your repository pattern?
Claude reads it before fixing a typo.
Every.
Single.
Time.</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Keep CLAUDE.md under 200 lines. Essentials only.</p>
</li>
<li>
<p>Move path-specific guidelines into rules. They load only when Claude works on matching files, not on every turn.</p>
</li>
<li>
<p>Move workflow instructions (PR reviews, deploy steps, migration guides) into skills.
They load on-demand, not on every turn.</p>
</li>
</ul>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/memory#path-specific-rules" target="_blank" rel="noopener">Path-specific rules</a>, <a href="https://code.claude.com/docs/en/skills" target="_blank" rel="noopener">Extend Claude with skills</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="you-just-finished-a-task-what-should-you-do-before-starting-the-next-one">5. You just finished a task. What should you do before starting the next one?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong><code>/clear</code>. Seriously.</strong></p>
</div>
<div class="paragraph">
<p>Every request re-sends the full conversation history as input tokens.
Once a task is done, that history is dead weight: old file reads, debugging logs, that long exchange where Claude went down the wrong path.
You&#8217;re carrying a suitcase full of things you don&#8217;t need anymore.</p>
</div>
<div class="paragraph">
<p><code>/clear</code> drops it.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="youre-mid-task-and-the-context-is-getting-heavy-what-do-you-do">6. You&#8217;re mid-task and the context is getting heavy. What do you do?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong><code>/compact</code>, but with instructions.</strong></p>
</div>
<div class="paragraph">
<p>Just running <code>/compact</code> summarizes the conversation, but Claude decides what to keep.
You can do better: <code>/compact Focus on modified files and unresolved errors</code> tells Claude exactly what matters.
You can also make it permanent in CLAUDE.md so it applies every time Claude compacts automatically.</p>
</div>
<div class="listingblock">
<div class="title">CLAUDE.md compaction instructions</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown">== Compact instructions

When compacting, focus on modified files and unresolved errors.</code></pre>
</div>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/context-window#when-your-context-fills-up" target="_blank" rel="noopener">Compact with a focus</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="your-agent-is-running-tests-and-reading-logs-where-does-all-that-output-go">7. Your agent is running tests and reading logs. Where does all that output go?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>In the main context, if you&#8217;re not careful.</strong></p>
</div>
<div class="paragraph">
<p>Test runners, log processors, and doc fetchers can generate a lot of output.
If that output lands in the main session, Claude re-sends it on every subsequent turn.
Subagents run in their own isolated context window.
The parent session gets a summary, not the raw output.</p>
</div>
<div class="paragraph">
<p>In skills and agents, structure workflows to delegate verbose operations to subagents.
The main agent stays lean.
In interactive sessions, Claude will usually make that call on its own, but you can always ask explicitly.</p>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/sub-agents#isolate-high-volume-operations" target="_blank" rel="noopener">Isolate high-volume operations</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="scripts-and-hooks-helping-claude-process-less">8. Scripts and hooks helping Claude process less</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This one is situational: the savings depend on how much output you&#8217;re actually cutting.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Pre-written scripts and hooks let you preprocess data before Claude sees it.
Feeding Claude a raw test report when all you needed was the failures means Claude processes a lot more than necessary.</p>
</div>
<div class="paragraph">
<p>A 2026 study filtered low-value output from agent trajectories and found 40-60% fewer input tokens and 21-36% lower costs, with no impact on task success. Scripts and hooks are a simpler way to act on the same idea.
The pattern scales well for agent-heavy workflows, but for small tasks the overhead isn&#8217;t worth it.</p>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://arxiv.org/html/2509.23586v2" target="_blank" rel="noopener">AgentDiet, FSE 2026</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="claude-is-about-to-rewrite-half-your-codebase-has-it-seen-a-plan-first">9. Claude is about to rewrite half your codebase. Has it seen a plan first?</h2>
<div class="sectionbody">
<div class="paragraph">
<p><strong>It should have.</strong></p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This one is situational: it only pays off on complex or ambiguous tasks.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Skip the plan and Claude might build the wrong thing entirely.
You pay for the wrong implementation, then pay to fix it.
Plan mode makes Claude explore and propose an approach before touching any code.
You review it, adjust it, then let it implement.</p>
</div>
<div class="paragraph">
<p>In interactive sessions, press Shift+Tab before giving Claude a large or ambiguous task.
In skills, bake it in: structure the definition to include an explicit planning step before execution.</p>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/permission-modes#analyze-before-you-edit-with-plan-mode" target="_blank" rel="noopener">Plan mode</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="did-you-actually-need-that-1m-context-window">10. Did you actually need that 1M context window?</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This one is situational.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p><strong>Surprise: it&#8217;s not free.</strong></p>
</div>
<div class="paragraph">
<p>The 1M context window costs the same per token as the default.
It just holds 5x more tokens, so sessions stay uncompacted much longer and every turn carries a heavier payload.
Stick with 200K unless you actually need it.</p>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/model-config#extended-context" target="_blank" rel="noopener">Extended context</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="how-do-you-know-if-its-working">How do you know if it&#8217;s working?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>You can&#8217;t improve what you can&#8217;t measure.</p>
</div>
<div class="paragraph">
<p>Run <code>/usage</code> in Claude Code to see token usage and cost for the current session.
Watch those numbers across sessions as you apply these practices.
The difference is visible.</p>
</div>
<div class="paragraph">
<p>Running the API or tracking team usage?
The Claude Console breaks it down by model, date, and API key.</p>
</div>
<div class="paragraph">
<p><em>Dig deeper:</em> <a href="https://code.claude.com/docs/en/costs#using-the-/usage-command" target="_blank" rel="noopener">Using the /usage command</a>, <a href="https://platform.claude.com/dashboard" target="_blank" rel="noopener">Claude Console</a></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="how-many-points-did-you-get">How many points did you get?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Scored 15 or above?
Genuinely impressive.</p>
</div>
<div class="paragraph">
<p>Below that?
You&#8217;re one or two practices away from making a real difference.
Start with model selection, and go from there.</p>
</div>
<div class="paragraph">
<p>Thanks for reading!</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="ai" /><category term="claude code" /><category term="costs" /><category term="developer experience" /><category term="skills" /><category term="agents" /><summary type="html"><![CDATA[10 practices to cut your Claude bill, ranked by impact. Score yourself as you read.]]></summary></entry><entry><title type="html">Turn AI friction into better docs</title><link href="https://gwenneg.github.io/2026/05/31/turn-ai-friction-into-better-docs.html" rel="alternate" type="text/html" title="Turn AI friction into better docs" /><published>2026-05-31T00:00:00+02:00</published><updated>2026-05-31T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/05/31/turn-ai-friction-into-better-docs</id><content type="html" xml:base="https://gwenneg.github.io/2026/05/31/turn-ai-friction-into-better-docs.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>In a <a href="/2026/05/28/the-docs-your-ai-agent-is-missing" target="_blank" rel="noopener">previous post</a>, I introduced a Claude skill that generates layered context docs for AI-assisted development: domain-specific guidelines, a cross-cutting <code>AGENTS.md</code>, path-scoped Claude rules, and a thin <code>CLAUDE.md</code> on top.</p>
</div>
<div class="paragraph">
<p>These files have two problems: they go stale as the codebase evolves, and the initial version is never perfect.
Some conventions only surface when the agent tries to follow the docs and stumbles: an unnecessary question, a wrong assumption, output that needs correcting.
Each of these stumbles is a friction event: a signal that the docs failed.</p>
</div>
<div class="paragraph">
<p>I wanted to automate as much of this as possible: capture friction, turn it into doc improvements, and keep developer effort to a minimum.
What I ended up with is a feedback loop built on git, Claude Code hooks, and shell scripts, no extra platform or infrastructure required.
Let me walk you through it.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="the-feedback-loop">The feedback loop</h2>
<div class="sectionbody">
<div class="paragraph">
<p>The loop has two phases:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Automated friction capture at the end of every Claude Code session</p>
</li>
<li>
<p>A manual step to turn accumulated friction events into context doc improvements</p>
</li>
</ul>
</div>
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/turn-ai-friction-into-better-docs/feedback-loop.svg" alt="Feedback loop" width="85%"></span></p>
</div>
<div class="sect2">
<h3 id="capturing-friction-automatically">Capturing friction automatically</h3>
<div class="paragraph">
<p>I wired up a <a href="https://code.claude.com/docs/en/hooks-guide#how-hooks-work" target="_blank" rel="noopener">SessionEnd hook</a> that fires at the end of every Claude Code session, or when the <a href="https://code.claude.com/docs/en/commands#all-commands" target="_blank" rel="noopener">/clear command</a> is run:</p>
</div>
<div class="listingblock">
<div class="title">.claude/settings.json</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"hooks"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"SessionEnd"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="p">{</span><span class="w">
        </span><span class="nl">"matcher"</span><span class="p">:</span><span class="w"> </span><span class="s2">""</span><span class="p">,</span><span class="w">
        </span><span class="nl">"hooks"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
          </span><span class="p">{</span><span class="w">
            </span><span class="nl">"type"</span><span class="p">:</span><span class="w"> </span><span class="s2">"command"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"command"</span><span class="p">:</span><span class="w"> </span><span class="s2">"bash .claude/scripts/friction-capture.sh"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"timeout"</span><span class="p">:</span><span class="w"> </span><span class="mi">5000</span><span class="w">
          </span><span class="p">}</span><span class="w">
        </span><span class="p">]</span><span class="w">
      </span><span class="p">}</span><span class="w">
    </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>When that happens, the <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/setup-friction-capture/scripts/friction-capture.sh" target="_blank" rel="noopener">friction-capture.sh</a> script runs in a background subshell, so it doesn&#8217;t block the user.
The script receives the transcript from the ended session and sends the last 200KB to Claude Haiku with a prompt asking it to identify friction events.
A <code>flock</code>-based lock inside the background block prevents concurrent runs.
Haiku is cheap enough that the cost per session stays under a few cents.</p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p><code>flock</code> is not available on macOS. The script currently requires Linux or a <code>flock</code> package like the one from Homebrew.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>The conversation between the user and Claude is sent to the Anthropic API at the end of each session, using the developer&#8217;s existing Claude Code credentials. Tool call outputs (file contents, command output) are not included, but anything discussed in the conversational text is. Injected content in the transcript could also produce friction events targeting arbitrary files. Review the resulting PR diff carefully, and exclude any suspicious events when the skill presents them. Friction capture is enabled by default after the setup PR merges. Developers can opt out with <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/disable-friction-capture/SKILL.md" target="_blank" rel="noopener"><code>/disable-friction-capture</code></a>.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="sect3">
<h4 id="what-counts-as-friction">What counts as friction</h4>
<div class="paragraph">
<p>The prompt tells Haiku to scan the transcript for four types of events:</p>
</div>
<div class="ulist">
<ul>
<li>
<p><strong>Corrections</strong>: the user corrected the agent&#8217;s output</p>
</li>
<li>
<p><strong>Clarifications</strong>: the agent asked a question the docs should have answered</p>
</li>
<li>
<p><strong>Mistakes</strong>: the agent made a wrong assumption about the codebase</p>
</li>
<li>
<p><strong>Denials</strong>: a tool call was denied, revealing a standing project policy (e.g., "don&#8217;t skip the OWASP dependency check")</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>Not everything qualifies. The prompt applies two filters: would a doc rule have prevented it, and is it likely to happen again? If either answer is no, the event is dropped. For example, user errors, one-off denials, scope changes, transient failures, and case-specific corrections are excluded.
For example, "all REST endpoints use kebab-case" is a doc gap, but "no, I meant the other endpoint" is not.</p>
</div>
<div class="paragraph">
<p>Each event must also name a specific target file (e.g., <code>docs/api-guidelines.md</code>) and state the missing rule in a few sentences max.
Otherwise it is excluded.</p>
</div>
</div>
<div class="sect3">
<h4 id="friction-event-format">Friction event format</h4>
<div class="paragraph">
<p>For each event, the script writes a markdown file to <code>.claude/friction/{session-id}/</code>.
These files accumulate silently across sessions.
Sessions with zero friction produce no files.</p>
</div>
<div class="listingblock">
<div class="title">.claude/friction/{session-id}/&lt;event-name&gt;.md</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown"><span class="nn">---</span>
<span class="na">type</span><span class="pi">:</span> <span class="s">correction</span>
<span class="na">doc_gap</span><span class="pi">:</span> <span class="s">docs/api-guidelines.md</span>
<span class="na">date</span><span class="pi">:</span> <span class="s">2026-05-19</span>
<span class="nn">---</span>

The agent used snake_case for a new REST endpoint path. The user corrected it to kebab-case,
which is the convention for all API routes in this project.</code></pre>
</div>
</div>
</div>
</div>
<div class="sect2">
<h3 id="the-startup-reminder">The startup reminder</h3>
<div class="paragraph">
<p>On the next session start, a <code>SessionStart</code> hook runs the <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/setup-friction-capture/scripts/friction-reminder.sh" target="_blank" rel="noopener">friction-reminder.sh</a> script to check how many sessions have unprocessed friction:</p>
</div>
<div class="listingblock">
<div class="title">.claude/settings.json</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"hooks"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"SessionStart"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="p">{</span><span class="w">
        </span><span class="nl">"matcher"</span><span class="p">:</span><span class="w"> </span><span class="s2">""</span><span class="p">,</span><span class="w">
        </span><span class="nl">"hooks"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
          </span><span class="p">{</span><span class="w">
            </span><span class="nl">"type"</span><span class="p">:</span><span class="w"> </span><span class="s2">"command"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"command"</span><span class="p">:</span><span class="w"> </span><span class="s2">"bash .claude/scripts/friction-reminder.sh"</span><span class="p">,</span><span class="w">
            </span><span class="nl">"timeout"</span><span class="p">:</span><span class="w"> </span><span class="mi">2000</span><span class="w">
          </span><span class="p">}</span><span class="w">
        </span><span class="p">]</span><span class="w">
      </span><span class="p">}</span><span class="w">
    </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Once a configurable threshold is reached (default: 3 sessions), Claude Code displays a reminder at startup:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown">╔══════════════════════════════════════════════════╗
║  🤖 BEEP BOOP IMPORTANT MESSAGE                  ║
╠══════════════════════════════════════════════════╣
║                                                  ║
║  5 sessions, 12 stumbles. I'm not proud.         ║
║  Update the docs. For both our sakes.            ║
║                                                  ║
║  → /update-context-docs                          ║
║                                                  ║
║  Not your thing? Run /disable-friction-capture.  ║
╚══════════════════════════════════════════════════╝</code></pre>
</div>
</div>
<div class="paragraph">
<p>The messages rotate randomly from a set of five.
Nothing is blocked. The developer can ignore the reminder, act on it by running <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/update-context-docs/SKILL.md" target="_blank" rel="noopener"><code>/update-context-docs</code></a>, or opt out entirely with <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/disable-friction-capture/SKILL.md" target="_blank" rel="noopener"><code>/disable-friction-capture</code></a>.</p>
</div>
</div>
<div class="sect2">
<h3 id="turning-friction-into-doc-edits">Turning friction into doc edits</h3>
<div class="paragraph">
<p>When the developer runs <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/update-context-docs/SKILL.md" target="_blank" rel="noopener"><code>/update-context-docs</code></a>, the skill first checks for toolkit updates and lets the developer decide whether to install them. If an update changes a skill definition, Claude Code needs to be restarted before it can continue. Otherwise, the skill proceeds to process the accumulated friction files.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Each time <code>/update-context-docs</code> detects a new toolkit version, it <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/setup-friction-capture/scripts/install-friction-capture.sh" target="_blank" rel="noopener">re-downloads and executes scripts</a> from GitHub with no integrity verification. This is fine for a demo but would need checksums or signatures for production use.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The skill groups events by target file and presents a numbered list. The developer can exclude any that look like noise.</p>
</div>
<div class="paragraph">
<p>For each remaining event, the skill assesses severity (low, medium, or high), edits the target doc, and enforces a 200-line cap per file. It only touches files that already exist and follows their existing formatting.</p>
</div>
<div class="paragraph">
<p>If a <a href="https://www.promptfoo.dev/docs/intro/" target="_blank" rel="noopener"><code>promptfoo.yaml</code></a> file exists in the repo, the skill can also propose eval test cases based on the friction events.</p>
</div>
<div class="paragraph">
<p>The skill then creates a branch, commits, and opens a pull request with a friction metrics summary:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown"><span class="gu">## Friction Metrics</span>

<span class="gu">### Events</span>

|      Type      | Count |
|----------------|-------|
| Corrections    |   2   |
| Clarifications |   1   |
| Denials        |   1   |
| Mistakes       |   1   |
| <span class="gs">**Total**</span>      | <span class="gs">**5**</span> |

<span class="gu">### Outcomes</span>

|      Result      | Count |
|------------------|-------|
| Docs improved    |   3   |
| Eval cases added |   1   |
| Skipped by user  |   1   |

<span class="gs">**Docs improved:**</span> <span class="sb">`docs/api-guidelines.md`</span>, <span class="sb">`AGENTS.md`</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>After processing, the friction files are deleted from <code>.claude/friction/</code>.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="configuration">Configuration</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Set the following variables under the <code>env</code> key in <code>.claude/settings.json</code> for team-wide use, or in <code>.claude/settings.local.json</code> to keep them local.</p>
</div>
<table class="tableblock frame-all grid-all fit-content stretch">
<colgroup>
<col>
<col>
<col>
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">Variable</th>
<th class="tableblock halign-left valign-top">Description</th>
<th class="tableblock halign-left valign-top">Default</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>FRICTION_CAPTURE</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Controls whether friction capture is active. Run <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/disable-friction-capture/SKILL.md" target="_blank" rel="noopener"><code>/disable-friction-capture</code></a> to opt out locally in a repo where friction capture is enabled.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>1</code> (enabled)</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>FRICTION_SESSION_THRESHOLD</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Number of sessions with unprocessed friction before the startup reminder is displayed in Claude Code.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>3</code></p></td>
</tr>
</tbody>
</table>
</div>
</div>
<div class="sect1">
<h2 id="try-it-yourself">Try it yourself</h2>
<div class="sectionbody">
<div class="paragraph">
<p>All skills and scripts described in this post and the <a href="/2026/05/28/the-docs-your-ai-agent-is-missing" target="_blank" rel="noopener">previous one</a> are available as a Claude Code plugin in the <a href="https://github.com/gwenneg/blog-ai-friction-loop" target="_blank" rel="noopener">gwenneg/blog-ai-friction-loop</a> repository.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This repository is intended for experimentation. The toolkit periodically re-downloads and executes scripts from GitHub with no signature verification. If the repository or a release were compromised, malicious code would run on the developer&#8217;s machine at the next update. Do not use it on projects with sensitive or proprietary code until artifact signing is in place.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Clone it and start Claude Code with the plugin from your target project:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">git clone https://github.com/gwenneg/blog-ai-friction-loop.git
<span class="nb">cd</span> /path/to/your-project
claude <span class="nt">--plugin-dir</span> /path/to/blog-ai-friction-loop</code></pre>
</div>
</div>
<div class="paragraph">
<p>Then run <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/setup-friction-capture/SKILL.md" target="_blank" rel="noopener"><code>/setup-friction-capture</code></a>, which handles the full installation:</p>
</div>
<div class="olist arabic">
<ol class="arabic">
<li>
<p>Downloads the scripts and skill definitions from the latest <a href="https://github.com/gwenneg/blog-ai-friction-loop/releases" target="_blank" rel="noopener">gwenneg/blog-ai-friction-loop release</a></p>
</li>
<li>
<p>Installs the <code>SessionStart</code> and <code>SessionEnd</code> hooks shown earlier into <code>.claude/settings.json</code></p>
</li>
<li>
<p>Updates <code>.gitignore</code> with an allowlist pattern for the <code>.claude/</code> directory</p>
</li>
<li>
<p>Commits everything and opens a PR</p>
</li>
</ol>
</div>
<div class="paragraph">
<p>The <code>.claude/</code> directory mixes things that should be committed (hooks, scripts, skills, shared settings) with things that should never be (friction logs, local settings, worktrees, lock files).
The allowlist pattern looks like this:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="gitignore">/.claude/* <i class="conum" data-value="1"></i><b>(1)</b>
!/.claude/settings.json <i class="conum" data-value="2"></i><b>(2)</b>
!/.claude/scripts/ <i class="conum" data-value="3"></i><b>(3)</b>
!/.claude/skills/ <i class="conum" data-value="4"></i><b>(4)</b>
!/.claude/.friction-capture-version <i class="conum" data-value="5"></i><b>(5)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Ignore everything in <code>.claude/</code> by default.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Shared settings are committed so the team gets the same hooks.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>Scripts are committed so the hooks work for everyone.</td>
</tr>
<tr>
<td><i class="conum" data-value="4"></i><b>4</b></td>
<td>Skills provide <code>/update-context-docs</code> and <code>/disable-friction-capture</code> to all developers.</td>
</tr>
<tr>
<td><i class="conum" data-value="5"></i><b>5</b></td>
<td>Tracks the installed toolkit version for update detection.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The PR includes a note for reviewers about what data is sent and how to opt out.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-next">What&#8217;s next</h2>
<div class="sectionbody">
<div class="paragraph">
<p>As AI agents take on more of the coding work, keeping context docs accurate becomes critical. Friction will always exist. The question is whether it gets captured and fixed, or silently repeated across sessions.</p>
</div>
<div class="paragraph">
<p>I&#8217;m deploying this across several repositories at Red Hat and collecting feedback. This is one approach to the problem, and I expect it to change as teams adapt it to their own workflows.</p>
</div>
<div class="paragraph">
<p>The capture is purely reactive right now: it catches what went wrong, not what could go wrong. A major refactor can silently invalidate parts of the guidelines, and the loop only notices once an agent stumbles. That&#8217;s a known gap and something I want to address.</p>
</div>
<div class="paragraph">
<p>I&#8217;m also working on the developer experience, exploring ways to further minimize the effort required from devs while keeping the docs updated automatically. That could eventually mean getting rid of the manual step entirely.</p>
</div>
<div class="paragraph">
<p>If you try this or build something different, I&#8217;d love to hear about it. What breaks, what works, and what the next step looks like for your team.
Feel free to share in the comments.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="agents.md" /><category term="ai" /><category term="claude code" /><category term="context engineering" /><category term="developer experience" /><category term="documentation" /><summary type="html"><![CDATA[An experiment using automated friction capture to continuously improve AI context docs, fixing both codebase drift and gaps in initially generated content.]]></summary></entry><entry><title type="html">The docs your AI agent is missing</title><link href="https://gwenneg.github.io/2026/05/28/the-docs-your-ai-agent-is-missing.html" rel="alternate" type="text/html" title="The docs your AI agent is missing" /><published>2026-05-28T00:00:00+02:00</published><updated>2026-05-28T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/05/28/the-docs-your-ai-agent-is-missing</id><content type="html" xml:base="https://gwenneg.github.io/2026/05/28/the-docs-your-ai-agent-is-missing.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>In LangChain&#8217;s <a href="https://www.langchain.com/state-of-agent-engineering" target="_blank" rel="noopener">2026 survey of 1,300 AI professionals</a>, large enterprises cited context engineering and managing context at scale as one of their biggest challenges in ensuring agent quality.
The term "context engineering" is barely a year old, and most organizations are still figuring it out.</p>
</div>
<div class="paragraph">
<p>The challenge is no longer whether AI can write code.
It&#8217;s whether it knows enough about <em>your</em> project to write the right code.
And even when teams invest in writing context docs, keeping them accurate is its own problem.
A <a href="https://arxiv.org/pdf/2510.21413" target="_blank" rel="noopener">study of 10,000 open-source repositories</a> found that half of the <code>AGENTS.md</code> files it identified were never modified after creation.</p>
</div>
<div class="paragraph">
<p>I&#8217;ve been experimenting with this at Red Hat, trying different ways to structure and maintain context docs for AI agents.
In this post, I&#8217;ll walk through <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/init-context-docs/SKILL.md" target="_blank" rel="noopener">a Claude Code skill</a> I built to help bootstrap the documentation agents need to work effectively on a project.
Here&#8217;s a before/after on a real project:</p>
</div>
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/the-docs-your-ai-agent-is-missing/before-after.png" alt="Before/after comparison" width="90%"></span></p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>An agent can get context from many sources: static files loaded at startup, dynamic retrieval (RAG), memory systems and more.
This post only covers the first: repo-level documentation that describes conventions, pitfalls, architectural decisions and other project knowledge not visible in the code.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="initiating-context-docs-with-a-claude-skill">Initiating context docs with a Claude skill</h2>
<div class="sectionbody">
<div class="paragraph">
<p>The <code>/init-context-docs</code> skill assesses a repository&#8217;s readiness for AI-assisted development, then bootstraps a layered set of context files.
While <code>AGENTS.md</code> and the guideline files work with any tool that supports the standard, the loading behaviors described here are specific to Claude Code:</p>
</div>
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 25%;">
<col style="width: 50%;">
<col style="width: 25%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">File</th>
<th class="tableblock halign-left valign-top">Role</th>
<th class="tableblock halign-left valign-top">Loading behavior</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>docs/*-guidelines.md</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Domain-specific guidelines (e.g., security, testing, database). Capped at 200 lines.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">At Claude&#8217;s discretion via <code>AGENTS.md</code> index</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>AGENTS.md</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Cross-cutting conventions and index to guideline files. Agent-agnostic. Capped at 200 lines.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">At Claude&#8217;s discretion by default; unconditional when imported via <code>@AGENTS.md</code> in <code>CLAUDE.md</code></p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>.claude/rules/*.md</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Path-scoped loaders that force a guideline into context for matching files.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Path-scoped deterministic load</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>CLAUDE.md</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Thin Claude Code-specific layer. Imports <code>AGENTS.md</code> via <code>@AGENTS.md</code>. Capped at 100 lines.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Unconditional load (every session)</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><code>README.md</code></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">High-level project context for humans and agents alike.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">At Claude&#8217;s discretion</p></td>
</tr>
</tbody>
</table>
<div class="paragraph">
<div class="title">Context docs loading layers</div>
<p><span class="image"><img src="/assets/images/posts/the-docs-your-ai-agent-is-missing/context-docs-loading-layers.svg" alt="Context docs loading layers" width="85%"></span></p>
</div>
<div class="paragraph">
<p>The unconditional layer is the most expensive in terms of context window tokens: it&#8217;s loaded every session regardless of the task.
Files loaded at Claude&#8217;s discretion are the cheapest, but come with no guarantee.
Path-scoped rules sit in between: deterministic loading, but only for matching files.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="why-size-and-ordering-matter">Why size and ordering matter</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Several studies point in the same direction: longer context alone hurts LLM performance, even when the content is relevant (<a href="https://arxiv.org/pdf/2510.05381" target="_blank" rel="noopener">Du et al., 2025</a>).
Models pay the most attention to the beginning and end of their input; everything in the middle gets less (<a href="https://arxiv.org/pdf/2307.03172" target="_blank" rel="noopener">Liu et al., 2024</a>; <a href="https://arxiv.org/pdf/2502.01951" target="_blank" rel="noopener">Wu et al., 2025</a>).
Anthropic frames context as <a href="https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents" target="_blank" rel="noopener">"a precious, finite resource"</a>.
On the flip side, well-formed <code>AGENTS.md</code> files are associated with ~29% faster execution (<a href="https://arxiv.org/pdf/2601.20404" target="_blank" rel="noopener">Lulla et al., 2026</a>).
But more isn&#8217;t better: LLM-generated context files with unnecessary content actually reduce task success rates compared to no context at all (<a href="https://arxiv.org/pdf/2602.11988" target="_blank" rel="noopener">Gloaguen et al., 2026</a>).</p>
</div>
<div class="paragraph">
<p>This is why every file in the system is capped (200 lines for guidelines and <code>AGENTS.md</code>, 100 for <code>CLAUDE.md</code>), the most critical rules go first, verification commands go last, and everything in between is kept ruthlessly short.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="why-each-layer-matters">Why each layer matters</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Every layer is a tradeoff between loading guarantee and token cost. The question for each file is: does the agent need this every session, only for certain files, or only sometimes?</p>
</div>
<div class="sect2">
<h3 id="guidelines">Guidelines</h3>
<div class="paragraph">
<p>This is the deepest layer: concrete rules about how <em>this</em> codebase does things (e.g., "use <code>middleware/validator.ts</code> for input validation"), not general best practices (e.g., "always validate user input").
Each guideline targets a specific domain (e.g., security, testing, database), determined dynamically based on what the skill finds in the repo.</p>
</div>
<div class="paragraph">
<p>Anthropic calls self-verification <a href="https://code.claude.com/docs/en/best-practices#give-claude-a-way-to-verify-its-work" target="_blank" rel="noopener">"the single highest-leverage thing you can do"</a>, so every guideline ends with a Verification section listing commands the agent can run to check its own work.</p>
</div>
</div>
<div class="sect2">
<h3 id="agents-md">AGENTS.md</h3>
<div class="paragraph">
<p><a href="https://agents.md/" target="_blank" rel="noopener">AGENTS.md</a> is an open standard stewarded by the Linux Foundation, supported by all major AI coding tools and adopted by 60K+ open-source projects.
It serves as the agent-agnostic onboarding doc: cross-cutting conventions plus an index pointing to the detailed guidelines.</p>
</div>
<div class="paragraph">
<p>Claude uses this index to decide which guidelines to load based on the current task.
This is a judgment call by the agent, not a guaranteed mechanism.
In practice, Claude sometimes skips a guideline it should have loaded, especially when the relevance isn&#8217;t obvious from the file names alone.
Path-scoped rules (covered below) exist to address that.</p>
</div>
</div>
<div class="sect2">
<h3 id="path-scoped-rules">Path-scoped rules</h3>
<div class="paragraph">
<p><code>.claude/rules/*.md</code> files let you force a guideline into context only when Claude works with matching files.
This addresses the gap mentioned above: when Claude&#8217;s own judgment about which guidelines to load isn&#8217;t reliable enough, a rule makes the loading deterministic.</p>
</div>
<div class="listingblock">
<div class="title">.claude/rules/testing.md</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown">paths:
<span class="p">  -</span> "<span class="gs">**/test/**</span>"

@docs/testing-guidelines.md</code></pre>
</div>
</div>
<div class="paragraph">
<p>The benefit is precision: a guideline only consumes tokens when the agent actually needs it.</p>
</div>
<div class="paragraph">
<p>But use rules sparingly.
Broad globs like <code>**/*</code> make a guideline effectively always-loaded. Multiple rules can stack up on the same file.
Patterns can go stale if the codebase restructures.
And rules are Claude Code-specific; other tools don&#8217;t support them.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>If <code>.claude/rules/</code> is gitignored, rules won&#8217;t be committed and other developers won&#8217;t benefit from them.
Make sure the rules directory is explicitly allowed in your <code>.gitignore</code>.
The skill checks for this and offers to add an exception.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="claude-md">CLAUDE.md</h3>
<div class="paragraph">
<p>This is the thinnest layer: only what applies exclusively to Claude Code.
It&#8217;s loaded unconditionally at the start of every session, so every line consumes context window tokens regardless of the task.
Anthropic&#8217;s guidance is blunt: <a href="https://code.claude.com/docs/en/best-practices#write-an-effective-claude-md" target="_blank" rel="noopener">"Bloated CLAUDE.md files cause Claude to ignore your actual instructions!"</a></p>
</div>
<div class="paragraph">
<p>Adding <code>@AGENTS.md</code> near the top guarantees Claude always has the agent guidance available.
Without it, Claude may or may not read <code>AGENTS.md</code> on its own. Loading is not guaranteed.
The tradeoff: the import makes loading deterministic, at the cost of consuming <code>AGENTS.md</code> tokens unconditionally every session.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Avoid importing guideline files directly from <code>CLAUDE.md</code>.
That would make them always-loaded, defeating the on-demand architecture the rest of the system is built around.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="readme">README</h3>
<div class="paragraph">
<p>A well-structured README can answer "what does this project do and how do I build it?" without the agent exploring dozens of files.
The skill generates one that front-loads the essentials (project purpose, tech stack, build instructions) and links to <code>AGENTS.md</code> and <code>docs/</code> for the deeper layers.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="how-the-skill-works">How the skill works</h2>
<div class="sectionbody">
<div class="paragraph">
<div class="title">Skill execution flow</div>
<p><span class="image"><img src="/assets/images/posts/the-docs-your-ai-agent-is-missing/skill-execution-flow.svg" alt="Skill execution flow" width="85%"></span></p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>At each phase, the skill asks whether to proceed, lets you skip layers, and offers customization before generating anything.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The skill starts by scanning the repo against the five layers described above and presents a baseline status showing what already exists and what&#8217;s missing.
It then matches the repo against a curated list of guideline domains (e.g., security, testing, database), drops any that aren&#8217;t relevant, identifies additional domains not on the list (e.g., GraphQL, machine learning), and lets you adjust the final selection.</p>
</div>
<div class="paragraph">
<p>Once the domains selection is final, the skill launches one generation agent per domain, each focused exclusively on its area.
An agent that only needs to produce a testing guideline can dig deep into your test patterns, rather than spreading its attention across the entire project.
The same pattern applies to <code>AGENTS.md</code>, <code>CLAUDE.md</code>, and <code>README</code>: each gets its own generation agent.
If a file already exists, the generation agent reads the existing content first and incorporates it, updating with new findings while preserving what&#8217;s still accurate.</p>
</div>
<div class="paragraph">
<p>Each generation agent reads a <a href="https://github.com/gwenneg/blog-ai-friction-loop/tree/main/skills/init-context-docs/checklists" target="_blank" rel="noopener">quality checklist</a> before writing anything.
The checklists enforce constraints like the 200-line cap, the necessity test ("Would removing this cause an agent to make a mistake?"), a ban on absolute language without evidence, and the requirement that every file reference actually exists in the codebase.
Generation and verification agents share the same checklists, so both are measured against the same standard.</p>
</div>
<div class="paragraph">
<p>A separate agent handles verification. The one that wrote the content is biased toward believing it&#8217;s correct: research shows that <a href="https://arxiv.org/pdf/2404.13076" target="_blank" rel="noopener">LLMs systematically favor their own output</a> (Panickssery et al., 2024) and <a href="https://arxiv.org/pdf/2507.02778" target="_blank" rel="noopener">fail to correct their own errors</a> while successfully correcting identical ones from external sources (Tsui, 2025).
There&#8217;s a catch, though: both studies examine self-bias within a single model.
The skill uses a different model for verification (Sonnet instead of Opus), but both belong to the same Claude family, so some bias may carry over.
Still, a fresh agent with a clean context checks file references against the actual codebase, validates factual claims with <code>WebSearch</code>, looks for contradictions across files, and flags duplication across layers.
It only corrects inaccuracies.
It doesn&#8217;t add new content.</p>
</div>
<div class="paragraph">
<p>After all agents finish, an <a href="https://github.com/gwenneg/blog-ai-friction-loop/blob/main/skills/init-context-docs/scripts/automated-checks.sh" target="_blank" rel="noopener"><code>automated-checks.sh</code></a> script validates the generated files (line counts, imports, docs index, secret detection) and re-runs until all checks pass.</p>
</div>
<div class="paragraph">
<p>The skill finally offers to create a pull request with all the changes, so the generated docs go through the team&#8217;s normal review process.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="try-it-yourself">Try it yourself</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Want to see how this works on your own project? Clone the <a href="https://github.com/gwenneg/blog-ai-friction-loop" target="_blank" rel="noopener">gwenneg/blog-ai-friction-loop</a> repository, then start Claude Code with the plugin from your target project:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">git clone https://github.com/gwenneg/blog-ai-friction-loop.git
<span class="nb">cd</span> /path/to/your-project
claude <span class="nt">--plugin-dir</span> /path/to/blog-ai-friction-loop</code></pre>
</div>
</div>
<div class="paragraph">
<p>Then type <code>/init-context-docs</code>.
The skill will walk you through each layer, ask what to include, and let you skip anything that doesn&#8217;t apply.
Expect it to take anywhere from a few minutes to about half an hour depending on the size of your codebase.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="whats-next">What&#8217;s next</h2>
<div class="sectionbody">
<div class="paragraph">
<p>In my own testing, the generated docs clearly improved how agents work with projects: fewer wrong assumptions, less time spent correcting output.
I don&#8217;t have metrics to back that up yet.
It&#8217;s based on what I observed across a handful of repositories.</p>
</div>
<div class="paragraph">
<p>But even after all of this, the output is imperfect.
Guidelines can sound plausible while being wrong about specifics, and some conventions only reveal themselves when the agent actually tries to follow the docs.</p>
</div>
<div class="paragraph">
<p>These are <em>friction events</em>, moments where the docs failed the agent:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>The user corrected the agent&#8217;s output</p>
</li>
<li>
<p>The agent asked a question the docs should have answered</p>
</li>
<li>
<p>The agent made a wrong assumption about the codebase</p>
</li>
<li>
<p>A tool call was denied because it violated a project policy the agent didn&#8217;t know about</p>
</li>
</ul>
</div>
<div class="paragraph">
<p>Each one is a signal that the docs have a gap, something a concrete rule or example could have prevented.</p>
</div>
<div class="paragraph">
<p>In a <a href="/2026/05/31/turn-ai-friction-into-better-docs" target="_blank" rel="noopener">follow-up post</a>, I introduce an experiment to capture these friction events automatically at the end of every session and turn them into targeted doc improvements.</p>
</div>
<div class="paragraph">
<p>If you try <code>/init-context-docs</code> on your own codebase, I&#8217;m curious what it gets right, what it misses, and what you end up changing.
Feel free to share your experience in the comments.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="sources">Sources</h2>
<div class="sectionbody">
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 60%;">
<col style="width: 20%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">Source</th>
<th class="tableblock halign-left valign-top">Author</th>
<th class="tableblock halign-left valign-top">Date</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2602.11988" target="_blank" rel="noopener">Evaluating AGENTS.md: Are Repository-Level Context Files Helpful for Coding Agents?</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Gloaguen et al. (ETH Zurich)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Feb 2026</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2601.20404" target="_blank" rel="noopener">On the Impact of AGENTS.md Files on the Efficiency of AI Coding Agents</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Lulla et al.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Jan 2026</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://www.langchain.com/state-of-agent-engineering" target="_blank" rel="noopener">State of Agent Engineering</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">LangChain</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Early 2026</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2510.21413" target="_blank" rel="noopener">Context Engineering for AI Agents in Open-Source Software</a> (peer-reviewed, MSR 2026)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Mohsenimofidi et al.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Oct 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2510.05381" target="_blank" rel="noopener">Context Length Alone Hurts LLM Performance Despite Perfect Retrieval</a> (peer-reviewed, EMNLP Findings 2025)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Du et al.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Oct 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents" target="_blank" rel="noopener">Effective Context Engineering for AI Agents</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Anthropic</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Sep 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://agents.md/" target="_blank" rel="noopener">AGENTS.md open standard</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Linux Foundation</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Aug 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2507.02778" target="_blank" rel="noopener">Self-Correction Bench: Uncovering and Addressing the Self-Correction Blind Spot in Large Language Models</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Tsui</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Jul 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://code.claude.com/docs/en/best-practices" target="_blank" rel="noopener">Best practices for Claude Code</a></p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Anthropic</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">May 2025 (updated regularly)</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2502.01951" target="_blank" rel="noopener">On the Emergence of Position Bias in Transformers</a> (peer-reviewed, ICML 2025)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Wu et al. (MIT)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Feb 2025</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2404.13076" target="_blank" rel="noopener">LLM Evaluators Recognize and Favor Their Own Generations</a> (peer-reviewed, NeurIPS 2024)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Panickssery et al.</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Apr 2024</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock"><a href="https://arxiv.org/pdf/2307.03172" target="_blank" rel="noopener">Lost in the Middle: How Language Models Use Long Contexts</a> (peer-reviewed, TACL 2024)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Liu et al. (Stanford)</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Feb 2024</p></td>
</tr>
</tbody>
</table>
</div>
</div>
<div class="sect1">
<h2 id="special-thanks">Special thanks</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Thanks to Jiří Bönsch for helping me test and improve the <code>/init-context-docs</code> skill.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="agents.md" /><category term="ai" /><category term="claude code" /><category term="context engineering" /><category term="developer experience" /><category term="documentation" /><summary type="html"><![CDATA[A Claude Code skill that builds the context docs your AI agent needs, backed by research on how LLMs process context.]]></summary></entry><entry><title type="html">Teaching Claude Code skills to improve themselves</title><link href="https://gwenneg.github.io/2026/05/04/self-improving-claude-code-skills.html" rel="alternate" type="text/html" title="Teaching Claude Code skills to improve themselves" /><published>2026-05-04T00:00:00+02:00</published><updated>2026-05-04T00:00:00+02:00</updated><id>https://gwenneg.github.io/2026/05/04/self-improving-claude-code-skills</id><content type="html" xml:base="https://gwenneg.github.io/2026/05/04/self-improving-claude-code-skills.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post was written with the help of AI.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>I&#8217;ve been so deep into AI tooling lately that blogging fell off the radar&#8201;&#8212;&#8201;things move too fast to stop and write about them.
But this one is such a quick win that I had to share it, even if someone else has probably had the same idea before.</p>
</div>
<div class="paragraph">
<p>If you&#8217;re using <a href="https://docs.anthropic.com/en/docs/claude-code/skills" target="_blank" rel="noopener">Claude Code skills</a>, you&#8217;ve probably noticed that getting them right takes a few iterations.
A skill might miss a step, produce something slightly off, or lack context that your <code>CLAUDE.md</code> should have provided.
The usual fix is to notice the problem, remember to update the skill later, and then&#8230;&#8203; forget about it.</p>
</div>
<div class="paragraph">
<p>What if the skill itself could flag those issues for you?</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="the-idea">The idea</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Add an optional final step to your skills that asks Claude to look back at what just happened and suggest improvements.
Not to the code it produced&#8201;&#8212;&#8201;to the skill definition, <code>CLAUDE.md</code>, or any other project documentation that would have made the execution smoother.</p>
</div>
<div class="paragraph">
<p>Think of it as a mini retrospective that runs every time, at near-zero cost.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="the-instruction">The instruction</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Here&#8217;s what I append to my skills:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="markdown"><span class="gu">## Optional: Self-Improvement Review</span>

After completing the skill, use AskUserQuestion to ask the user if they want to run the self-improvement review.

If they decline, skip it entirely.

If they accept, reflect on your execution:
<span class="p">
-</span> Did anything fail, feel awkward, or require unnecessary retries?
<span class="p">-</span> Were you missing context that CLAUDE.md or another project doc should have provided?
<span class="p">-</span> Is there a step in this skill that was unclear, redundant, or in the wrong order?

If you identify a concrete improvement, present it as a <span class="gs">**diff to the relevant file**</span> (skill definition, CLAUDE.md, AGENTS.md, etc.) and offer to apply it. Do NOT just list observations — every finding must come with an actionable diff.
Do not apply changes without approval.
If nothing stands out, say so briefly and move on — do not force feedback.</code></pre>
</div>
</div>
<div class="paragraph">
<p>A few things worth noting:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Asking for a <strong>diff</strong> prevents vague suggestions like "consider improving the error handling step." It forces something actionable.</p>
</li>
<li>
<p>The "if nothing stands out, move on" line is important. Without it, Claude will invent problems to fill the step every single time.</p>
</li>
<li>
<p>The scope covers both the skill <em>and</em> project docs. A skill might work perfectly but still struggle because <code>CLAUDE.md</code> is missing a convention or a path.</p>
</li>
</ul>
</div>
</div>
</div>
<div class="sect1">
<h2 id="does-it-actually-work">Does it actually work?</h2>
<div class="sectionbody">
<div class="paragraph">
<p>In my experience, most executions produce no suggestion&#8201;&#8212;&#8201;which is the right outcome.
But when it does flag something, it&#8217;s usually a missing convention in <code>CLAUDE.md</code> or a step in the skill that assumed context Claude didn&#8217;t have.
Those are exactly the kind of issues you&#8217;d never bother tracking down yourself.</p>
</div>
<div class="paragraph">
<p>It won&#8217;t revolutionize your workflow, but it&#8217;s a small investment that compounds over time.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="ai" /><category term="claude code" /><summary type="html"><![CDATA[A simple instruction you can append to your Claude Code skills to make them suggest improvements to themselves and your project docs.]]></summary></entry><entry><title type="html">Easing the maintenance of Konflux build pipelines</title><link href="https://gwenneg.github.io/2025/04/11/konflux-remote-pipeline.html" rel="alternate" type="text/html" title="Easing the maintenance of Konflux build pipelines" /><published>2025-04-11T00:00:00+02:00</published><updated>2025-04-11T00:00:00+02:00</updated><id>https://gwenneg.github.io/2025/04/11/konflux-remote-pipeline</id><content type="html" xml:base="https://gwenneg.github.io/2025/04/11/konflux-remote-pipeline.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="paragraph">
<p><a href="https://konflux-ci.dev" target="_blank" rel="noopener">Konflux</a> is an open source, cloud-native software factory developed by Red Hat and focused on software supply chain security.</p>
</div>
<div class="paragraph">
<p>When a component is <a href="https://konflux-ci.dev/docs/building/creating" target="_blank" rel="noopener">onboarded to Konflux</a>, the <a href="https://github.com/apps/red-hat-konflux" target="_blank" rel="noopener">Red Hat Konflux app</a> automatically creates two build pipelines in the Git repository:</p>
</div>
<div class="ulist">
<ul>
<li>
<p><code>${component.name}-pull-request.yaml</code></p>
</li>
<li>
<p><code>${component.name}-push.yaml</code></p>
</li>
</ul>
</div>
<div class="paragraph">
<p>Then, every once in a while, <a href="https://github.com/konflux-ci/mintmaker" target="_blank" rel="noopener">MintMaker</a> — a Konflux hosted instance of the <a href="https://github.com/renovatebot/renovate" target="_blank" rel="noopener">Renovate bot</a> — will open PRs to update the Konflux task references in the pipelines.
Some of these PRs may also include <a href="https://github.com/RedHatInsights/konflux-pipelines/pull/58" target="_blank" rel="noopener">migration notes</a> and require additional work.</p>
</div>
<div class="paragraph">
<p>If you&#8217;re managing multiple repositories onboarded to Konflux, keeping all the pipelines up to date can require significant effort over time.
In this post, I&#8217;ll show you different ways to make pipeline maintenance easier by using remote pipelines and tweaking MintMaker&#8217;s settings.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>This post includes multiple references to the <a href="https://github.com/RedHatInsights/konflux-pipelines" target="_blank" rel="noopener">RedHatInsights/konflux-pipelines</a> repository.
If you&#8217;re not a member of the RedHatInsights organization on GitHub, please consider forking the repository before using the remote pipelines it contains, as they may be modified at any time without prior notice.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="introducing-remote-pipelines">Introducing remote pipelines</h2>
<div class="sectionbody">
<div class="paragraph">
<p><a href="https://tekton.dev/docs/pipelines/resolution" target="_blank" rel="noopener">Remote pipelines</a> from Tekton let you reference pipeline definitions stored in external Git repositories instead of defining them locally in each project.
They make it easier to share and maintain pipelines across multiple repositories.</p>
</div>
<div class="paragraph">
<p>Konflux is built on top of Tekton.
Let&#8217;s see how we can leverage remote pipelines in a Konflux build pipeline!</p>
</div>
<div class="paragraph">
<p>Nothing shows it better than a good PR: <a href="https://github.com/gwenneg/blog-remote-konflux-pipeline/pull/2/files" target="_blank" rel="noopener">gwenneg/blog-remote-konflux-pipeline#2</a>.
If you don&#8217;t have time to review the whole thing, here&#8217;s the TL;DR:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">tekton.dev/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">PipelineRun</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">annotations</span><span class="pi">:</span>
    <span class="na">pipelinesascode.tekton.dev/pipeline</span><span class="pi">:</span> <span class="pi">&gt;</span> <i class="conum" data-value="1"></i><b>(1)</b>
      <span class="s">https://github.com/RedHatInsights/konflux-pipelines/raw/main/pipelines/docker-build-oci-ta.yaml</span>
    <span class="c1"># Additional annotations omitted for brevity</span>
  <span class="na">labels</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">remote-konflux-pipeline-on-pull-request</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">glepage-tenant</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">params</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span>
  <span class="na">pipelineRef</span><span class="pi">:</span> <i class="conum" data-value="2"></i><b>(2)</b>
    <span class="na">name</span><span class="pi">:</span> <span class="s">docker-build-oci-ta</span> <i class="conum" data-value="3"></i><b>(3)</b>
  <span class="na">workspaces</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>This annotation comes from <a href="https://pipelinesascode.com/docs/guide/resolver/#remote-pipeline-annotations" target="_blank" rel="noopener">Pipelines as Code</a> and references a remote pipeline from the <a href="https://github.com/RedHatInsights/konflux-pipelines" target="_blank" rel="noopener">RedHatInsights/konflux-pipelines</a> repository.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>The entire <code>pipelineSpec</code> section from the default Konflux pipeline is replaced with a minimal <code>pipelineRef</code> section.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>This value needs to match the <code>metadata.name</code> value from the remote pipeline.</td>
</tr>
</table>
</div>
<div class="sect2">
<h3 id="why-go-remote">Why go remote?</h3>
<div class="paragraph">
<p>After applying the changes shown above:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>MintMaker will no longer open PRs in your repository to update Konflux task references or request pipeline migrations.</p>
</li>
<li>
<p>Your pipeline runs will automatically depend on the latest version of the remote pipelines, thanks to the dependency on the <code>main</code> branch.</p>
</li>
<li>
<p>MintMaker will still open PRs unrelated to pipelines, such as <a href="https://github.com/RedHatInsights/sources-api-go/pull/835" target="_blank" rel="noopener">RedHatInsights/sources-api-go#835</a>, to update dependencies.</p>
</li>
</ul>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>If you want to test a change in a remote pipeline or roll back to an earlier version if something breaks, just point to a different Git branch or SHA.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="theres-a-catch">There&#8217;s a catch</h3>
<div class="paragraph">
<p>This approach almost entirely removes the need to maintain pipelines, but there&#8217;s a catch.
Since MintMaker won&#8217;t open PRs to update your pipelines anymore, any changes in the remote pipelines will go untested in your repository until you open another unrelated PR that triggers a pipeline run.</p>
</div>
<div class="paragraph">
<p>The next section explains how to work around this limitation.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="depending-on-a-specific-release-of-remote-pipelines">Depending on a specific release of remote pipelines</h2>
<div class="sectionbody">
<div class="paragraph">
<p>If the repository that hosts the remote pipelines publishes releases on GitHub, your repository can depend on a specific release instead of always using the latest version.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="yaml"><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">tekton.dev/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">PipelineRun</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">annotations</span><span class="pi">:</span>
    <span class="na">pipelinesascode.tekton.dev/pipeline</span><span class="pi">:</span> <span class="pi">&gt;</span> <i class="conum" data-value="1"></i><b>(1)</b>
      <span class="s">https://github.com/RedHatInsights/konflux-pipelines/raw/v1.2.0/pipelines/docker-build-oci-ta.yaml</span>
    <span class="c1"># Additional annotations omitted for brevity</span>
  <span class="na">labels</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">remote-konflux-pipeline-on-pull-request</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">glepage-tenant</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">params</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span>
  <span class="na">pipelineRef</span><span class="pi">:</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">docker-build-oci-ta</span>
  <span class="na">workspaces</span><span class="pi">:</span> <span class="s">...</span> <span class="c1"># Omitted for brevity</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The local pipeline now depends on version <code>v1.2.0</code> of the remote pipeline instead of <code>main</code>.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>With this approach:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>MintMaker will automatically open PRs such as <a href="https://github.com/gwenneg/blog-remote-konflux-pipeline/pull/4" target="_blank" rel="noopener">gwenneg/blog-remote-konflux-pipeline#4</a> in your repository every time a new release of the remote pipelines is published.</p>
</li>
<li>
<p>Any changes in the remote pipelines will be immediately tested in your repository and you will catch issues as early as possible.</p>
</li>
<li>
<p>You still won&#8217;t have to worry about Konflux task reference updates or pipeline migrations.</p>
</li>
</ul>
</div>
</div>
</div>
<div class="sect1">
<h2 id="customizing-mintmakers-settings">Customizing MintMaker&#8217;s settings</h2>
<div class="sectionbody">
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>You can use the tips from this section whether or not you&#8217;re using remote pipelines.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>MintMaker works out of the box in repositories onboarded to Konflux and doesn&#8217;t require any additional configuration files.
However, it is possible to customize MintMaker&#8217;s settings by adding a <a href="https://github.com/gwenneg/blog-remote-konflux-pipeline/blob/main/renovate.json" target="_blank" rel="noopener">renovate.json</a> file at the root of your repository.
The default configuration is detailed in the <a href="https://konflux-ci.dev/docs/mintmaker/default-config" target="_blank" rel="noopener">Konflux doc</a>.</p>
</div>
<div class="sect2">
<h3 id="changing-when-mintmaker-runs">Changing when MintMaker runs</h3>
<div class="paragraph">
<p>The Renovate configuration lets you control when and how often MintMaker may open PRs in your repository:</p>
</div>
<div class="listingblock">
<div class="title">renovate.json</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"$schema"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://docs.renovatebot.com/renovate-schema.json"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"extends"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"github&gt;konflux-ci/mintmaker//config/renovate/renovate.json"</span><span class="p">],</span><span class="w"> <i class="conum" data-value="1"></i><b>(1)</b>
  </span><span class="nl">"tekton"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"schedule"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"on Tuesday after 3am and before 10am"</span><span class="p">]</span><span class="w"> <i class="conum" data-value="2"></i><b>(2)</b>
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>This snippet extends <a href="https://github.com/konflux-ci/mintmaker/blob/main/config/renovate/renovate.json" class="bare" target="_blank" rel="noopener">https://github.com/konflux-ci/mintmaker/blob/main/config/renovate/renovate.json</a>.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Renovate supports both natural language and cron-based scheduling.
See the <a href="https://docs.renovatebot.com/configuration-options/#schedule" target="_blank" rel="noopener">Renovate doc</a> for more details.</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="automatically-approving-and-merging-mintmakers-prs">Automatically approving and merging MintMaker&#8217;s PRs</h3>
<div class="paragraph">
<p>You can also tweak your Renovate settings to automatically approve or <a href="https://github.com/gwenneg/blog-remote-konflux-pipeline/pull/11" target="_blank" rel="noopener">merge</a> PRs opened by MintMaker:</p>
</div>
<div class="listingblock">
<div class="title">renovate.json</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"$schema"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://docs.renovatebot.com/renovate-schema.json"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"extends"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"github&gt;konflux-ci/mintmaker//config/renovate/renovate.json"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"tekton"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"autoApprove"</span><span class="p">:</span><span class="w"> </span><span class="kc">true</span><span class="p">,</span><span class="w"> <i class="conum" data-value="1"></i><b>(1)</b>
    </span><span class="nl">"automerge"</span><span class="p">:</span><span class="w"> </span><span class="kc">true</span><span class="w"> <i class="conum" data-value="2"></i><b>(2)</b>
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Auto-approving only works in GitLab, not in GitHub. Find more details in the <a href="https://docs.renovatebot.com/configuration-options/#autoapprove" target="_blank" rel="noopener">Renovate doc</a>.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Auto-merging works in both GitHub and GitLab. Find more details in the <a href="https://docs.renovatebot.com/configuration-options/#automerge" target="_blank" rel="noopener">Renovate doc</a>.</td>
</tr>
</table>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="hosting-remote-konflux-pipelines">Hosting remote Konflux pipelines</h2>
<div class="sectionbody">
<div class="paragraph">
<p>If you plan on creating a repository to host remote pipelines, there are two things you&#8217;ll need to do:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Onboard the repository to Konflux as a component.</p>
</li>
<li>
<p>Let MintMaker know where to find the remote pipelines so it can keep them updated.</p>
</li>
</ul>
</div>
<div class="listingblock">
<div class="title">renovate.json</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="json"><span class="p">{</span><span class="w">
  </span><span class="nl">"$schema"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://docs.renovatebot.com/renovate-schema.json"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"extends"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"github&gt;konflux-ci/mintmaker//config/renovate/renovate.json"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"tekton"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"includePaths"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"pipelines/**"</span><span class="p">]</span><span class="w"> <i class="conum" data-value="1"></i><b>(1)</b>
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>By default, MintMaker only updates pipelines found in the <code>.tekton</code> folder.
To use a different location, you must specify where the remote pipelines are located.</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="special-thanks">Special thanks</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Special thanks to <a href="https://github.com/jpopelka" target="_blank" rel="noopener">Jiri Popelka</a> for suggesting the <a href="https://pipelinesascode.com/docs/guide/resolver/#remote-pipeline-annotations" target="_blank" rel="noopener">Pipelines as Code annotation</a> as an alternative to the <a href="https://tekton.dev/docs/pipelines/git-resolver/#pipeline-resolution" target="_blank" rel="noopener">Tekton Git resolver</a>.</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="konflux" /><summary type="html"><![CDATA[Maintaining Konflux pipelines doesn&#8217;t have to be a pain. I&#8217;ve got a few tips to help you out.]]></summary></entry><entry><title type="html">Why is my PostgreSQL query so slow?! Let’s fix it!</title><link href="https://gwenneg.github.io/2025/03/21/postgres-execution-time.html" rel="alternate" type="text/html" title="Why is my PostgreSQL query so slow?! Let’s fix it!" /><published>2025-03-21T00:00:00+01:00</published><updated>2025-03-21T00:00:00+01:00</updated><id>https://gwenneg.github.io/2025/03/21/postgres-execution-time</id><content type="html" xml:base="https://gwenneg.github.io/2025/03/21/postgres-execution-time.html"><![CDATA[<div id="preamble">
<div class="sectionbody">
<div class="paragraph">
<p><a href="https://www.postgresql.org/" target="_blank" rel="noopener">PostgreSQL</a> is pretty smart at running queries, but sometimes it needs a little help to hit top speed.
In this post, we&#8217;ll walk through a practical use case and explore different ways to speed up your queries.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="the-use-case">The use case</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Imagine a centralized meteorological system that collects daily weather reports from 100 weather stations.
Each station produces 10,000 reports every day, which are stored in the database and automatically deleted after 30 days.</p>
</div>
<div class="paragraph">
<p>Here&#8217;s what the SQL schema looks like:</p>
</div>
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/postgres-execution-time/schema.svg" alt="DB schema"></span></p>
</div>
<div class="paragraph">
<p>The system depends on two essential SQL queries that require optimal performance:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>Fetching all reports from a specific weather station starting from a given date, sorted by received time in descending order and paginated:</p>
</li>
</ul>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">select</span> <span class="n">wr</span><span class="p">.</span><span class="n">id</span><span class="p">,</span> <span class="n">wr</span><span class="p">.</span><span class="k">data</span><span class="p">,</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span>
<span class="k">from</span> <span class="n">weather_report</span> <span class="n">wr</span> <span class="k">join</span> <span class="n">weather_station</span> <span class="n">ws</span> <span class="k">on</span> <span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span>
<span class="k">where</span> <span class="n">ws</span><span class="p">.</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span> <span class="k">and</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span>
<span class="k">order</span> <span class="k">by</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="k">desc</span>
<span class="k">offset</span> <span class="mi">800</span> <span class="k">limit</span> <span class="mi">100</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="ulist">
<ul>
<li>
<p>Counting all reports from a specific weather station starting from a given date:</p>
</li>
</ul>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">select</span> <span class="k">count</span><span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
<span class="k">from</span> <span class="n">weather_report</span> <span class="n">wr</span> <span class="k">join</span> <span class="n">weather_station</span> <span class="n">ws</span> <span class="k">on</span> <span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span>
<span class="k">where</span> <span class="n">ws</span><span class="p">.</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span> <span class="k">and</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Now, let&#8217;s see how we can make these queries faster!</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="optimization-playground">Optimization playground</h2>
<div class="sectionbody">
<div class="paragraph">
<p>You&#8217;re not just reading another post about PostgreSQL query performance.
This post comes with a repository I created and used to test all the content discussed below: <a href="https://github.com/gwenneg/blog-postgres-execution-time" target="_blank" rel="noopener">gwenneg/blog-postgres-execution-time</a>.
Hopefully, this repository will make it easier for you to experiment with different optimizations, possibly using your own schema and generated data.</p>
</div>
<div class="paragraph">
<p>If you&#8217;re not interested in testing optimizations, feel free to skip this section and jump to the <a href="#query-planner">next one</a>.
Otherwise, I&#8217;ll show you how to use my repository to run your own tests.</p>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>By default, the <a href="https://github.com/gwenneg/blog-postgres-execution-time" target="_blank" rel="noopener">gwenneg/blog-postgres-execution-time</a> repository generates 60 million records during the initialization of a local PostgreSQL database.
Depending on your machine, this process can take several hours.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p><a href="https://docs.docker.com/compose/" target="_blank" rel="noopener">Docker Compose</a> is required to run the tests on your machine.
While PostgreSQL is not required, using an existing installation should work.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Clone the <a href="https://github.com/gwenneg/blog-postgres-execution-time" target="_blank" rel="noopener">gwenneg/blog-postgres-execution-time</a> repository.
Open a terminal in either the <a href="https://github.com/gwenneg/blog-postgres-execution-time/tree/main/single-table" target="_blank" rel="noopener">single-table</a> folder (no partitions) or the <a href="https://github.com/gwenneg/blog-postgres-execution-time/tree/main/partitioned-table" target="_blank" rel="noopener">partitioned-table</a> folder (with partitions) from the repository, depending on which approach you want to test.
Then, start a container with:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">docker compose up <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The execution of this command may take several hours.</td>
</tr>
</table>
</div>
<details>
<summary class="title"><strong>Click here</strong> if you run into a <code>permission denied</code> error on a SELinux-enabled system.</summary>
<div class="content">
<div class="paragraph">
<p>In a SELinux-enabled system (e.g. Fedora, CentOS, RHEL), SELinux policies may prevent the container from accessing the <code>init.sql</code> file:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash"><span class="o">[</span>postgres] | psql: error: /docker-entrypoint-initdb.d/init.sql: Permission denied</code></pre>
</div>
</div>
<div class="paragraph">
<p>If that happens, run the following commands:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash"><span class="nb">chcon</span> <span class="nt">-Rt</span> svirt_sandbox_file_t ./sql <i class="conum" data-value="1"></i><b>(1)</b>
docker compose down <span class="nt">--volumes</span> <i class="conum" data-value="2"></i><b>(2)</b>
docker compose up <i class="conum" data-value="3"></i><b>(3)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>This changes the SELinux security context and grants permission to the container to access all files from the <code>./sql</code> folder.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>The volumes that were created with the previous <code>docker compose up</code> execution need to be removed.
Otherwise, the <code>init.sql</code> script will not be rerun.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>The execution of this command may take several hours.</td>
</tr>
</table>
</div>
</div>
</details>
<div class="paragraph">
<p>The database initialization is complete when the following message appears:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash"><span class="o">[</span>postgres] | 2025-03-21 13:28:21.316 UTC <span class="o">[</span>1] LOG:  database system is ready to accept connections</code></pre>
</div>
</div>
<div class="paragraph">
<p>You can now connect to the database.</p>
</div>
<details>
<summary class="title"><strong>Click here</strong> if PostgreSQL is not installed on your machine.</summary>
<div class="content">
<div class="paragraph">
<p>First, identify the PostgreSQL container ID using <code>docker ps</code>.
Then, enter the container with the following command:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">docker <span class="nb">exec</span> <span class="nt">-it</span> 44086e358596 bash <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td><code>44086e358596</code> is the container ID returned by <code>docker ps</code>.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Now that you&#8217;re in the container, it&#8217;s time to connect to PostgreSQL:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">psql <span class="nt">-h</span> localhost <span class="nt">-U</span> postgres</code></pre>
</div>
</div>
</div>
</details>
<details>
<summary class="title"><strong>Click here</strong> to use <code>psql</code> from an existing PostgreSQL installation.</summary>
<div class="content">
<div class="paragraph">
<p>Run the following command from the current folder:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="bash">psql <span class="nt">-h</span> localhost <span class="nt">-p</span> 15432 <span class="nt">-U</span> postgres <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>When prompted, enter the password: <code>postgres</code>.</td>
</tr>
</table>
</div>
</div>
</details>
<div class="paragraph">
<p>Congrats! You&#8217;re now ready to run the SQL scripts provided in the repository or any other SQL queries:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code>\i sql/explain_analyze.sql <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>If you&#8217;re connected to PostgreSQL from within the container, the path is <code>/mnt/sql/explain_analyze.sql</code>.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>These are the SQL scripts included in the repository:</p>
</div>
<table class="tableblock frame-all grid-all stretch">
<colgroup>
<col style="width: 25%;">
<col style="width: 75%;">
</colgroup>
<thead>
<tr>
<th class="tableblock halign-left valign-top">File name</th>
<th class="tableblock halign-left valign-top">Description</th>
</tr>
</thead>
<tbody>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">create_indexes.sql</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Adds indexes to the <code>weather_report</code> table.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">explain_analyze.sql</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Displays the execution plan of the "fetch" and "count" queries.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">init.sql</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">DO NOT RUN MANUALLY - Creates the database schema and generates data at container startup.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">relations_size.sql</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Displays the disk usage of the <code>weather_report</code> table and all associated indexes.</p></td>
</tr>
<tr>
<td class="tableblock halign-left valign-top"><p class="tableblock">vacuum_analyze.sql</p></td>
<td class="tableblock halign-left valign-top"><p class="tableblock">Performs <code>VACUUM</code> and updates statistics on the <code>weather_report</code> and <code>weather_station</code> tables.</p></td>
</tr>
</tbody>
</table>
</div>
</div>
<div class="sect1">
<h2 id="the-postgresql-query-planner"><a id="query-planner"></a> The PostgreSQL query planner</h2>
<div class="sectionbody">
<div class="paragraph">
<p>When you run a SQL query in PostgreSQL, it isn&#8217;t executed immediately.
First, the <a href="https://www.postgresql.org/docs/current/planner-optimizer.html" target="_blank" rel="noopener">query planner</a> analyzes the query structure, table sizes, indexes, joins, filtering conditions and available statistics to generate multiple execution plans.
Then, PostgreSQL selects the most efficient plan and executes the query.</p>
</div>
<div class="paragraph">
<p>The <a href="https://www.postgresql.org/docs/current/sql-explain.html" target="_blank" rel="noopener">EXPLAIN</a> command displays the execution plan for a given query, providing details on execution time, row counts, indexes usage and more.
That command is crucial for identifying slow queries, missing indexes, inefficient joins or outdated statistics.
We&#8217;ll rely on it heavily throughout this post.</p>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>When testing query optimizations, use <a href="https://www.postgresql.org/docs/current/sql-explain.html" target="_blank" rel="noopener">EXPLAIN</a> before and after making changes.
This will help you determine whether the optimization was effective.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Reading an execution plan used to require highly specialized knowledge before the rise of Large Language Models.
Today, if you submit your execution plan to an LLM, it can help identify weaknesses and suggest fixes.
However, as with any LLM, be cautious of hallucinations and always double-check its recommendations.</p>
</div>
<div class="paragraph">
<p>Besides LLMs, tools like <a href="https://explain.dalibo.com" target="_blank" rel="noopener">explain.dalibo.com</a> can also help you visualize and understand your execution plan:</p>
</div>
<div class="paragraph">
<p><span class="image"><img src="/assets/images/posts/postgres-execution-time/dalibo.png" alt="Visualizing an execution plan with Dalibo"></span></p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="explaining-the-sql-queries-from-the-use-case">Explaining the SQL queries from the use case</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Most of this post is based on the <a href="https://github.com/gwenneg/blog-postgres-execution-time/tree/main/single-table" target="_blank" rel="noopener">single-table</a> folder from the <a href="https://github.com/gwenneg/blog-postgres-execution-time" target="_blank" rel="noopener">gwenneg/blog-postgres-execution-time</a> repository.
The <a href="https://github.com/gwenneg/blog-postgres-execution-time/tree/main/partitioned-table" target="_blank" rel="noopener">partitioned-table</a> folder is only used in the <a href="#partitioning">Partitioning the <code>weather_report</code> table</a> section below.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Let&#8217;s see what the execution plans for our two essential queries look like without indexes (except for primary keys) and using the default PostgreSQL settings.</p>
</div>
<div class="listingblock">
<div class="title">Explaining the "fetch" query</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">explain</span> <span class="k">analyze</span> <i class="conum" data-value="1"></i><b>(1)</b>
<span class="k">select</span> <span class="n">wr</span><span class="p">.</span><span class="n">id</span><span class="p">,</span> <span class="n">wr</span><span class="p">.</span><span class="k">data</span><span class="p">,</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span>
<span class="k">from</span> <span class="n">weather_report</span> <span class="n">wr</span> <span class="k">join</span> <span class="n">weather_station</span> <span class="n">ws</span> <span class="k">on</span> <span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span>
<span class="k">where</span> <span class="n">ws</span><span class="p">.</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span> <span class="k">and</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span>
<span class="k">order</span> <span class="k">by</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="k">desc</span>
<span class="k">offset</span> <span class="mi">800</span> <span class="k">limit</span> <span class="mi">100</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>When the <code>ANALYZE</code> option is used, PostgreSQL provides additional details including the actual execution times.</td>
</tr>
</table>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>When <code>ANALYZE</code> is used, the SQL query is actually executed and modifies the DB data.
If you need to <code>EXPLAIN ANALYZE</code> an <code>INSERT</code> query or any other query that modifies the data, you should wrap the <code>EXPLAIN</code> statement into a transaction and end it with a <code>ROLLBACK</code>.</p>
</div>
</td>
</tr>
</table>
</div>
<details>
<summary class="title"><strong>Click here</strong> to see the execution plan of the "fetch" query.</summary>
<div class="content">
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Limit</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">980048</span><span class="p">.</span><span class="mi">43</span><span class="p">..</span><span class="mi">980060</span><span class="p">.</span><span class="mi">09</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">2063</span><span class="p">.</span><span class="mi">296</span><span class="p">..</span><span class="mi">2067</span><span class="p">.</span><span class="mi">738</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Gather</span> <span class="n">Merge</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">979955</span><span class="p">.</span><span class="mi">09</span><span class="p">..</span><span class="mi">995587</span><span class="p">.</span><span class="mi">64</span> <span class="k">rows</span><span class="o">=</span><span class="mi">133984</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">1984</span><span class="p">.</span><span class="mi">690</span><span class="p">..</span><span class="mi">1989</span><span class="p">.</span><span class="mi">270</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="n">Workers</span> <span class="n">Planned</span><span class="p">:</span> <span class="mi">2</span>
         <span class="n">Workers</span> <span class="n">Launched</span><span class="p">:</span> <span class="mi">2</span> <i class="conum" data-value="1"></i><b>(1)</b>
         <span class="o">-&gt;</span>  <span class="n">Sort</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">978955</span><span class="p">.</span><span class="mi">06</span><span class="p">..</span><span class="mi">979122</span><span class="p">.</span><span class="mi">54</span> <span class="k">rows</span><span class="o">=</span><span class="mi">66992</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">1944</span><span class="p">.</span><span class="mi">160</span><span class="p">..</span><span class="mi">1944</span><span class="p">.</span><span class="mi">194</span> <span class="k">rows</span><span class="o">=</span><span class="mi">687</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
               <span class="n">Sort</span> <span class="k">Key</span><span class="p">:</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="k">DESC</span>
               <span class="n">Sort</span> <span class="k">Method</span><span class="p">:</span> <span class="n">top</span><span class="o">-</span><span class="n">N</span> <span class="n">heapsort</span>  <span class="n">Memory</span><span class="p">:</span> <span class="mi">288</span><span class="n">kB</span> <i class="conum" data-value="2"></i><b>(2)</b>
               <span class="n">Worker</span> <span class="mi">0</span><span class="p">:</span>  <span class="n">Sort</span> <span class="k">Method</span><span class="p">:</span> <span class="n">top</span><span class="o">-</span><span class="n">N</span> <span class="n">heapsort</span>  <span class="n">Memory</span><span class="p">:</span> <span class="mi">288</span><span class="n">kB</span>
               <span class="n">Worker</span> <span class="mi">1</span><span class="p">:</span>  <span class="n">Sort</span> <span class="k">Method</span><span class="p">:</span> <span class="n">top</span><span class="o">-</span><span class="n">N</span> <span class="n">heapsort</span>  <span class="n">Memory</span><span class="p">:</span> <span class="mi">288</span><span class="n">kB</span>
               <span class="o">-&gt;</span>  <span class="n">Hash</span> <span class="k">Join</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">2</span><span class="p">.</span><span class="mi">26</span><span class="p">..</span><span class="mi">975332</span><span class="p">.</span><span class="mi">88</span> <span class="k">rows</span><span class="o">=</span><span class="mi">66992</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">873</span><span class="p">.</span><span class="mi">837</span><span class="p">..</span><span class="mi">1927</span><span class="p">.</span><span class="mi">942</span> <span class="k">rows</span><span class="o">=</span><span class="mi">53333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                     <span class="n">Hash</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
                     <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">957000</span><span class="p">.</span><span class="mi">00</span> <span class="k">rows</span><span class="o">=</span><span class="mi">6699173</span> <span class="n">width</span><span class="o">=</span><span class="mi">73</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">873</span><span class="p">.</span><span class="mi">701</span><span class="p">..</span><span class="mi">1494</span><span class="p">.</span><span class="mi">414</span> <span class="k">rows</span><span class="o">=</span><span class="mi">5333333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span> <i class="conum" data-value="3"></i><b>(3)</b>
                           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">)</span>
                           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">4666667</span>
                     <span class="o">-&gt;</span>  <span class="n">Hash</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">054</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">054</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                           <span class="n">Buckets</span><span class="p">:</span> <span class="mi">1024</span>  <span class="n">Batches</span><span class="p">:</span> <span class="mi">1</span>  <span class="n">Memory</span> <span class="k">Usage</span><span class="p">:</span> <span class="mi">9</span><span class="n">kB</span>
                           <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">040</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">045</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                                 <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
                                 <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">200</span> <span class="n">ms</span>
 <span class="n">JIT</span><span class="p">:</span>
   <span class="n">Functions</span><span class="p">:</span> <span class="mi">44</span>
   <span class="k">Options</span><span class="p">:</span> <span class="n">Inlining</span> <span class="k">true</span><span class="p">,</span> <span class="n">Optimization</span> <span class="k">true</span><span class="p">,</span> <span class="n">Expressions</span> <span class="k">true</span><span class="p">,</span> <span class="n">Deforming</span> <span class="k">true</span>
   <span class="n">Timing</span><span class="p">:</span> <span class="n">Generation</span> <span class="mi">1</span><span class="p">.</span><span class="mi">955</span> <span class="n">ms</span> <span class="p">(</span><span class="n">Deform</span> <span class="mi">0</span><span class="p">.</span><span class="mi">951</span> <span class="n">ms</span><span class="p">),</span> <span class="n">Inlining</span> <span class="mi">212</span><span class="p">.</span><span class="mi">662</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Optimization</span> <span class="mi">142</span><span class="p">.</span><span class="mi">882</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Emission</span> <span class="mi">131</span><span class="p">.</span><span class="mi">128</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Total</span> <span class="mi">488</span><span class="p">.</span><span class="mi">627</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">2068</span><span class="p">.</span><span class="mi">703</span> <span class="n">ms</span> <i class="conum" data-value="4"></i><b>(4)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The number of workers varies depending on the available CPU cores and the PostgreSQL configuration.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Sorting all matching rows using <code>top-N heapsort</code> is expensive.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>A <a href="https://www.postgresql.org/docs/current/parallel-plans.html#PARALLEL-SCANS" target="_blank" rel="noopener">parallel sequential scan</a> on 30 million rows is a major bottleneck.</td>
</tr>
<tr>
<td><i class="conum" data-value="4"></i><b>4</b></td>
<td>This is the execution time of the query.</td>
</tr>
</table>
</div>
</div>
</details>
<div class="listingblock">
<div class="title">Explaining the "count" query</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">explain</span> <span class="k">analyze</span>
<span class="k">select</span> <span class="k">count</span><span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
<span class="k">from</span> <span class="n">weather_report</span> <span class="n">wr</span> <span class="k">join</span> <span class="n">weather_station</span> <span class="n">ws</span> <span class="k">on</span> <span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span>
<span class="k">where</span> <span class="n">ws</span><span class="p">.</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span> <span class="k">and</span> <span class="n">wr</span><span class="p">.</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span><span class="p">;</span></code></pre>
</div>
</div>
<details>
<summary class="title"><strong>Click here</strong> to see the execution plan of the "count" query.</summary>
<div class="content">
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="n">Finalize</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">976500</span><span class="p">.</span><span class="mi">57</span><span class="p">..</span><span class="mi">976500</span><span class="p">.</span><span class="mi">58</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">2029</span><span class="p">.</span><span class="mi">976</span><span class="p">..</span><span class="mi">2034</span><span class="p">.</span><span class="mi">088</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Gather</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">976500</span><span class="p">.</span><span class="mi">36</span><span class="p">..</span><span class="mi">976500</span><span class="p">.</span><span class="mi">57</span> <span class="k">rows</span><span class="o">=</span><span class="mi">2</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">2029</span><span class="p">.</span><span class="mi">833</span><span class="p">..</span><span class="mi">2034</span><span class="p">.</span><span class="mi">071</span> <span class="k">rows</span><span class="o">=</span><span class="mi">3</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="n">Workers</span> <span class="n">Planned</span><span class="p">:</span> <span class="mi">2</span>
         <span class="n">Workers</span> <span class="n">Launched</span><span class="p">:</span> <span class="mi">2</span> <i class="conum" data-value="1"></i><b>(1)</b>
         <span class="o">-&gt;</span>  <span class="k">Partial</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">975500</span><span class="p">.</span><span class="mi">36</span><span class="p">..</span><span class="mi">975500</span><span class="p">.</span><span class="mi">37</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">2013</span><span class="p">.</span><span class="mi">942</span><span class="p">..</span><span class="mi">2013</span><span class="p">.</span><span class="mi">943</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
               <span class="o">-&gt;</span>  <span class="n">Hash</span> <span class="k">Join</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">2</span><span class="p">.</span><span class="mi">26</span><span class="p">..</span><span class="mi">975332</span><span class="p">.</span><span class="mi">88</span> <span class="k">rows</span><span class="o">=</span><span class="mi">66992</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">888</span><span class="p">.</span><span class="mi">852</span><span class="p">..</span><span class="mi">2011</span><span class="p">.</span><span class="mi">411</span> <span class="k">rows</span><span class="o">=</span><span class="mi">53333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                     <span class="n">Hash</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
                     <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">957000</span><span class="p">.</span><span class="mi">00</span> <span class="k">rows</span><span class="o">=</span><span class="mi">6699173</span> <span class="n">width</span><span class="o">=</span><span class="mi">32</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">888</span><span class="p">.</span><span class="mi">705</span><span class="p">..</span><span class="mi">1508</span><span class="p">.</span><span class="mi">554</span> <span class="k">rows</span><span class="o">=</span><span class="mi">5333333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span> <i class="conum" data-value="2"></i><b>(2)</b>
                           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">)</span>
                           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">4666667</span>
                     <span class="o">-&gt;</span>  <span class="n">Hash</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">042</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">043</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                           <span class="n">Buckets</span><span class="p">:</span> <span class="mi">1024</span>  <span class="n">Batches</span><span class="p">:</span> <span class="mi">1</span>  <span class="n">Memory</span> <span class="k">Usage</span><span class="p">:</span> <span class="mi">9</span><span class="n">kB</span>
                           <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">033</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">037</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                                 <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
                                 <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">141</span> <span class="n">ms</span>
 <span class="n">JIT</span><span class="p">:</span>
   <span class="n">Functions</span><span class="p">:</span> <span class="mi">50</span>
   <span class="k">Options</span><span class="p">:</span> <span class="n">Inlining</span> <span class="k">true</span><span class="p">,</span> <span class="n">Optimization</span> <span class="k">true</span><span class="p">,</span> <span class="n">Expressions</span> <span class="k">true</span><span class="p">,</span> <span class="n">Deforming</span> <span class="k">true</span>
   <span class="n">Timing</span><span class="p">:</span> <span class="n">Generation</span> <span class="mi">1</span><span class="p">.</span><span class="mi">781</span> <span class="n">ms</span> <span class="p">(</span><span class="n">Deform</span> <span class="mi">0</span><span class="p">.</span><span class="mi">765</span> <span class="n">ms</span><span class="p">),</span> <span class="n">Inlining</span> <span class="mi">211</span><span class="p">.</span><span class="mi">423</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Optimization</span> <span class="mi">142</span><span class="p">.</span><span class="mi">079</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Emission</span> <span class="mi">162</span><span class="p">.</span><span class="mi">995</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Total</span> <span class="mi">518</span><span class="p">.</span><span class="mi">278</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">2034</span><span class="p">.</span><span class="mi">732</span> <span class="n">ms</span> <i class="conum" data-value="3"></i><b>(3)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The number of workers varies depending on the available CPU cores and the PostgreSQL configuration.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>A <a href="https://www.postgresql.org/docs/current/parallel-plans.html#PARALLEL-SCANS" target="_blank" rel="noopener">parallel sequential scan</a> on 30 million rows is a major bottleneck.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>This is the execution time of the query.</td>
</tr>
</table>
</div>
</div>
</details>
<div class="paragraph">
<p>More than 2 seconds to run each query - that doesn&#8217;t look good, right?
But it&#8217;s no surprise since the <code>weather_report</code> table contains 30 million records and we&#8217;re filtering on unindexed columns.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="indexing-the-weather_report-table">Indexing the <code>weather_report</code> table</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Our queries both include a condition on the <code>received_at</code> and <code>weather_station_id</code> columns from the <code>weather_report</code> table, which contains 30 million records.
Indexing these columns should help speed up the queries.</p>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>If you create a composite <a href="https://www.postgresql.org/docs/current/indexes-types.html#INDEXES-TYPES-BTREE" target="_blank" rel="noopener">B-Tree index</a> (the default index type in PostgreSQL) with multiple columns, their order matters and can impact query performance.
The best column order depends on how your query filters, sorts or joins data.
So how do you figure out which order works best?
A good rule of thumb is to put the column that filters out the most rows — in other words, the one with the highest cardinality — first.
In a local environment, you can also take a trial-and-error approach by creating different index orders and using <code>EXPLAIN ANALYZE</code> to see which one the query planner prefers.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="sect2">
<h3 id="introducing-non-covering-b-tree-indexes">Introducing non-covering B-Tree indexes</h3>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>A non-covering index is an index that does not include all the columns needed to satisfy a query.
As a result, PostgreSQL must perform extra lookups in the table (heap) to retrieve missing column values.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Let&#8217;s add the following indexes and see how they impact the execution plans.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_btree_received_at_weather_station_id_non_covering</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">btree</span> <span class="p">(</span><span class="n">received_at</span> <span class="k">desc</span><span class="p">,</span> <span class="n">weather_station_id</span><span class="p">);</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td><code>using btree</code> can be omitted because that&#8217;s the default index type in PostgreSQL.</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_btree_weather_station_id_received_at_non_covering</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">btree</span> <span class="p">(</span><span class="n">weather_station_id</span><span class="p">,</span> <span class="n">received_at</span> <span class="k">desc</span><span class="p">);</span></code></pre>
</div>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>If a column is mostly queried in descending order, indexing it with <code>DESC</code> helps avoid reverse index scans and reduces sorting overhead, effectively improving query performance.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "fetch" query with a non-covering index</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Limit</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">69479</span><span class="p">.</span><span class="mi">90</span><span class="p">..</span><span class="mi">78164</span><span class="p">.</span><span class="mi">82</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">67</span><span class="p">.</span><span class="mi">339</span><span class="p">..</span><span class="mi">70</span><span class="p">.</span><span class="mi">740</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Nested</span> <span class="n">Loop</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">13831166</span><span class="p">.</span><span class="mi">26</span> <span class="k">rows</span><span class="o">=</span><span class="mi">159255</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">1</span><span class="p">.</span><span class="mi">021</span><span class="p">..</span><span class="mi">70</span><span class="p">.</span><span class="mi">693</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="k">Join</span> <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
         <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="k">Join</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">89092</span>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_received_at_weather_station_id_non_covering</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">13592281</span><span class="p">.</span><span class="mi">74</span> <span class="k">rows</span><span class="o">=</span><span class="mi">15925485</span> <span class="n">width</span><span class="o">=</span><span class="mi">73</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">545</span><span class="p">..</span><span class="mi">51</span><span class="p">.</span><span class="mi">906</span> <span class="k">rows</span><span class="o">=</span><span class="mi">89992</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="1"></i><b>(1)</b>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">)</span>
         <span class="o">-&gt;</span>  <span class="n">Materialize</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">000</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">000</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">89992</span><span class="p">)</span>
               <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">026</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">044</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
                     <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
                     <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">10</span><span class="p">.</span><span class="mi">100</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">70</span><span class="p">.</span><span class="mi">824</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The previous parallel sequential scan was replaced with an <a href="https://www.postgresql.org/docs/current/index-scanning.html" target="_blank" rel="noopener">index scan</a> which is much faster.</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "count" query with a non-covering index</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">587672</span><span class="p">.</span><span class="mi">27</span><span class="p">..</span><span class="mi">587672</span><span class="p">.</span><span class="mi">28</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">452</span><span class="p">.</span><span class="mi">095</span><span class="p">..</span><span class="mi">452</span><span class="p">.</span><span class="mi">096</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Nested</span> <span class="n">Loop</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">587274</span><span class="p">.</span><span class="mi">13</span> <span class="k">rows</span><span class="o">=</span><span class="mi">159255</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">41</span><span class="p">.</span><span class="mi">065</span><span class="p">..</span><span class="mi">441</span><span class="p">.</span><span class="mi">346</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">41</span><span class="p">.</span><span class="mi">031</span><span class="p">..</span><span class="mi">41</span><span class="p">.</span><span class="mi">039</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
               <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
               <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_weather_station_id_received_at_non_covering</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">585679</span><span class="p">.</span><span class="mi">33</span> <span class="k">rows</span><span class="o">=</span><span class="mi">159255</span> <span class="n">width</span><span class="o">=</span><span class="mi">32</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">023</span><span class="p">..</span><span class="mi">384</span><span class="p">.</span><span class="mi">034</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="1"></i><b>(1)</b>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">141</span> <span class="n">ms</span>
 <span class="n">JIT</span><span class="p">:</span>
   <span class="n">Functions</span><span class="p">:</span> <span class="mi">9</span>
   <span class="k">Options</span><span class="p">:</span> <span class="n">Inlining</span> <span class="k">true</span><span class="p">,</span> <span class="n">Optimization</span> <span class="k">true</span><span class="p">,</span> <span class="n">Expressions</span> <span class="k">true</span><span class="p">,</span> <span class="n">Deforming</span> <span class="k">true</span>
   <span class="n">Timing</span><span class="p">:</span> <span class="n">Generation</span> <span class="mi">0</span><span class="p">.</span><span class="mi">615</span> <span class="n">ms</span> <span class="p">(</span><span class="n">Deform</span> <span class="mi">0</span><span class="p">.</span><span class="mi">204</span> <span class="n">ms</span><span class="p">),</span> <span class="n">Inlining</span> <span class="mi">13</span><span class="p">.</span><span class="mi">385</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Optimization</span> <span class="mi">16</span><span class="p">.</span><span class="mi">098</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Emission</span> <span class="mi">11</span><span class="p">.</span><span class="mi">561</span> <span class="n">ms</span><span class="p">,</span> <span class="n">Total</span> <span class="mi">41</span><span class="p">.</span><span class="mi">658</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">452</span><span class="p">.</span><span class="mi">780</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The previous parallel sequential scan was replaced with an <a href="https://www.postgresql.org/docs/current/index-scanning.html" target="_blank" rel="noopener">index scan</a>, which is faster but still not fast enough because PostgreSQL must fetch additional columns from the table.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Execution times have dropped from 2069 ms to 71 ms for the "fetch" query and from 2035 ms to 453 ms for the "count" query.
Much better, but there&#8217;s still room for improvement!</p>
</div>
</div>
<div class="sect2">
<h3 id="introducing-covering-b-tree-indexes">Introducing covering B-Tree indexes</h3>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>A <a href="https://www.postgresql.org/docs/current/indexes-index-only-scans.html" target="_blank" rel="noopener">covering index</a> is an index that includes all the columns needed for a query, allowing PostgreSQL to retrieve data entirely from the index without accessing the main table (heap fetch).
This improves performance by reducing disk I/O, but comes at the cost of increased storage usage.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Let&#8217;s replace our previous non-covering indexes with covering indexes for better performance.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_btree_received_at_weather_station_id_covering</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">btree</span> <span class="p">(</span><span class="n">received_at</span> <span class="k">desc</span><span class="p">,</span> <span class="n">weather_station_id</span><span class="p">)</span> <span class="n">include</span> <span class="p">(</span><span class="n">id</span><span class="p">,</span> <span class="k">data</span><span class="p">);</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The <code>INCLUDE</code> clause for covering indexes was introduced in PostgreSQL 11.
If you&#8217;re using an older version, you&#8217;ll need to add the <code>id</code> and <code>data</code> columns at the end of the index definition instead.</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_btree_weather_station_id_received_at_covering</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">btree</span> <span class="p">(</span><span class="n">weather_station_id</span><span class="p">,</span> <span class="n">received_at</span> <span class="k">desc</span><span class="p">)</span> <span class="n">include</span> <span class="p">(</span><span class="n">id</span><span class="p">,</span> <span class="k">data</span><span class="p">);</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Does that make our queries run faster?</p>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "fetch" query with a covering index</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Limit</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">6641</span><span class="p">.</span><span class="mi">57</span><span class="p">..</span><span class="mi">7471</span><span class="p">.</span><span class="mi">70</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">27</span><span class="p">.</span><span class="mi">223</span><span class="p">..</span><span class="mi">29</span><span class="p">.</span><span class="mi">976</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Nested</span> <span class="n">Loop</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">1336188</span><span class="p">.</span><span class="mi">27</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160962</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">156</span><span class="p">..</span><span class="mi">29</span><span class="p">.</span><span class="mi">946</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="k">Join</span> <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">wr</span><span class="p">.</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span>
         <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="k">Join</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">89092</span> <i class="conum" data-value="1"></i><b>(1)</b>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_received_at_weather_station_id_covering</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">1094743</span><span class="p">.</span><span class="mi">50</span> <span class="k">rows</span><span class="o">=</span><span class="mi">16096168</span> <span class="n">width</span><span class="o">=</span><span class="mi">73</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">030</span><span class="p">..</span><span class="mi">11</span><span class="p">.</span><span class="mi">414</span> <span class="k">rows</span><span class="o">=</span><span class="mi">89992</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="2"></i><b>(2)</b>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">)</span>
               <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
         <span class="o">-&gt;</span>  <span class="n">Materialize</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">000</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">000</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">89992</span><span class="p">)</span>
               <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">018</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">035</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
                     <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
                     <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">472</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">30</span><span class="p">.</span><span class="mi">018</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Filtering out 89,092 rows after the join is inefficient.
We&#8217;ll need to fix that later.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>The previous index scan was replaced with an <a href="https://www.postgresql.org/docs/current/indexes-index-only-scans.html" target="_blank" rel="noopener">index-only scan</a> which is significantly faster.</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "count" query with a covering index</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">13390</span><span class="p">.</span><span class="mi">08</span><span class="p">..</span><span class="mi">13390</span><span class="p">.</span><span class="mi">09</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">31</span><span class="p">.</span><span class="mi">861</span><span class="p">..</span><span class="mi">31</span><span class="p">.</span><span class="mi">862</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="o">-&gt;</span>  <span class="n">Nested</span> <span class="n">Loop</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">12987</span><span class="p">.</span><span class="mi">67</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160962</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">018</span><span class="p">..</span><span class="mi">26</span><span class="p">.</span><span class="mi">090</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span> <span class="n">ws</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">005</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">016</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
               <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
               <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_weather_station_id_received_at_covering</span> <span class="k">on</span> <span class="n">weather_report</span> <span class="n">wr</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">11375</span><span class="p">.</span><span class="mi">80</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160962</span> <span class="n">width</span><span class="o">=</span><span class="mi">32</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">012</span><span class="p">..</span><span class="mi">17</span><span class="p">.</span><span class="mi">698</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="1"></i><b>(1)</b>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">id</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
               <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">139</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">31</span><span class="p">.</span><span class="mi">886</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The previous index scan was replaced with an <a href="https://www.postgresql.org/docs/current/indexes-index-only-scans.html" target="_blank" rel="noopener">index-only scan</a> which is much faster.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Compared to non-covering indexes, execution times have dropped from 71 ms to 30 ms for the "fetch" query and from 453 ms to 32 ms for the "count" query.
That&#8217;s awesome, but we&#8217;re not done optimizing these queries yet!</p>
</div>
</div>
<div class="sect2">
<h3 id="introducing-a-brin-index">Introducing a BRIN index</h3>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>A <a href="https://www.postgresql.org/docs/current/brin.html" target="_blank" rel="noopener">BRIN index</a> is a lightweight index that stores summary metadata (min and max values) for block ranges instead of indexing every row.
It is ideal for large, append-only tables with naturally ordered data, such as time-series or logs, offering fast lookups with minimal storage overhead.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>That sounds like a great index for the <code>received_at</code> column.
Here&#8217;s how to create it:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_brin_received_at</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">brin</span> <span class="p">(</span><span class="n">received_at</span><span class="p">);</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Unfortunately, that index doesn&#8217;t help reduce the execution time of our queries.
A BRIN index is only effective when data is physically sorted, but since <code>weather_report</code> records are deleted after 30 days, they are not stored in natural order.
If the records were not removed, a BRIN index could have been a great way to improve query performance.</p>
</div>
<div class="paragraph">
<p>PostgreSQL provides a command that physically reorders a table based on an index: <a href="https://www.postgresql.org/docs/current/sql-cluster.html" target="_blank" rel="noopener">CLUSTER</a>.
However, BRIN indexes do not support clustering.</p>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="indexes-come-at-a-cost">Indexes come at a cost</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Run this query to check how much disk space your indexes are using:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">select</span> <span class="n">indexname</span><span class="p">,</span> <span class="n">pg_size_pretty</span><span class="p">(</span><span class="n">pg_relation_size</span><span class="p">(</span><span class="n">indexname</span><span class="p">::</span><span class="n">regclass</span><span class="p">))</span>
<span class="k">from</span> <span class="n">pg_indexes</span>
<span class="k">where</span> <span class="n">tablename</span> <span class="o">=</span> <span class="s1">'weather_report'</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Covering B-Tree indexes can be quite expensive and sometimes use nearly as much disk space as the table itself.
On the other hand, BRIN indexes use a very small amount of disk space.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql">                      <span class="n">indexname</span>                       <span class="o">|</span> <span class="n">pg_size_pretty</span>
<span class="c1">------------------------------------------------------+----------------</span>
 <span class="n">pk_weather_report</span>                                    <span class="o">|</span> <span class="mi">2337</span> <span class="n">MB</span>
 <span class="n">ix_btree_received_at_weather_station_id_non_covering</span> <span class="o">|</span> <span class="mi">1159</span> <span class="n">MB</span>
 <span class="n">ix_btree_weather_station_id_received_at_non_covering</span> <span class="o">|</span> <span class="mi">1162</span> <span class="n">MB</span>
 <span class="n">ix_btree_received_at_weather_station_id_covering</span>     <span class="o">|</span> <span class="mi">2977</span> <span class="n">MB</span>
 <span class="n">ix_btree_weather_station_id_received_at_covering</span>     <span class="o">|</span> <span class="mi">2986</span> <span class="n">MB</span>
 <span class="n">ix_brin_received_at</span>                                  <span class="o">|</span> <span class="mi">176</span> <span class="n">kB</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>Indexes also slow down <code>INSERT</code>, <code>UPDATE</code> and <code>DELETE</code> queries.
Every time a row is modified, PostgreSQL must update the corresponding index entries.
This overhead on write operations is especially noticeable with high insert-rate workloads.</p>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>You can check the impact of indexes on write performance by analyzing execution plans or running <a href="https://www.postgresql.org/docs/current/pgbench.html" target="_blank" rel="noopener">benchmark tests</a> on your database.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="title">Explaining an insert query</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">explain</span> <span class="k">analyze</span>
<span class="k">insert</span> <span class="k">into</span> <span class="n">weather_report</span> <span class="p">(</span><span class="k">data</span><span class="p">,</span> <span class="n">received_at</span><span class="p">,</span> <span class="n">weather_station_id</span><span class="p">)</span>
<span class="k">values</span> <span class="p">(</span><span class="s1">'Sunny day'</span><span class="p">,</span> <span class="n">now</span><span class="p">(),</span> <span class="s1">'be9a5a83-f789-41dd-8023-cd3df445f055'</span><span class="p">);</span></code></pre>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="writing-smarter-queries">Writing smarter queries</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Indexes can really boost performance, but they can&#8217;t automagically fix a poorly written query.</p>
</div>
<div class="paragraph">
<p>In the current "fetch" query, PostgreSQL retrieves 89,992 rows and then filters out 89,092 of them.
That doesn&#8217;t look right.
Let&#8217;s see what happens if we replace the join with a subquery:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">explain</span> <span class="k">analyze</span>
<span class="k">select</span> <span class="n">id</span><span class="p">,</span> <span class="k">data</span><span class="p">,</span> <span class="n">received_at</span>
<span class="k">from</span> <span class="n">weather_report</span>
<span class="k">where</span> <span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span>
<span class="k">and</span> <span class="n">weather_station_id</span> <span class="o">=</span>
<span class="p">(</span><span class="k">select</span> <span class="n">id</span> <span class="k">from</span> <span class="n">weather_station</span> <span class="k">where</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">)</span>
<span class="k">order</span> <span class="k">by</span> <span class="n">received_at</span> <span class="k">desc</span>
<span class="k">offset</span> <span class="mi">800</span> <span class="k">limit</span> <span class="mi">100</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "fetch" query with subquery</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Limit</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">59</span><span class="p">.</span><span class="mi">35</span><span class="p">..</span><span class="mi">66</span><span class="p">.</span><span class="mi">42</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">146</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">162</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="n">InitPlan</span> <span class="mi">1</span>
     <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">008</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">014</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
   <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_weather_station_id_received_at_covering</span> <span class="k">on</span> <span class="n">weather_report</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">11375</span><span class="p">.</span><span class="mi">80</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160962</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">029</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">139</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="1"></i><b>(1)</b>
         <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
         <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">095</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">177</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The query planner is now using a different index.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Wow, that&#8217;s an incredible improvement!
The query that originally took 2069 ms without an index now runs in under 1 ms.
How is that even possible?</p>
</div>
<div class="paragraph">
<p>The subquery helped move filtering <em>before</em> scanning.
Because of that, PostgreSQL no longer has to fetch 89,992 rows and perform a materialized lookup for each one.
That was a lot of unnecessary work.
It&#8217;s gone now.</p>
</div>
<div class="paragraph">
<p>What about the "count" query?
Could a subquery help reduce its execution time as well?</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">explain</span> <span class="k">analyze</span>
<span class="k">select</span> <span class="k">count</span><span class="p">(</span><span class="o">*</span><span class="p">)</span>
<span class="k">from</span> <span class="n">weather_report</span>
<span class="k">where</span> <span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06'</span>
<span class="k">and</span> <span class="n">weather_station_id</span> <span class="o">=</span>
<span class="p">(</span><span class="k">select</span> <span class="n">id</span> <span class="k">from</span> <span class="n">weather_station</span> <span class="k">where</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">);</span></code></pre>
</div>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "count" query with a subquery</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="n">Finalize</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">11606</span><span class="p">.</span><span class="mi">99</span><span class="p">..</span><span class="mi">11607</span><span class="p">.</span><span class="mi">00</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">19</span><span class="p">.</span><span class="mi">492</span><span class="p">..</span><span class="mi">22</span><span class="p">.</span><span class="mi">322</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="n">InitPlan</span> <span class="mi">1</span>
     <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">007</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">013</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
   <span class="o">-&gt;</span>  <span class="n">Gather</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">11604</span><span class="p">.</span><span class="mi">53</span><span class="p">..</span><span class="mi">11604</span><span class="p">.</span><span class="mi">74</span> <span class="k">rows</span><span class="o">=</span><span class="mi">2</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">19</span><span class="p">.</span><span class="mi">455</span><span class="p">..</span><span class="mi">22</span><span class="p">.</span><span class="mi">317</span> <span class="k">rows</span><span class="o">=</span><span class="mi">3</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="n">Workers</span> <span class="n">Planned</span><span class="p">:</span> <span class="mi">2</span>
         <span class="n">Workers</span> <span class="n">Launched</span><span class="p">:</span> <span class="mi">2</span>
         <span class="o">-&gt;</span>  <span class="k">Partial</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">10604</span><span class="p">.</span><span class="mi">53</span><span class="p">..</span><span class="mi">10604</span><span class="p">.</span><span class="mi">54</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">8</span><span class="p">.</span><span class="mi">007</span><span class="p">..</span><span class="mi">8</span><span class="p">.</span><span class="mi">007</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
               <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">ix_btree_weather_station_id_received_at_covering</span> <span class="k">on</span> <span class="n">weather_report</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">10436</span><span class="p">.</span><span class="mi">86</span> <span class="k">rows</span><span class="o">=</span><span class="mi">67068</span> <span class="n">width</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">038</span><span class="p">..</span><span class="mi">6</span><span class="p">.</span><span class="mi">107</span> <span class="k">rows</span><span class="o">=</span><span class="mi">53333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                     <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
                     <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">093</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">22</span><span class="p">.</span><span class="mi">346</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>It&#8217;s not as impressive as the "fetch" query, but the subquery still significantly improves performance by allowing parallel scans and aggregation.</p>
</div>
</div>
</div>
<div class="sect1">
<h2 id="keep-your-visibility-map-clean">Keep your visibility map clean</h2>
<div class="sectionbody">
<div class="paragraph">
<p>Covering B-Tree indexes can greatly improve query performance, but they have a weakness you should be aware of: heap fetches.
A covering index allows a query to retrieve data entirely from the index without accessing the main table (heap), which would otherwise be expensive.
However, this only works efficiently if the <a href="https://www.postgresql.org/docs/current/storage-vm.html" target="_blank" rel="noopener">visibility map</a> marks all necessary heap pages as "all-visible".
If tuples are updated or deleted from a page and vacuum has not run, that page gets marked as "dirty" in the visibility map and PostgreSQL is forced to fetch rows from the heap, slowing down the query.</p>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p><a href="https://www.postgresql.org/docs/current/sql-vacuum.html" target="_blank" rel="noopener">VACUUM</a> removes dead tuples left behind by <code>UPDATE</code> and <code>DELETE</code> operations while updating the visibility map to minimize unnecessary heap fetches.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="sect2">
<h3 id="when-should-a-table-be-vacuumed">When should a table be vacuumed?</h3>
<div class="paragraph">
<p>A good indicator is the execution plan: if you see heap fetches there, it means the visibility map isn’t up to date.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="p">[...]</span>
<span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="p">[...]</span>
      <span class="p">[...]</span>
      <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">87</span> <i class="conum" data-value="1"></i><b>(1)</b>
<span class="p">[...]</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>PostgreSQL retrieved 87 rows from the heap, which suggests the table may need vacuuming.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>You can also check the number of dead tuples by querying the <a href="https://www.postgresql.org/docs/current/monitoring-stats.html#MONITORING-PG-STAT-ALL-TABLES-VIEW" target="_blank" rel="noopener">pg_stat_user_tables</a> view:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">select</span> <span class="n">relname</span><span class="p">,</span> <span class="n">n_live_tup</span><span class="p">,</span> <span class="n">n_dead_tup</span><span class="p">,</span> <span class="n">last_autovacuum</span>
<span class="k">from</span> <span class="n">pg_stat_user_tables</span>
<span class="k">order</span> <span class="k">by</span> <span class="n">n_dead_tup</span> <span class="k">desc</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>If <code>n_dead_tup</code> is high relative to <code>n_live_tup</code>, the table likely needs vacuuming.</p>
</div>
</div>
<div class="sect2">
<h3 id="how-can-a-table-be-vacuumed">How can a table be vacuumed?</h3>
<div class="paragraph">
<p>PostgreSQL <a href="https://www.postgresql.org/docs/current/runtime-config-autovacuum.html" target="_blank" rel="noopener">vacuums automatically</a> based on the number of dead tuples in a table.
By default, autovacuum is triggered when the number of dead tuples exceeds 50 + 20% of the total number of tuples in the table.
However, the default autovacuum settings are often not aggressive enough when data is removed daily, as in our use case.</p>
</div>
<div class="paragraph">
<p>Autovacuum settings can be tuned for a specific table:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">alter</span> <span class="k">table</span> <span class="n">weather_report</span>
<span class="k">set</span> <span class="p">(</span>
    <span class="n">autovacuum_vacuum_threshold</span> <span class="o">=</span> <span class="mi">0</span><span class="p">,</span> <i class="conum" data-value="1"></i><b>(1)</b>
    <span class="n">autovacuum_vacuum_scale_factor</span> <span class="o">=</span> <span class="mi">0</span><span class="p">.</span><span class="mi">02</span> <i class="conum" data-value="2"></i><b>(2)</b>
<span class="p">);</span> <i class="conum" data-value="3"></i><b>(3)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Minimum number of updated or deleted tuples needed to trigger an autovacuum. Defaults to <code>50</code>.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>Fraction of the table size to add to <code>autovacuum_vacuum_threshold</code> when deciding whether to trigger an autovacuum. Defaults to <code>0.2</code>.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>PostgreSQL will trigger an autovacuum when 2% of the table tuples are dead, instead of the default 50 + 20%.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>If your data is removed in a single batch as part of a daily maintenance task, a better approach is to run a manual vacuum afterward:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">vacuum</span> <span class="k">analyze</span> <span class="n">weather_report</span><span class="p">;</span></code></pre>
</div>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p><a href="https://www.postgresql.org/docs/current/sql-analyze.html" target="_blank" rel="noopener">ANALYZE</a> updates statistics that help the query planner choose the most efficient execution plan.
Running it alongside vacuum is usually a good practice.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>All execution plans in this post were generated after running a manual <code>VACUUM ANALYZE</code>.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="partitioning-the-weather_report-table"><a id="partitioning"></a> Partitioning the <code>weather_report</code> table</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p><a href="https://www.postgresql.org/docs/current/ddl-partitioning.html" target="_blank" rel="noopener">Partitioning</a> a table speeds up queries by allowing PostgreSQL to scan only the relevant partition instead of the entire table.
When each partition is indexed, the indexes are smaller and more focused, making lookups faster and more efficient.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="sect2">
<h3 id="schema-changes-required-for-partitioning">Schema changes required for partitioning</h3>
<div class="paragraph">
<p>Partitioning the <code>weather_report</code> table requires a few changes to the table schema:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">table</span> <span class="n">weather_report</span> <span class="p">(</span>
    <span class="n">id</span> <span class="n">uuid</span> <span class="k">not</span> <span class="k">null</span> <span class="k">default</span> <span class="n">gen_random_uuid</span><span class="p">(),</span>
    <span class="k">data</span> <span class="nb">text</span> <span class="k">not</span> <span class="k">null</span><span class="p">,</span>
    <span class="n">received_at</span> <span class="nb">timestamp</span> <span class="k">not</span> <span class="k">null</span><span class="p">,</span>
    <span class="n">weather_station_id</span> <span class="n">uuid</span> <span class="k">not</span> <span class="k">null</span><span class="p">,</span>
    <span class="k">constraint</span> <span class="n">fk_weather_report_weather_station</span> <span class="k">foreign</span> <span class="k">key</span> <span class="p">(</span><span class="n">weather_station_id</span><span class="p">)</span> <span class="k">references</span> <span class="n">weather_station</span> <span class="p">(</span><span class="n">id</span><span class="p">)</span>
<span class="p">)</span> <span class="k">partition</span> <span class="k">by</span> <span class="k">range</span> <span class="p">(</span><span class="n">received_at</span><span class="p">);</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Each partition will contain a distinct and continuous range of <code>received_at</code> values.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Until now, the <code>id</code> column was the primary key of the <code>weather_report</code> table.
That won&#8217;t work with partitions, as the primary key defined on the parent table <em>must</em> include the partition key (<code>received_at</code>).
It&#8217;s still possible to define a primary key on <code>id</code> within each child partition, but this doesn&#8217;t guarantee uniqueness across all partitions.
This limitation can be addressed in various ways, such as using a <a href="https://www.postgresql.org/docs/current/sql-createtrigger.html" target="_blank" rel="noopener">trigger</a> to enforce uniqueness on the <code>id</code> column.
However, this goes beyond the scope of this post, so I won’t go into further detail.</p>
</div>
</div>
<div class="sect2">
<h3 id="creating-and-dropping-partitions">Creating and dropping partitions</h3>
<div class="paragraph">
<p>Each day requires a new partition:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">table</span> <span class="n">weather_report_2023_03_21</span>
<span class="k">partition</span> <span class="k">of</span> <span class="n">weather_report</span> <span class="k">for</span> <span class="k">values</span> <span class="k">from</span> <span class="p">(</span><span class="s1">'2023-03-21'</span><span class="p">)</span> <span class="k">to</span> <span class="p">(</span><span class="s1">'2023-03-22'</span><span class="p">);</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The lower bound is inclusive and the upper bound is exclusive.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Deleting weather reports older than 30 days couldn&#8217;t be easier: just drop the oldest partition.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">drop</span> <span class="k">table</span> <span class="n">weather_report_2023_02_19</span><span class="p">;</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>Finding the oldest partition can be automated.
Check out the <a href="https://github.com/gwenneg/blog-postgres-execution-time/blob/main/partitioned-table/sql/init.sql" target="_blank" rel="noopener">gwenneg/blog-postgres-execution-time</a> repository for more details.</td>
</tr>
</table>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>PostgreSQL doesn&#8217;t automatically refresh the parent table&#8217;s statistics or the query planner&#8217;s metadata after dropping a partition.
Run <code>VACUUM ANALYZE</code> on the parent table to update them manually.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="indexing-partitions">Indexing partitions</h3>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>If you create an index on the parent table, PostgreSQL automatically creates local indexes with the same definition on each existing and future partition.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>We already know which indexing strategy performs best with a regular <code>weather_report</code> table (without partitions).
Let&#8217;s reuse it with the partitioned <code>weather_report</code> table:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">create</span> <span class="k">index</span> <span class="n">ix_btree_weather_station_id_received_at_covering</span>
<span class="k">on</span> <span class="n">weather_report</span> <span class="k">using</span> <span class="n">btree</span> <span class="p">(</span><span class="n">weather_station_id</span><span class="p">,</span> <span class="n">received_at</span> <span class="k">desc</span><span class="p">)</span> <span class="n">include</span> <span class="p">(</span><span class="n">id</span><span class="p">,</span> <span class="k">data</span><span class="p">);</span></code></pre>
</div>
</div>
<div class="paragraph">
<p>The partitioned index is similar to the regular index in terms of disk space usage:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql">                           <span class="n">index_name</span>                              <span class="o">|</span> <span class="n">index_size</span>
<span class="c1">-------------------------------------------------------------------+------------</span>
 <span class="n">ix_btree_weather_station_id_received_at_covering</span>                  <span class="o">|</span> <span class="mi">0</span> <span class="n">bytes</span> <i class="conum" data-value="1"></i><b>(1)</b>
 <span class="n">weather_report_2025_02_20_weather_station_id_received_at_id_d_idx</span> <span class="o">|</span> <span class="mi">100</span> <span class="n">MB</span>
 <span class="n">weather_report_2025_02_21_weather_station_id_received_at_id_d_idx</span> <span class="o">|</span> <span class="mi">100</span> <span class="n">MB</span>
 <span class="p">[...]</span>
 <span class="n">weather_report_2025_03_21_weather_station_id_received_at_id_d_idx</span> <span class="o">|</span> <span class="mi">100</span> <span class="n">MB</span> <i class="conum" data-value="2"></i><b>(2)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>This is the index definition that is inherited by each partition.
It’s not an actual index and its size will never grow.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>The total size of the index across all partitions is 3000 MB.</td>
</tr>
</table>
</div>
</div>
<div class="sect2">
<h3 id="performance-with-partitions">Performance with partitions</h3>
<div class="paragraph">
<p>Does partitioning improve query performance?</p>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "fetch" query with partitions</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="k">Limit</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">70</span><span class="p">.</span><span class="mi">01</span><span class="p">..</span><span class="mi">77</span><span class="p">.</span><span class="mi">63</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">408</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">456</span> <span class="k">rows</span><span class="o">=</span><span class="mi">100</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="n">InitPlan</span> <span class="mi">1</span>
     <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">018</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">031</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
   <span class="o">-&gt;</span>  <span class="n">Append</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">6</span><span class="p">.</span><span class="mi">80</span><span class="p">..</span><span class="mi">12198</span><span class="p">.</span><span class="mi">40</span> <span class="k">rows</span><span class="o">=</span><span class="mi">159984</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">065</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">401</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_21_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_21</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">712</span><span class="p">.</span><span class="mi">40</span> <span class="k">rows</span><span class="o">=</span><span class="mi">9999</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">065</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">308</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
               <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_20_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_20</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">712</span><span class="p">.</span><span class="mi">40</span> <span class="k">rows</span><span class="o">=</span><span class="mi">9999</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">never</span> <span class="n">executed</span><span class="p">)</span>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
               <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
         <span class="p">[...]</span> <i class="conum" data-value="1"></i><b>(1)</b>
         <span class="o">-&gt;</span>  <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_06_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_06</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">712</span><span class="p">.</span><span class="mi">40</span> <span class="k">rows</span><span class="o">=</span><span class="mi">9999</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">never</span> <span class="n">executed</span><span class="p">)</span>
               <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
               <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">793</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">574</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The execution plan has been cropped for readability.
The omitted section involves scanning data from 13 additional partitions.</td>
</tr>
</table>
</div>
<div class="listingblock">
<div class="title">Execution plan of the "count" query with partitions</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"> <span class="n">Finalize</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">12242</span><span class="p">.</span><span class="mi">11</span><span class="p">..</span><span class="mi">12242</span><span class="p">.</span><span class="mi">12</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">17</span><span class="p">.</span><span class="mi">946</span><span class="p">..</span><span class="mi">20</span><span class="p">.</span><span class="mi">509</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
   <span class="n">InitPlan</span> <span class="mi">1</span>
     <span class="o">-&gt;</span>  <span class="n">Seq</span> <span class="n">Scan</span> <span class="k">on</span> <span class="n">weather_station</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">00</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">25</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">16</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">025</span><span class="p">..</span><span class="mi">0</span><span class="p">.</span><span class="mi">044</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
           <span class="n">Filter</span><span class="p">:</span> <span class="p">(</span><span class="n">name</span> <span class="o">=</span> <span class="s1">'weather-station-17'</span><span class="p">::</span><span class="nb">text</span><span class="p">)</span>
           <span class="k">Rows</span> <span class="n">Removed</span> <span class="k">by</span> <span class="n">Filter</span><span class="p">:</span> <span class="mi">99</span>
   <span class="o">-&gt;</span>  <span class="n">Gather</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">12239</span><span class="p">.</span><span class="mi">64</span><span class="p">..</span><span class="mi">12239</span><span class="p">.</span><span class="mi">85</span> <span class="k">rows</span><span class="o">=</span><span class="mi">2</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">17</span><span class="p">.</span><span class="mi">825</span><span class="p">..</span><span class="mi">20</span><span class="p">.</span><span class="mi">499</span> <span class="k">rows</span><span class="o">=</span><span class="mi">3</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
         <span class="n">Workers</span> <span class="n">Planned</span><span class="p">:</span> <span class="mi">2</span>
         <span class="n">Workers</span> <span class="n">Launched</span><span class="p">:</span> <span class="mi">2</span>
         <span class="o">-&gt;</span>  <span class="k">Partial</span> <span class="k">Aggregate</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">11239</span><span class="p">.</span><span class="mi">64</span><span class="p">..</span><span class="mi">11239</span><span class="p">.</span><span class="mi">65</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">width</span><span class="o">=</span><span class="mi">8</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">12</span><span class="p">.</span><span class="mi">684</span><span class="p">..</span><span class="mi">12</span><span class="p">.</span><span class="mi">688</span> <span class="k">rows</span><span class="o">=</span><span class="mi">1</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
               <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="n">Append</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">11073</span><span class="p">.</span><span class="mi">00</span> <span class="k">rows</span><span class="o">=</span><span class="mi">66656</span> <span class="n">width</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">045</span><span class="p">..</span><span class="mi">10</span><span class="p">.</span><span class="mi">572</span> <span class="k">rows</span><span class="o">=</span><span class="mi">53333</span> <span class="n">loops</span><span class="o">=</span><span class="mi">3</span><span class="p">)</span>
                     <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_06_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_06</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">671</span><span class="p">.</span><span class="mi">23</span> <span class="k">rows</span><span class="o">=</span><span class="mi">5882</span> <span class="n">width</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">041</span><span class="p">..</span><span class="mi">1</span><span class="p">.</span><span class="mi">431</span> <span class="k">rows</span><span class="o">=</span><span class="mi">10000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
                           <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
                           <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
                     <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_07_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_07</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">671</span><span class="p">.</span><span class="mi">23</span> <span class="k">rows</span><span class="o">=</span><span class="mi">5882</span> <span class="n">width</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">040</span><span class="p">..</span><span class="mi">1</span><span class="p">.</span><span class="mi">434</span> <span class="k">rows</span><span class="o">=</span><span class="mi">10000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
                           <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
                           <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
                     <span class="p">[...]</span> <i class="conum" data-value="1"></i><b>(1)</b>
                     <span class="o">-&gt;</span>  <span class="n">Parallel</span> <span class="k">Index</span> <span class="k">Only</span> <span class="n">Scan</span> <span class="k">using</span> <span class="n">weather_report_2025_03_21_weather_station_id_received_at_id_d_idx</span> <span class="k">on</span> <span class="n">weather_report_2025_03_21</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">42</span><span class="p">..</span><span class="mi">671</span><span class="p">.</span><span class="mi">23</span> <span class="k">rows</span><span class="o">=</span><span class="mi">5882</span> <span class="n">width</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">052</span><span class="p">..</span><span class="mi">2</span><span class="p">.</span><span class="mi">213</span> <span class="k">rows</span><span class="o">=</span><span class="mi">10000</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
                           <span class="k">Index</span> <span class="n">Cond</span><span class="p">:</span> <span class="p">((</span><span class="n">weather_station_id</span> <span class="o">=</span> <span class="p">(</span><span class="n">InitPlan</span> <span class="mi">1</span><span class="p">).</span><span class="n">col1</span><span class="p">)</span> <span class="k">AND</span> <span class="p">(</span><span class="n">received_at</span> <span class="o">&gt;=</span> <span class="s1">'2025-03-06 00:00:00'</span><span class="p">::</span><span class="nb">timestamp</span> <span class="k">without</span> <span class="nb">time</span> <span class="k">zone</span><span class="p">))</span>
                           <span class="n">Heap</span> <span class="n">Fetches</span><span class="p">:</span> <span class="mi">0</span>
 <span class="n">Planning</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">0</span><span class="p">.</span><span class="mi">931</span> <span class="n">ms</span>
 <span class="n">Execution</span> <span class="nb">Time</span><span class="p">:</span> <span class="mi">20</span><span class="p">.</span><span class="mi">670</span> <span class="n">ms</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The execution plan has been cropped for readability.
The omitted section involves scanning data from 13 additional partitions.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Well, partitioning didn&#8217;t really help in our case.
The "fetch" query is slightly slower, although still extremely fast.
The execution time of the "count" query improved a bit - from 22 ms to 20 ms - which may or may not be a meaningful difference.
Execution times can vary between runs of <code>EXPLAIN ANALYZE</code> and only proper <a href="https://www.postgresql.org/docs/current/pgbench.html" target="_blank" rel="noopener">benchmarking</a> will confirm whether this is a real performance gain.</p>
</div>
<div class="paragraph">
<p>That doesn&#8217;t mean partitioning is not worth the effort, but it usually makes sense for larger tables.
In our case, the <code>weather_report</code> table contains only 30 million records which isn&#8217;t quite enough to see real benefits from partitioning.
You might start noticing small performance gains around 100 million records, with more significant improvements as your table grows to several hundred million or even a billion rows.</p>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Partitioning comes with extra complexity, such as dealing with constraints and maintaining partitions and indexes.
Make sure you&#8217;ve explored all indexing strategies before deciding to partition your tables.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
</div>
<div class="sect1">
<h2 id="fine-tuning-statistics">Fine-tuning statistics</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>PostgreSQL uses <a href="https://www.postgresql.org/docs/current/sql-analyze.html" target="_blank" rel="noopener">ANALYZE</a> to collect table <a href="https://www.postgresql.org/docs/current/planner-stats.html" target="_blank" rel="noopener">statistics</a> and help the query planner choose the most efficient way to run queries.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>By default, PostgreSQL analyzes tables using the <a href="https://www.postgresql.org/docs/current/runtime-config-query.html#GUC-DEFAULT-STATISTICS-TARGET" target="_blank" rel="noopener">default_statistics_target</a> setting, which defaults to 100.
You can change this value globally or tweak it for specific columns if needed.
Before you do, keep in mind that <code>ANALYZE</code> samples approximately <code>300 x statistics_target</code> rows.
With the default configuration, PostgreSQL samples around 30,000 rows.</p>
</div>
<div class="paragraph">
<p>Here&#8217;s how statistics can be changed for a specific column:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">alter</span> <span class="k">table</span> <span class="n">weather_report</span>
<span class="k">alter</span> <span class="k">column</span> <span class="n">received_at</span> <span class="k">set</span> <span class="k">statistics</span> <span class="mi">1000</span><span class="p">;</span> <i class="conum" data-value="1"></i><b>(1)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>After this change, <code>ANALYZE</code> will sample approximately 300,000 rows from the <code>weather_report</code> table.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>Increasing statistics on a column can help the query planner generate better execution plans and speed up queries, but it will also make <code>ANALYZE</code> slower.
Consider it when:</p>
</div>
<div class="ulist">
<ul>
<li>
<p>The column has many distinct values (e.g. UUIDs, timestamps).</p>
</li>
<li>
<p>The column is used frequently in <code>WHERE</code> clauses with highly selective filters.</p>
</li>
<li>
<p>The planner misestimates row counts, leading to poor query plans.</p>
</li>
</ul>
</div>
<div class="listingblock">
<div class="title">Misestimation of row counts in an execution plan</div>
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="p">[...]</span>
   <span class="o">-&gt;</span>  <span class="n">Nested</span> <span class="n">Loop</span>  <span class="p">(</span><span class="n">cost</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">56</span><span class="p">..</span><span class="mi">13949593</span><span class="p">.</span><span class="mi">89</span> <span class="k">rows</span><span class="o">=</span><span class="mi">160683</span> <span class="n">width</span><span class="o">=</span><span class="mi">57</span><span class="p">)</span> <span class="p">(</span><span class="n">actual</span> <span class="nb">time</span><span class="o">=</span><span class="mi">0</span><span class="p">.</span><span class="mi">210</span><span class="p">..</span><span class="mi">63</span><span class="p">.</span><span class="mi">221</span> <span class="k">rows</span><span class="o">=</span><span class="mi">900</span> <span class="n">loops</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span> <i class="conum" data-value="1"></i><b>(1)</b>
<span class="p">[...]</span></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>The query planner estimated 160,683 rows but the actual execution only returned 900 rows.</td>
</tr>
</table>
</div>
<div class="admonitionblock tip">
<table>
<tr>
<td class="icon">
<i class="fa icon-tip" title="Tip"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Always run <code>ANALYZE</code> after changing statistics to apply the updates.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="increasing-the-work-memory">Increasing the work memory</h2>
<div class="sectionbody">
<div class="admonitionblock note">
<table>
<tr>
<td class="icon">
<i class="fa icon-note" title="Note"></i>
</td>
<td class="content">
<div class="paragraph">
<p>The <a href="https://www.postgresql.org/docs/current/runtime-config-resource.html" target="_blank" rel="noopener">work memory</a> is the amount of memory PostgreSQL can use for certain operations within a query such as sorting, hashing and aggregations, before spilling data to disk.
Increasing it can improve performance by reducing expensive disk I/O.
The default <code>work_mem</code> setting is 4MB per query operation.</p>
</div>
</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>The work memory can be increased at different levels:</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="k">ALTER</span> <span class="k">SYSTEM</span> <span class="k">SET</span> <span class="n">work_mem</span> <span class="o">=</span> <span class="s1">'128MB'</span><span class="p">;</span> <i class="conum" data-value="1"></i><b>(1)</b>
<span class="k">ALTER</span> <span class="k">ROLE</span> <span class="n">gwenneg</span> <span class="k">SET</span> <span class="n">work_mem</span> <span class="o">=</span> <span class="s1">'128MB'</span><span class="p">;</span> <i class="conum" data-value="2"></i><b>(2)</b>
<span class="k">SET</span> <span class="n">work_mem</span> <span class="o">=</span> <span class="s1">'128MB'</span><span class="p">;</span> <i class="conum" data-value="3"></i><b>(3)</b>
<span class="k">SET</span> <span class="k">LOCAL</span> <span class="n">work_mem</span> <span class="o">=</span> <span class="s1">'128MB'</span><span class="p">;</span> <i class="conum" data-value="4"></i><b>(4)</b></code></pre>
</div>
</div>
<div class="colist arabic">
<table>
<tr>
<td><i class="conum" data-value="1"></i><b>1</b></td>
<td>This permanently changes the work memory for all sessions and queries.
Run <code>SELECT pg_reload_conf();</code> afterward to apply the change.</td>
</tr>
<tr>
<td><i class="conum" data-value="2"></i><b>2</b></td>
<td>This permanently changes the work memory for a specific role or user.</td>
</tr>
<tr>
<td><i class="conum" data-value="3"></i><b>3</b></td>
<td>This changes the work memory for the current session only.</td>
</tr>
<tr>
<td><i class="conum" data-value="4"></i><b>4</b></td>
<td>This changes the work memory for the current transaction only.</td>
</tr>
</table>
</div>
<div class="paragraph">
<p>If you see <code>external merge</code> or <code>disk batches</code> in an execution plan, it means PostgreSQL had to rely on disk instead of keeping operations in memory.
That&#8217;s how you know the work memory could be increased.</p>
</div>
<div class="listingblock">
<div class="content">
<pre class="rouge highlight"><code data-lang="sql"><span class="p">[...]</span>
<span class="n">Sort</span> <span class="k">Method</span><span class="p">:</span> <span class="k">external</span> <span class="n">merge</span>  <span class="n">Disk</span><span class="p">:</span> <span class="mi">10240</span><span class="n">kB</span>
<span class="p">[...]</span>
<span class="n">Hash</span> <span class="k">Join</span>
  <span class="n">Hash</span> <span class="n">Batches</span><span class="p">:</span> <span class="mi">32</span>  <span class="n">Disk</span> <span class="n">Batches</span><span class="p">:</span> <span class="mi">8</span>
<span class="p">[...]</span></code></pre>
</div>
</div>
<div class="admonitionblock warning">
<table>
<tr>
<td class="icon">
<i class="fa icon-warning" title="Warning"></i>
</td>
<td class="content">
<div class="paragraph">
<p>Setting <code>work_mem</code> too high can significantly increase memory usage, especially when multiple queries run in parallel, potentially leading to out-of-memory errors.</p>
</div>
</td>
</tr>
</table>
</div>
</div>
</div>
<div class="sect1">
<h2 id="conclusion">Conclusion</h2>
<div class="sectionbody">
<div class="paragraph">
<p>There are other ways to optimize PostgreSQL query performance.
<a href="https://www.postgresql.org/docs/current/indexes-partial.html" target="_blank" rel="noopener">Partial indexes</a> and tuning <a href="https://www.postgresql.org/docs/current/wal-configuration.html" target="_blank" rel="noopener">WAL settings</a>, for example, can be powerful tools depending on your workload.
But this post should already give you a solid foundation with some of the most impactful techniques.</p>
</div>
<div class="paragraph">
<p>Thanks for reading!
Hopefully, you’ve learned a thing or two that you can apply in your own environment to make your queries faster.
If you’ve got tips or experiences to share, I’d love to hear them!</p>
</div>
<div class="paragraph">
<p>Happy optimizing!</p>
</div>
</div>
</div>]]></content><author><name>Gwenneg Lepage</name></author><category term="execution plan" /><category term="indexing" /><category term="performances" /><category term="postgres" /><category term="sql" /><summary type="html"><![CDATA[PostgreSQL is pretty smart at running queries, but sometimes it needs a little help to hit top speed.]]></summary></entry></feed>